diff --git a/CHANGELOG.md b/CHANGELOG.md
index e924037..1d96bed 100644
--- a/CHANGELOG.md
+++ b/CHANGELOG.md
@@ -11,6 +11,8 @@ Concurrency and scale: a native async client, a lexical/hybrid retrieval path,
per-document TTL, a new framework connector, and a graph data-loss fix.
### Added
+
+- **MCP write tools** (#350) - Added opt-in `dynavec_remember`, `dynavec_get`, and `dynavec_forget` tools, enabled with `dynavec mcp --enable-write`.
- **Native async client** (#270) — `AsyncDynavec` offers `async`/`await` `upsert` / `search` /
`get` / `delete` built on non-blocking I/O, so agent and web workloads can fan out
concurrent calls without thread pools.
diff --git a/README.md b/README.md
index ac70b0d..83ae628 100644
--- a/README.md
+++ b/README.md
@@ -1,643 +1,1331 @@
-# dynavec
-[](https://pypi.org/project/dynavec/)
-[](https://pypi.org/project/dynavec/)
-[](https://github.com/codeforstartups/dynavec/actions/workflows/ci.yml)
-[](https://github.com/codeforstartups/dynavec/blob/development/LICENSE)
-**Serverless, in-your-own-account hybrid vector database on AWS.**
-`dynavec` fuses **Amazon DynamoDB** (single-digit-millisecond metadata + document store) with **Amazon S3 Vectors** (billion-scale, AWS-managed approximate-nearest-neighbor search) into one Python client — a drop-in alternative to Pinecone, Qdrant, Milvus, Weaviate, and OpenSearch that **runs entirely inside your AWS account** and **bills only when you use it**.
-```bash
-# with pip
-pip install dynavec # base: boto3 + numpy only
-pip install "dynavec[openai]" # + OpenAI embedder
-pip install "dynavec[sentence-transformers]" # + local/offline embedder
-pip install "dynavec[all]" # every embedder + framework adapters
-# with uv (installs from the same PyPI index)
+**# dynavec**
+
+
+
+[![PyPI version]\(https\://img.shields.io/pypi/v/dynavec?style=flat-square&color=e8623b&label=release)]\(https\://pypi.org/project/dynavec/)
+
+[![Python versions]\(https\://img.shields.io/badge/python-3.9%20%7C%203.10%20%7C%203.11%20%7C%203.12-3776ab?style=flat-square&logo=python&logoColor=white)]\(https\://pypi.org/project/dynavec/)
+
+[![CI]\(https\://img.shields.io/github/actions/workflow/status/codeforstartups/dynavec/ci.yml?branch=development&style=flat-square&label=CI)]\(https\://github.com/codeforstartups/dynavec/actions/workflows/ci.yml)
+
+[![License]\(https\://img.shields.io/pypi/l/dynavec?style=flat-square&color=green)]\(https\://github.com/codeforstartups/dynavec/blob/development/LICENSE)
+
+
+
+**\*\*Serverless, in-your-own-account hybrid vector database on AWS.\*\***
+
+\`dynavec\` fuses **\*\*Amazon DynamoDB\*\*** (single-digit-millisecond metadata + document store) with **\*\*Amazon S3 Vectors\*\*** (billion-scale, AWS-managed approximate-nearest-neighbor search) into one Python client — a drop-in alternative to Pinecone, Qdrant, Milvus, Weaviate, and OpenSearch that **\*\*runs entirely inside your AWS account\*\*** and **\*\*bills only when you use it\*\***.
+
+
+
+\`\`\`bash
+
+\# with pip
+
+pip install dynavec # base: boto3 + numpy only
+
+pip install "dynavec[openai]" # + OpenAI embedder
+
+pip install "dynavec[sentence-transformers]" # + local/offline embedder
+
+pip install "dynavec[all]" # every embedder + framework adapters
+
+
+
+\# with uv (installs from the same PyPI index)
+
uv add dynavec
+
uv add "dynavec[all]"
-```
-Type hints are included for type checkers such as mypy and pyright.
+\`\`\`
+
+
+
+Type hints are included for type checkers such as mypy and pyright.
+
+
+
+\---
+
+
+
+**## Why dynavec**
+
+
+
+\| Goal | How dynavec delivers it |
+
+\|------|-------------------------|
+
+\| **\*\*Cost-effective\*\*** | No always-on servers, no managed-service premium. You pay S3 Vectors storage/query + DynamoDB on-demand. Idle cost ≈ storage only. |
+
+\| **\*\*Lowest latency\*\*** | ANN keys come from S3 Vectors; the **\*\*actual documents are hydrated from DynamoDB via \`BatchGetItem\` in single-digit ms\*\***. Warm S3 Vectors queries land \~100 ms. |
+
+\| **\*\*Scale\*\*** | S3 Vectors is designed to search across **\*\*billions of vectors\*\*** with 90%+ recall. |
+
+\| **\*\*Data compliance\*\*** | Every byte stays in **\*\*your\*\*** account, **\*\*your\*\*** region, **\*\*your\*\*** AZs. dynavec only ever calls AWS with your credentials. No third-party data plane. |
+
+\| **\*\*Secure / elastic\*\*** | Serverless primitives scale to zero and back automatically; IAM is the only access boundary. |
+
+
+
+**### What dynavec is **_\*not\*_** pretending to be**
+
+
+
+S3 Vectors **\*\*is\*\*** the ANN engine — AWS manages the index internally, so you don't (and can't) choose HNSW vs SPANN vs SPFresh there. dynavec's algorithmic value is the layers **\*\*around\*\*** it that you *\*do\** control: the two-store hybrid design, metadata pre-filtering, **\*\*RRF hybrid fusion\*\***, **\*\*MMR diversity reranking\*\***, namespace/partition routing, and (on the roadmap) an optional in-process \`hnswlib\` **\*\*hot tier\*\*** for sub-10-ms hot-partition queries. See [ARCHITECTURE.md]\(ARCHITECTURE.md).
+
+
+
+\---
+
+
+
+**## Architecture at a glance**
+
+
+
+\`\`\`
+
+ ┌──────────────────────── your AWS account ────────────────────────┐
+
+ upsert ───▶│ Embedder (BYO key: OpenAI / Gemini / Cohere / Bedrock / local) │
+
+ │ │ │
+
+ │ ▼ │
+
+ │ ┌─────────────┐ vector + small filterable metadata │
+
+ │ │ S3 Vectors │◀──────────────────────────────────┐ │
+
+ │ │ (ANN index) │ │ │
+
+ │ └─────────────┘ full text + rich metadata │ │
+
+ │ ┌─────────────┐◀──────────────────────────────────┘ │
+
+ │ │ DynamoDB │ │
+
+ │ │ (documents) │ │
+
+ │ └─────────────┘ │
+
+ │ │
+
+ search ──▶│ 1) query_vectors → keys+distance 2) BatchGetItem → documents │
+
+ │ 3) MMR rerank / RRF hybrid fusion → ranked SearchResults │
+
+ └───────────────────────────────────────────────────────────────────┘
+
+\`\`\`
+
+
+
+\---
+
+
+
+**## Quick start**
+
+
+
+Three steps to your first semantic search — everything runs inside **\*\*your own AWS account\*\***.
+
+
+
+**### 1. Install**
+
+
+
+\`\`\`bash
+
+pip install dynavec # or: uv add dynavec
+
+pip install "dynavec[openai]" # add an embedder extra so dynavec can embed for you
+
+\`\`\`
+
+
+
+**### 2. Grant AWS access**
+
+
+
+dynavec needs an IAM identity with permission for **\*\*Amazon S3 Vectors\*\*** + **\*\*Amazon DynamoDB\*\***. Create an IAM user, attach the policy below, and export its keys (or use an IAM role / profile — see [Provisioning & IAM]\(#provisioning--iam)).
+
+
+
+\`\`\`bash
+
+export AWS_ACCESS_KEY_ID=...
+
+export AWS_SECRET_ACCESS_KEY=...
+
+export AWS_DEFAULT_REGION=us-east-1
+
+\`\`\`
+
+
+
+\
+
+\\Minimum IAM policy\ (click to expand)\
+
+
+
+Replace \`REGION\` and \`ACCOUNT_ID\`. \`dynamodb:Scan\` is only needed for the GraphRAG feature; the \`Create\*\`/\`Delete\*\` actions are only needed for \`auto_provision=True\`.
+
+
+
+\`\`\`json
+
+{
+
+ "Version": "2012-10-17",
+
+ "Statement": [
+
+ {
+
+ "Sid": "DynavecS3Vectors",
+
+ "Effect": "Allow",
+
+ "Action": [
+
+ "s3vectors:CreateVectorBucket", "s3vectors:GetVectorBucket",
+
+ "s3vectors:ListVectorBuckets", "s3vectors:DeleteVectorBucket",
+
+ "s3vectors:CreateIndex", "s3vectors:GetIndex",
+
+ "s3vectors:ListIndexes", "s3vectors:DeleteIndex",
+
+ "s3vectors:PutVectors", "s3vectors:GetVectors",
+
+ "s3vectors:ListVectors", "s3vectors:QueryVectors", "s3vectors:DeleteVectors"
+
+ ],
+
+ "Resource": "\*"
+
+ },
+
+ {
+
+ "Sid": "DynavecDynamoDB",
+
+ "Effect": "Allow",
+
+ "Action": [
+
+ "dynamodb:CreateTable", "dynamodb:DescribeTable", "dynamodb:DeleteTable",
+
+ "dynamodb:BatchWriteItem", "dynamodb:BatchGetItem",
+
+ "dynamodb:PutItem", "dynamodb:GetItem", "dynamodb:UpdateItem",
+
+ "dynamodb:DeleteItem", "dynamodb:Query", "dynamodb:Scan",
+
+ "dynamodb:DescribeTimeToLive", "dynamodb:UpdateTimeToLive"
+
+ ],
+
+ "Resource": [
+
+ "arn:aws:dynamodb:REGION:ACCOUNT_ID:table/dynavec\_\*",
+
+ "arn:aws:dynamodb:REGION:ACCOUNT_ID:table/dynavec\_\*/index/\*"
+
+ ]
+
+ }
+
+ ]
+
+}
+
+\`\`\`
+
+
+
+\
+
+
+
+**### 3. Run your first query**
+
+
+
+\`\`\`python
+
+from dynavec import Dynavec, DynavecConfig, Document
+
+from dynavec.embeddings import OpenAIEmbedder # or Gemini / Bedrock / SentenceTransformer
+
+
+
+cfg = DynavecConfig(
+
+ vector_bucket="my-vectors", # S3 vector bucket
+
+ index="docs", # vector index
+
+ table="dynavec_docs", # DynamoDB table
+
+ dimension=1536,
+
+ distance_metric="cosine",
+
+ region="us-east-1",
+
+ auto_provision=True, # create bucket + index + table if missing
+
+)
+
+
+
+db = Dynavec(cfg, embedder=OpenAIEmbedder(model="text-embedding-3-small"))
+
+
+
+db.upsert(
+
+ [
+
+ Document(id="a", text="The mitochondria is the powerhouse of the cell.",
+
+ metadata={"topic": "biology", "year": 2021}),
+
+ Document(id="b", text="Rockets reach orbit at roughly 28,000 km/h.",
+
+ metadata={"topic": "space", "year": 2023}),
+
+ ],
+
+ auto_metadata=True, # also attach hash/timestamp/word counts
+
+)
+
+
+
+hits = db.search(
+
+ "how do cells make energy?",
+
+ top_k=3,
+
+ filter={"topic": "biology"}, # S3 Vectors metadata pre-filter
+
+ rerank="mmr", # diversity-aware reranking
+
+)
+
+for h in hits:
+
+ print(h.score, h.id, h.text)
+
+\`\`\`
+
+
+
+\`search()\` returns a list of hits by default. Pass \`explain=True\` to receive an
+
+\`ExplainedSearchResult\` containing those hits plus timing and candidate-count
+
+details; the type annotations distinguish the two return shapes.
+
+
+
+**### Bring your own vectors (no embedder needed)**
+
+
+
+\`\`\`python
+
+db = Dynavec(cfg) # no embedder
+
+db.upsert([Document(id="x", vector=my_1536_dim_vector, metadata={"lang": "en"})])
+
+hits = db.search(vector=my_query_vector, top_k=5)
+
+\`\`\`
+
+
+
+**### The metadata switch**
+
+
+
+\- **\*\*You provide metadata\*\*** → stored verbatim (full copy in DynamoDB, filterable subset in S3 Vectors).
+
+\- **\*\*\`auto_metadata=True\`\*\*** → dynavec also derives \`created_at\`, \`content_hash\`, \`word_count\`, \`char_count\`. Your keys always win on conflict.
+
+
+
+Control the split with \`DynavecConfig.filterable_keys\` (allowlist of keys pushed to S3 Vectors for filtering) — keep it small; S3 Vectors caps filterable metadata size per vector.
+
+
+
+**### Per-document TTL & automatic expiry**
+
+
+
+Expire ephemeral documents, session memories, or cache entries automatically via DynamoDB's native Time To Live (TTL):
+
+
+
+\`\`\`python
+
+\# Pass ttl_seconds on Document or upsert()
+
+db.upsert([
+
+ Document(id="session-1", text="Temporary session context", ttl_seconds=3600),
+
+ Document(id="cached-doc", text="Ephemeral cache data", ttl_seconds=86400),
+
+])
+
+
+
+\# Or set a default TTL across an entire batch
+
+ns = db.namespace("sessions")
+
+ns.upsert([Document(id="a", text="..."), Document(id="b", text="...")], ttl_seconds=1800)
+
+\`\`\`
+
+
+
+Dynavec automatically computes the Unix epoch timestamp, stores it in the DynamoDB \`ttl\` attribute, and enables TTL on the table during provisioning (\`auto_provision=True\` or \`provision_all\`).
+
+
+
+\---
+
+
+
+**## Framework integrations**
+
+
+
+**### LangChain**
+
+
+
+\`\`\`python
+
+from dynavec.integrations.langchain import DynavecVectorStore
+
+
+
+store = DynavecVectorStore(db, namespace="kb")
+
+retriever = store.as_retriever(search_kwargs={"k": 4})
+
+\`\`\`
+
+
+
+**### FastMCP Server (Claude Desktop, Cursor, AI agents)**
+
+
+
+Expose \`dynavec_search\` and \`dynavec_graph_search\` tools to any MCP client over stdio:
+
+
+
+\`\`\`bash
+
+\# Launch MCP server from environment variables
+
+dynavec mcp
+
+\`\`\`
+
+
+
+\`\`\`json
+
+{
+
+ "mcpServers": {
+
+ "dynavec": {
+
+ "command": "uvx",
+
+ "args": ["--with", "dynavec[all]", "dynavec", "mcp"],
+
+ "env": {
+
+ "AWS_ACCESS_KEY_ID": "AKIA...",
+
+ "AWS_SECRET_ACCESS_KEY": "...",
+
+ "AWS_REGION": "us-east-1",
+
+ "OPENAI_API_KEY": "sk-...",
+
+ "DYNAVEC_VECTOR_BUCKET": "my-vectors",
+
+ "DYNAVEC_INDEX": "docs",
+
+ "DYNAVEC_TABLE": "dynavec_docs"
+
+ }
+
+ }
+
+ }
+
+}
+
+\`\`\`
+
+
+
+**### Opt-in memory tools**
+
+
+
+Dynavec includes three additional MCP tools for managing stored documents:
+
+
+
+- **\`dynavec_remember\`** — store a document, optionally with an ID, metadata, namespace, and TTL.
+- **\`dynavec_get\`** — retrieve documents by ID.
+- **\`dynavec_forget\`** — delete documents by ID.
+
+
+
+These memory tools are **disabled by default**. Enable them explicitly when starting the MCP server:
+
+
+
+\`\`\`bash
+
+dynavec mcp --enable-write
+
+\`\`\`
+
+
+
+For SSE transport, include the same flag alongside the transport options:
+
+
+
+\`\`\`bash
+
+dynavec mcp --transport sse --port 8000 --enable-write
+
+\`\`\`
+
+
+
+Only enable write access when you trust the MCP clients connected to the server. The flag exposes document storage and deletion tools to those clients.
+
+
+
+**### Strands Agents**
+
+
+
+Use the framework-agnostic \`make_retriever_fn\` as a native Strands tool:
+
+
+
+\`\`\`bash
+
+pip install "dynavec[sentence-transformers]" strands-agents
+
+\`\`\`
+
+
+
+\`\`\`python
+
+from strands import Agent, tool
+
+
+
+from dynavec.integrations.tools import make_retriever_fn
+
+
+
+retrieve = make_retriever_fn(db, namespace="kb", top_k=2)
+
+
+
+@tool
+
+def search_knowledge_base(query: str) -> str:
+
+ """Search the dynavec knowledge base for relevant passages."""
+
+ return retrieve(query)
+
+
+
+agent = Agent(tools=[search_knowledge_base])
+
+agent("Where is dynavec vector data stored?")
+
+\`\`\`
+
+
+
+See [\`examples/strands_retriever.py\`]\(examples/strands_retriever.py) for a complete example that provisions a database and indexes sample documents. LlamaIndex integration remains on the roadmap; the core client works in any agent framework today.
+
+
+
+\---
+
+
+
+**## Query expansion: Multi-Query and HyDE**
+
+
+
+Single-query vector search frequently misses relevant documents when queries are short, colloquial, or use different terminology than the corpus. Dynavec provides two first-class query expansion adapters:
+
+
+
+**### MultiQueryRetriever**
+
+Expands a user query into diverse reformulations using an LLM, fans out searches concurrently, and merges results via Reciprocal Rank Fusion (RRF):
+
+
+
+\`\`\`python
+
+from dynavec import MultiQueryRetriever
+
+
+
+retriever = MultiQueryRetriever(
+
+ db.namespace("docs"),
+
+ generate_queries=lambda q: my_llm.generate_variations(q, n=3),
+
+ top_k=4,
+
+)
+
+hits = retriever.search("car won't start")
+
+\`\`\`
+
+
+
+**### HyDERetriever**
+
+Hypothetical Document Embeddings (HyDE) asks an LLM to generate an answer passage, embeds it as a document (via \`embed_documents\`), and retrieves nearest neighbours. Supports single-passage or multi-passage Centroid averaging (\`strategy="average"\`) and multi-search fusion (\`strategy="fuse"\`):
+
+
+
+\`\`\`python
+
+from dynavec import HyDERetriever
+
+
+
+hyde = HyDERetriever(
+
+ db.namespace("docs"),
+
+ generate_hypothetical=lambda q: my_llm.generate_answer(q),
+
+ top_k=4,
+
+ strategy="average",
+
+ include_original=True,
+
+)
+
+hits = hyde.search("explain dynamo db storage pricing breakdown")
+
+\`\`\`
+
+
+
+You can also instantiate retrievers directly via \`db.as_multiquery_retriever(...)\` or \`db.namespace("docs").as_hyde_retriever(...)\`.
+
+
+
+\---
+
+
+
+**## Choosing an embedding dimension**
+
+
+
+Embedding dimension trades off recall against storage cost and latency. A larger dimension usually gives higher recall, but the right choice is the **\*\*smallest dimension that meets your recall target\*\*** — not the largest. See [EMBEDDING_DIMENSIONS.md]\(docs/EMBEDDING_DIMENSIONS.md) for a comparison table, the S3 Vectors 4096-dim ceiling, and a step-by-step picking guide.
+
+
+
+\---
+
+
+
+**## Namespaces & multi-tenancy**
+
+
+
+Every write/read takes a \`namespace\`. dynavec tags each vector with its namespace and scopes queries to it automatically, so a single index can host many tenants (or many embedding "collections") with clean isolation. DynamoDB keys use escaped \`"{namespace}#{id}"\` components for even partition distribution, so \`#\` in namespaces, document IDs, and graph entity IDs remains unambiguous.
+
+
+
+\---
+
+
+
+**## Provisioning & IAM**
+
+
+
+\`auto_provision=True\` (or \`db.provision()\`) creates the S3 vector bucket, the vector index, and the DynamoDB table idempotently. The caller needs \`s3vectors:\*\` on the bucket/index and \`dynamodb:\*\` on the table (scope these down in production — see [ARCHITECTURE.md]\(ARCHITECTURE.md)). For supported AWS regions and regional configuration, see [REGIONS.md]\(docs/REGIONS.md).
+
+
+
+**### Inspecting what's provisioned**
+
+
+
+\`db.describe()\` returns an \`IndexInfo\` dataclass with the live bucket/index/table
+
+config — dimension, distance metric, non-filterable metadata keys, and the
+
+DynamoDB table's status and item count. Useful for a quick sanity check after
+
+\`provision()\`, or for debugging a dimension-mismatch in production.
+
+
+
+\`\`\`python
+
+info = db.describe()
+
+print(info.dimension, info.distance_metric, info.table_status)
+
+\`\`\`
+
+
+
+\---
+
+
+
+**## Benchmarks**
+
+
+
+\`benchmarks/\` measures recall\@k, latency (p50/p95/p99), and estimated \\$/month, with a cost model comparing dynavec to Pinecone / Qdrant / Milvus / Weaviate / OpenSearch. See [benchmarks/README.md]\(benchmarks/README.md).
+
+
+
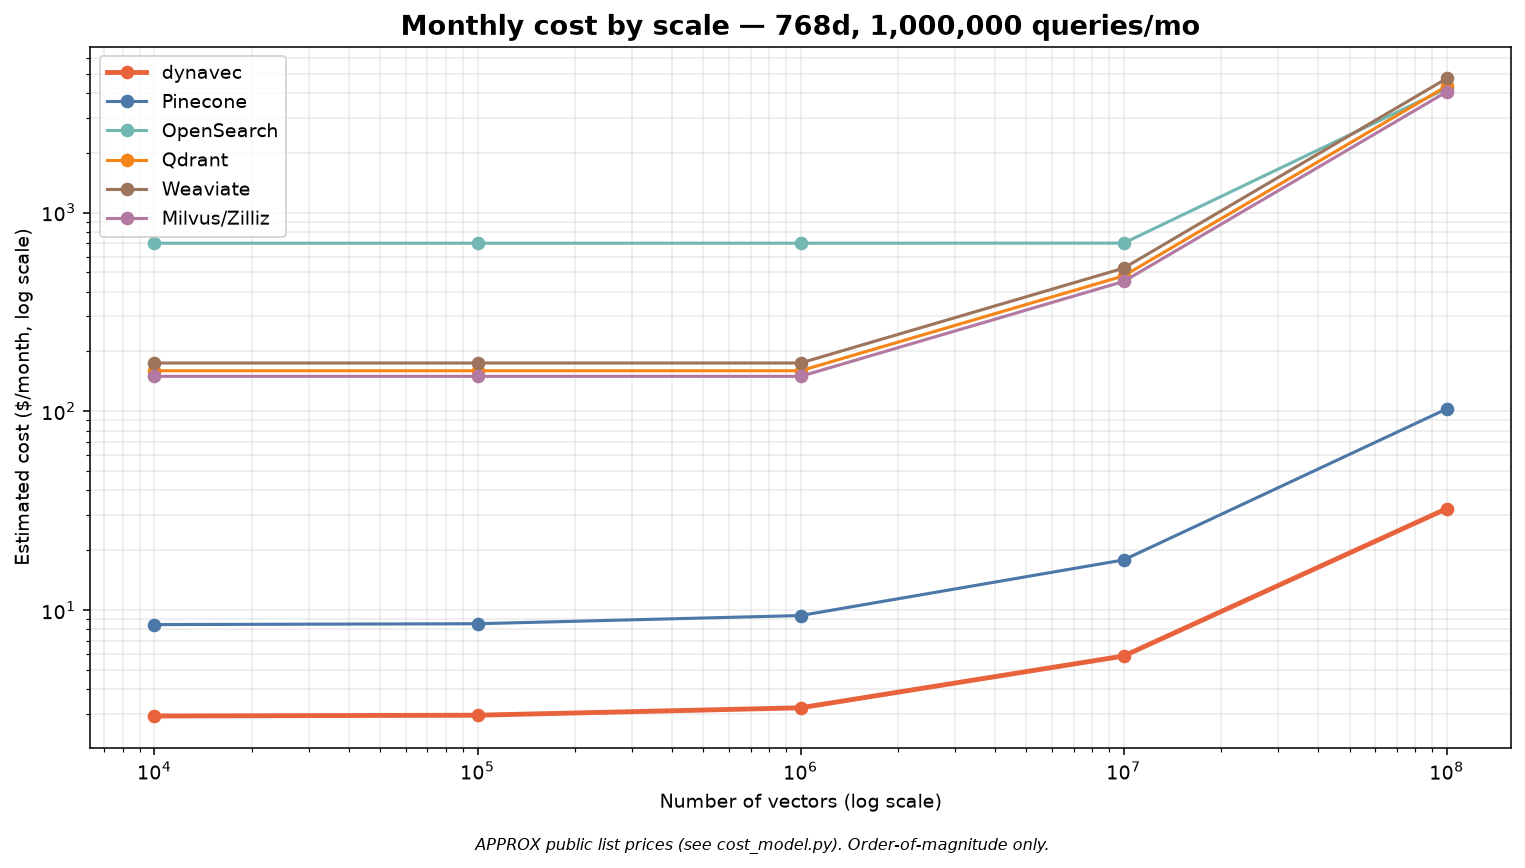
+**### Cost by scale**
+
+
+
+dynavec has **\*\*no idle floor\*\*** — you pay storage + per-request, so it stays far below cluster- and OCU-based systems, and tracks serverless Pinecone while keeping your data in-account.
+
+
+
+![Monthly cost by scale]\(https\://raw\.githubusercontent.com/codeforstartups/dynavec/development/docs/assets/cost_by_scale.png)
+
+
+
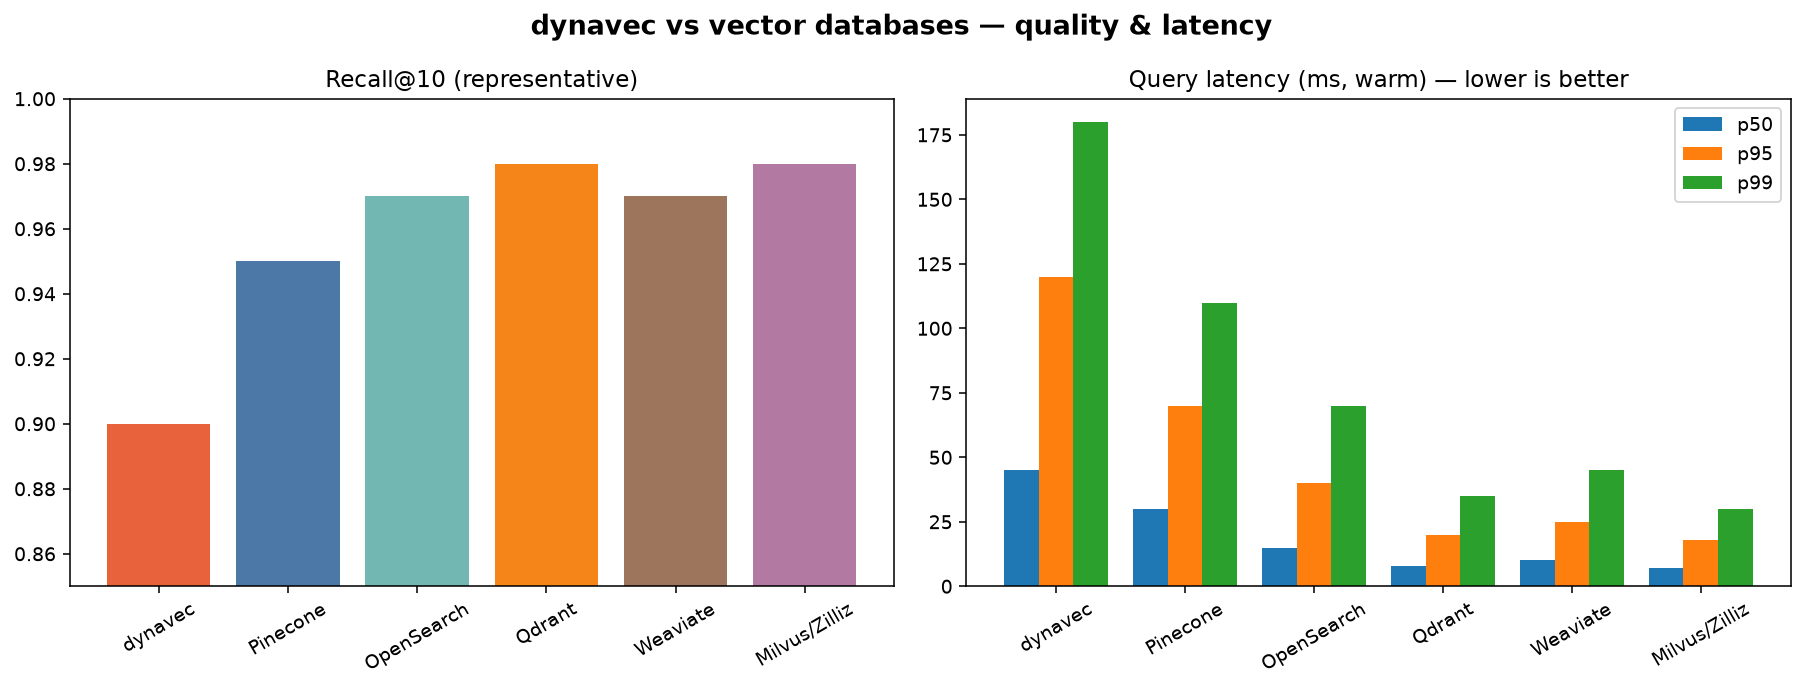
+**### Quality & latency**
+
+
+
+![Recall and latency]\(https\://raw\.githubusercontent.com/codeforstartups/dynavec/development/docs/assets/quality_latency.png)
+
+
+
+**### Comparison (1M × 768d, 1M queries/mo)**
+
+
+
+\| Metric | dynavec | Pinecone | OpenSearch | Qdrant | Weaviate | Milvus/Zilliz |
+
+\|---|---|---|---|---|---|---|
+
+\| Recall\@10 | 0.90 | 0.95 | 0.97 | **\*\*0.98\*\*** | 0.97 | 0.98 |
+
+\| Latency p50 (ms) | 45 | 30 | 15 | 8 | 10 | **\*\*7\*\*** |
+
+\| Latency p95 (ms) | 120 | 70 | 40 | 20 | 25 | **\*\*18\*\*** |
+
+\| Cost ($/mo) | **\*\*$3\*\*** | $9 | $701 | $160 | $175 | $150 |
+
+\| Serverless (scale-to-zero) | Yes | Yes | No (OCU floor) | No (nodes) | No (nodes) | No (CU) |
+
+\| Data in your AWS account | Yes | No | Yes | Self-host only | Self-host only | Self-host only |
+
+
+
+\> **\*\*Honesty note:\*\*** the **\*\*cost\*\*** row is computed by the repo's cost model from public list prices (order-of-magnitude; verify before quoting). **\*\*Recall/latency\*\*** are representative figures pending a live AWS run — regenerate real numbers with the commands below.
+
+
+
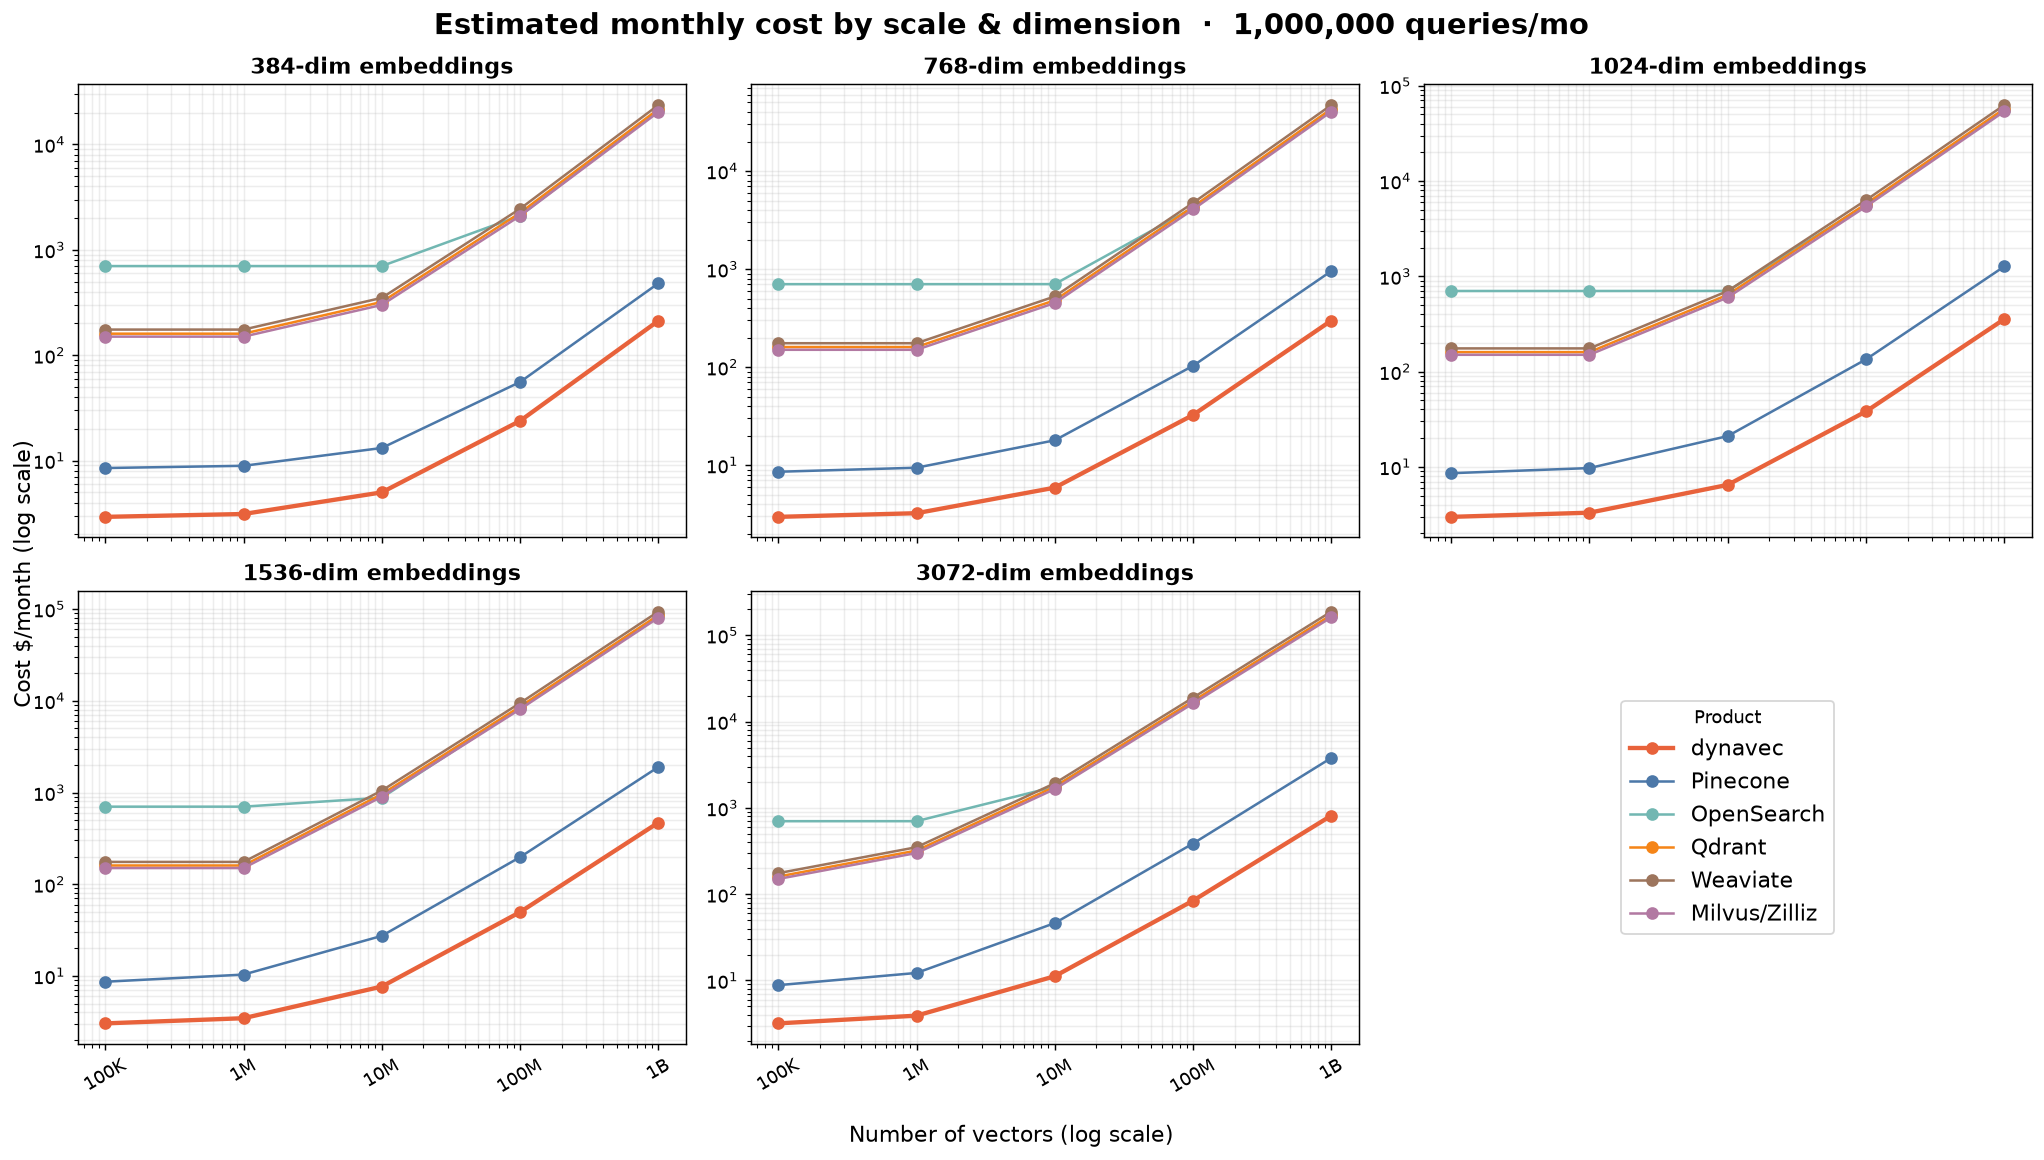
+**### Scaling: every embedding dimension, 100K → 1 billion vectors**
+
+
+
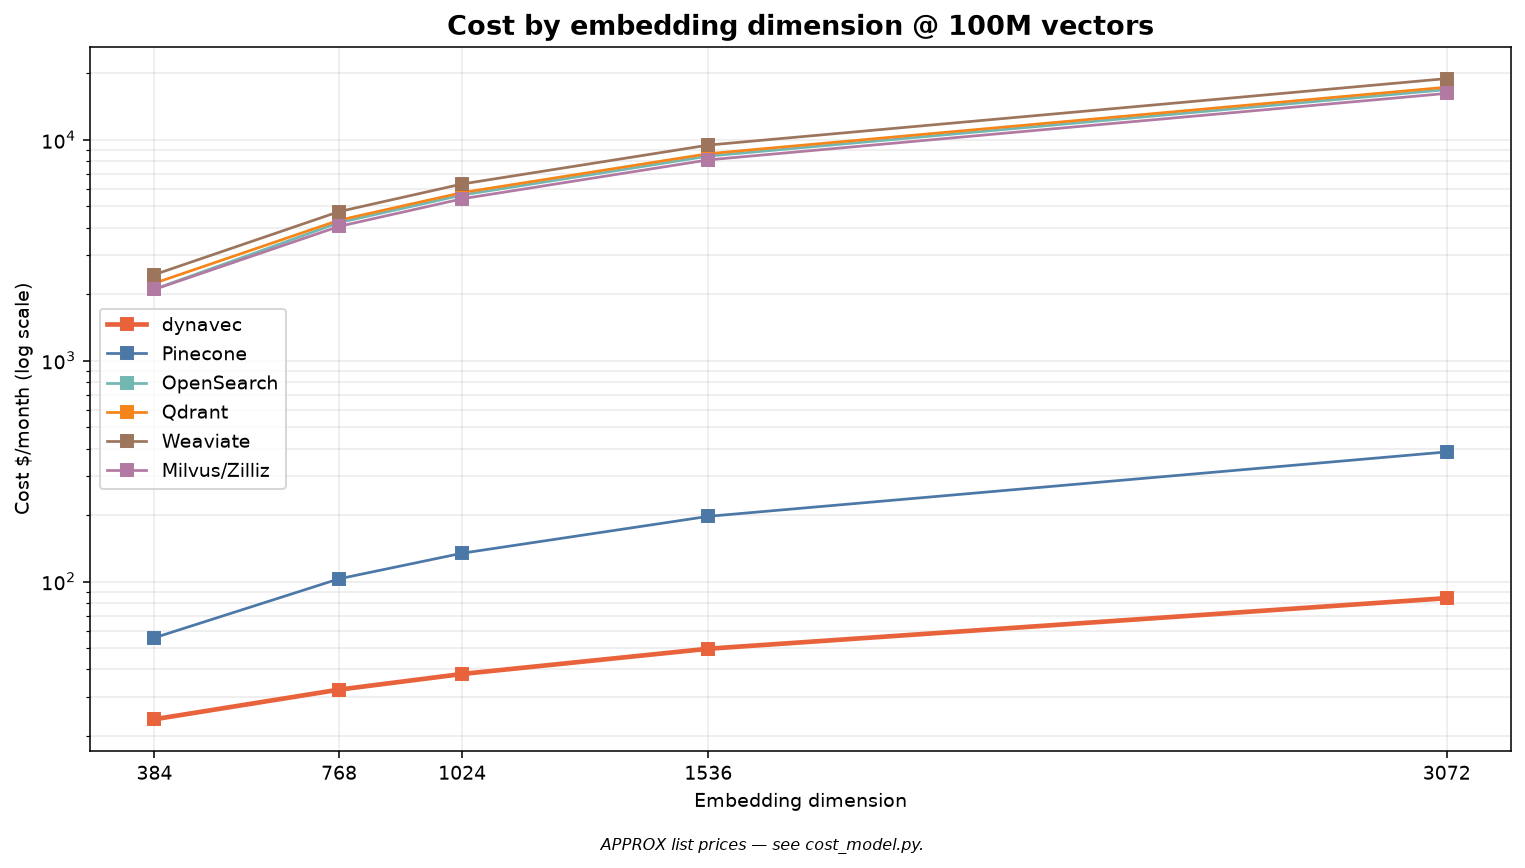
+Cost across the common embedding dimensions (384 / 768 / 1024 / 1536 / 3072) and the full scale ladder. dynavec stays lowest at **\*\*every\*\*** point because its storage is priced like S3, not RAM — while cluster/OCU systems grow linearly with data held in memory.
+
+
+
+![Cost by scale and dimension]\(https\://raw\.githubusercontent.com/codeforstartups/dynavec/development/docs/assets/cost_matrix_by_dim.png)
+
+
+
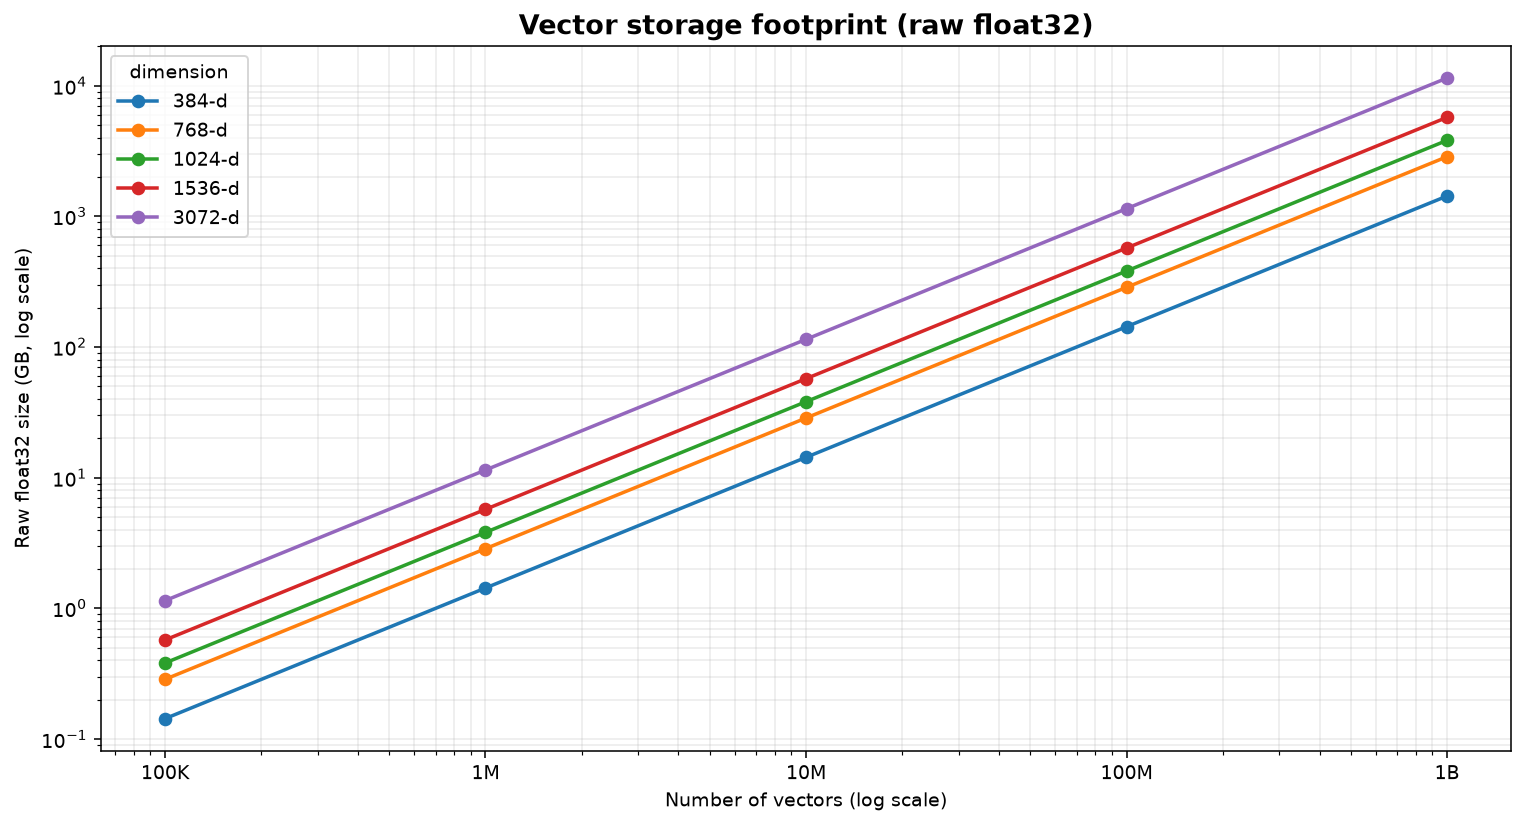
+\| | Cost by dimension @ 100M vectors | Raw storage footprint |
----
+\|---|---|---|
-## Why dynavec
+\| | ![Cost by dimension]\(https\://raw\.githubusercontent.com/codeforstartups/dynavec/development/docs/assets/cost_by_dimension.png) | ![Storage footprint]\(https\://raw\.githubusercontent.com/codeforstartups/dynavec/development/docs/assets/storage_footprint.png) |
-| Goal | How dynavec delivers it |
-|------|-------------------------|
-| **Cost-effective** | No always-on servers, no managed-service premium. You pay S3 Vectors storage/query + DynamoDB on-demand. Idle cost ≈ storage only. |
-| **Lowest latency** | ANN keys come from S3 Vectors; the **actual documents are hydrated from DynamoDB via `BatchGetItem` in single-digit ms**. Warm S3 Vectors queries land ~100 ms. |
-| **Scale** | S3 Vectors is designed to search across **billions of vectors** with 90%+ recall. |
-| **Data compliance** | Every byte stays in **your** account, **your** region, **your** AZs. dynavec only ever calls AWS with your credentials. No third-party data plane. |
-| **Secure / elastic** | Serverless primitives scale to zero and back automatically; IAM is the only access boundary. |
-### What dynavec is *not* pretending to be
-S3 Vectors **is** the ANN engine — AWS manages the index internally, so you don't (and can't) choose HNSW vs SPANN vs SPFresh there. dynavec's algorithmic value is the layers **around** it that you *do* control: the two-store hybrid design, metadata pre-filtering, **RRF hybrid fusion**, **MMR diversity reranking**, namespace/partition routing, and (on the roadmap) an optional in-process `hnswlib` **hot tier** for sub-10-ms hot-partition queries. See [ARCHITECTURE.md](ARCHITECTURE.md).
+**\*\*1536-dim (e.g. OpenAI \`text-embedding-3-small\`) — $/month @ 1M queries/mo:\*\***
----
-## Architecture at a glance
-```
- ┌──────────────────────── your AWS account ────────────────────────┐
- upsert ───▶│ Embedder (BYO key: OpenAI / Gemini / Cohere / Bedrock / local) │
- │ │ │
- │ ▼ │
- │ ┌─────────────┐ vector + small filterable metadata │
- │ │ S3 Vectors │◀──────────────────────────────────┐ │
- │ │ (ANN index) │ │ │
- │ └─────────────┘ full text + rich metadata │ │
- │ ┌─────────────┐◀──────────────────────────────────┘ │
- │ │ DynamoDB │ │
- │ │ (documents) │ │
- │ └─────────────┘ │
- │ │
- search ──▶│ 1) query_vectors → keys+distance 2) BatchGetItem → documents │
- │ 3) MMR rerank / RRF hybrid fusion → ranked SearchResults │
- └───────────────────────────────────────────────────────────────────┘
-```
+\| Product | 100K | 1M | 10M | 100M | 1B |
----
+\|---|---|---|---|---|---|
-## Quick start
+\| **\*\*dynavec\*\*** | **\*\*$3\*\*** | **\*\*$3\*\*** | **\*\*$8\*\*** | **\*\*$50\*\*** | **\*\*$469\*\*** |
-Three steps to your first semantic search — everything runs inside **your own AWS account**.
+\| Pinecone | $9 | $10 | $27 | $197 | $1,897 |
-### 1. Install
+\| OpenSearch | $701 | $701 | $877 | $8,423 | $83,708 |
-```bash
-pip install dynavec # or: uv add dynavec
-pip install "dynavec[openai]" # add an embedder extra so dynavec can embed for you
-```
+\| Qdrant | $160 | $160 | $960 | $8,640 | $85,920 |
-### 2. Grant AWS access
+\| Weaviate | $175 | $175 | $1,050 | $9,450 | $93,975 |
-dynavec needs an IAM identity with permission for **Amazon S3 Vectors** + **Amazon DynamoDB**. Create an IAM user, attach the policy below, and export its keys (or use an IAM role / profile — see [Provisioning & IAM](#provisioning--iam)).
+\| Milvus/Zilliz | $150 | $150 | $900 | $8,100 | $80,550 |
-```bash
-export AWS_ACCESS_KEY_ID=...
-export AWS_SECRET_ACCESS_KEY=...
-export AWS_DEFAULT_REGION=us-east-1
-```
+\| *\_raw float32 size\_* | 1 GB | 6 GB | 57 GB | 572 GB | 5,722 GB |
-
-Minimum IAM policy (click to expand)
-Replace `REGION` and `ACCOUNT_ID`. `dynamodb:Scan` is only needed for the GraphRAG feature; the `Create*`/`Delete*` actions are only needed for `auto_provision=True`.
-```json
-{
- "Version": "2012-10-17",
- "Statement": [
- {
- "Sid": "DynavecS3Vectors",
- "Effect": "Allow",
- "Action": [
- "s3vectors:CreateVectorBucket", "s3vectors:GetVectorBucket",
- "s3vectors:ListVectorBuckets", "s3vectors:DeleteVectorBucket",
- "s3vectors:CreateIndex", "s3vectors:GetIndex",
- "s3vectors:ListIndexes", "s3vectors:DeleteIndex",
- "s3vectors:PutVectors", "s3vectors:GetVectors",
- "s3vectors:ListVectors", "s3vectors:QueryVectors", "s3vectors:DeleteVectors"
- ],
- "Resource": "*"
- },
- {
- "Sid": "DynavecDynamoDB",
- "Effect": "Allow",
- "Action": [
- "dynamodb:CreateTable", "dynamodb:DescribeTable", "dynamodb:DeleteTable",
- "dynamodb:BatchWriteItem", "dynamodb:BatchGetItem",
- "dynamodb:PutItem", "dynamodb:GetItem", "dynamodb:UpdateItem",
- "dynamodb:DeleteItem", "dynamodb:Query", "dynamodb:Scan",
- "dynamodb:DescribeTimeToLive", "dynamodb:UpdateTimeToLive"
- ],
- "Resource": [
- "arn:aws:dynamodb:REGION:ACCOUNT_ID:table/dynavec_*",
- "arn:aws:dynamodb:REGION:ACCOUNT_ID:table/dynavec_*/index/*"
- ]
- }
- ]
-}
-```
+Full tables for all five dimensions: [scaling.md]\(https\://github.com/codeforstartups/dynavec/blob/development/docs/assets/scaling.md). At 1B × 1536-d that's \~5.7 TB of raw vectors — where dynavec's product quantization and the S3-priced tier matter most.
-
-### 3. Run your first query
-```python
-from dynavec import Dynavec, DynavecConfig, Document
-from dynavec.embeddings import OpenAIEmbedder # or Gemini / Bedrock / SentenceTransformer
+\`\`\`bash
-cfg = DynavecConfig(
- vector_bucket="my-vectors", # S3 vector bucket
- index="docs", # vector index
- table="dynavec_docs", # DynamoDB table
- dimension=1536,
- distance_metric="cosine",
- region="us-east-1",
- auto_provision=True, # create bucket + index + table if missing
-)
+pip install "dynavec[benchmark]" # or: uv add "dynavec[benchmark]"
-db = Dynavec(cfg, embedder=OpenAIEmbedder(model="text-embedding-3-small"))
-db.upsert(
- [
- Document(id="a", text="The mitochondria is the powerhouse of the cell.",
- metadata={"topic": "biology", "year": 2021}),
- Document(id="b", text="Rockets reach orbit at roughly 28,000 km/h.",
- metadata={"topic": "space", "year": 2023}),
- ],
- auto_metadata=True, # also attach hash/timestamp/word counts
-)
-hits = db.search(
- "how do cells make energy?",
- top_k=3,
- filter={"topic": "biology"}, # S3 Vectors metadata pre-filter
- rerank="mmr", # diversity-aware reranking
-)
-for h in hits:
- print(h.score, h.id, h.text)
-```
+\# reproduce the charts + table above
-`search()` returns a list of hits by default. Pass `explain=True` to receive an
-`ExplainedSearchResult` containing those hits plus timing and candidate-count
-details; the type annotations distinguish the two return shapes.
+python -m benchmarks.report --vectors 1_000_000 --dim 768 --qpm 1_000_000
-### Bring your own vectors (no embedder needed)
-```python
-db = Dynavec(cfg) # no embedder
-db.upsert([Document(id="x", vector=my_1536_dim_vector, metadata={"lang": "en"})])
-hits = db.search(vector=my_query_vector, top_k=5)
-```
-### The metadata switch
+\# measure real recall + latency against your own AWS account
-- **You provide metadata** → stored verbatim (full copy in DynamoDB, filterable subset in S3 Vectors).
-- **`auto_metadata=True`** → dynavec also derives `created_at`, `content_hash`, `word_count`, `char_count`. Your keys always win on conflict.
+python -m benchmarks.run_benchmark --backend dynavec \\
-Control the split with `DynavecConfig.filterable_keys` (allowlist of keys pushed to S3 Vectors for filtering) — keep it small; S3 Vectors caps filterable metadata size per vector.
+ --bucket my-vectors --index bench --table dynavec_bench --n 100000 --dim 768
-### Per-document TTL & automatic expiry
+\`\`\`
-Expire ephemeral documents, session memories, or cache entries automatically via DynamoDB's native Time To Live (TTL):
-```python
-# Pass ttl_seconds on Document or upsert()
-db.upsert([
- Document(id="session-1", text="Temporary session context", ttl_seconds=3600),
- Document(id="cached-doc", text="Ephemeral cache data", ttl_seconds=86400),
-])
-# Or set a default TTL across an entire batch
-ns = db.namespace("sessions")
-ns.upsert([Document(id="a", text="..."), Document(id="b", text="...")], ttl_seconds=1800)
-```
+\---
-Dynavec automatically computes the Unix epoch timestamp, stores it in the DynamoDB `ttl` attribute, and enables TTL on the table during provisioning (`auto_provision=True` or `provision_all`).
----
-## Framework integrations
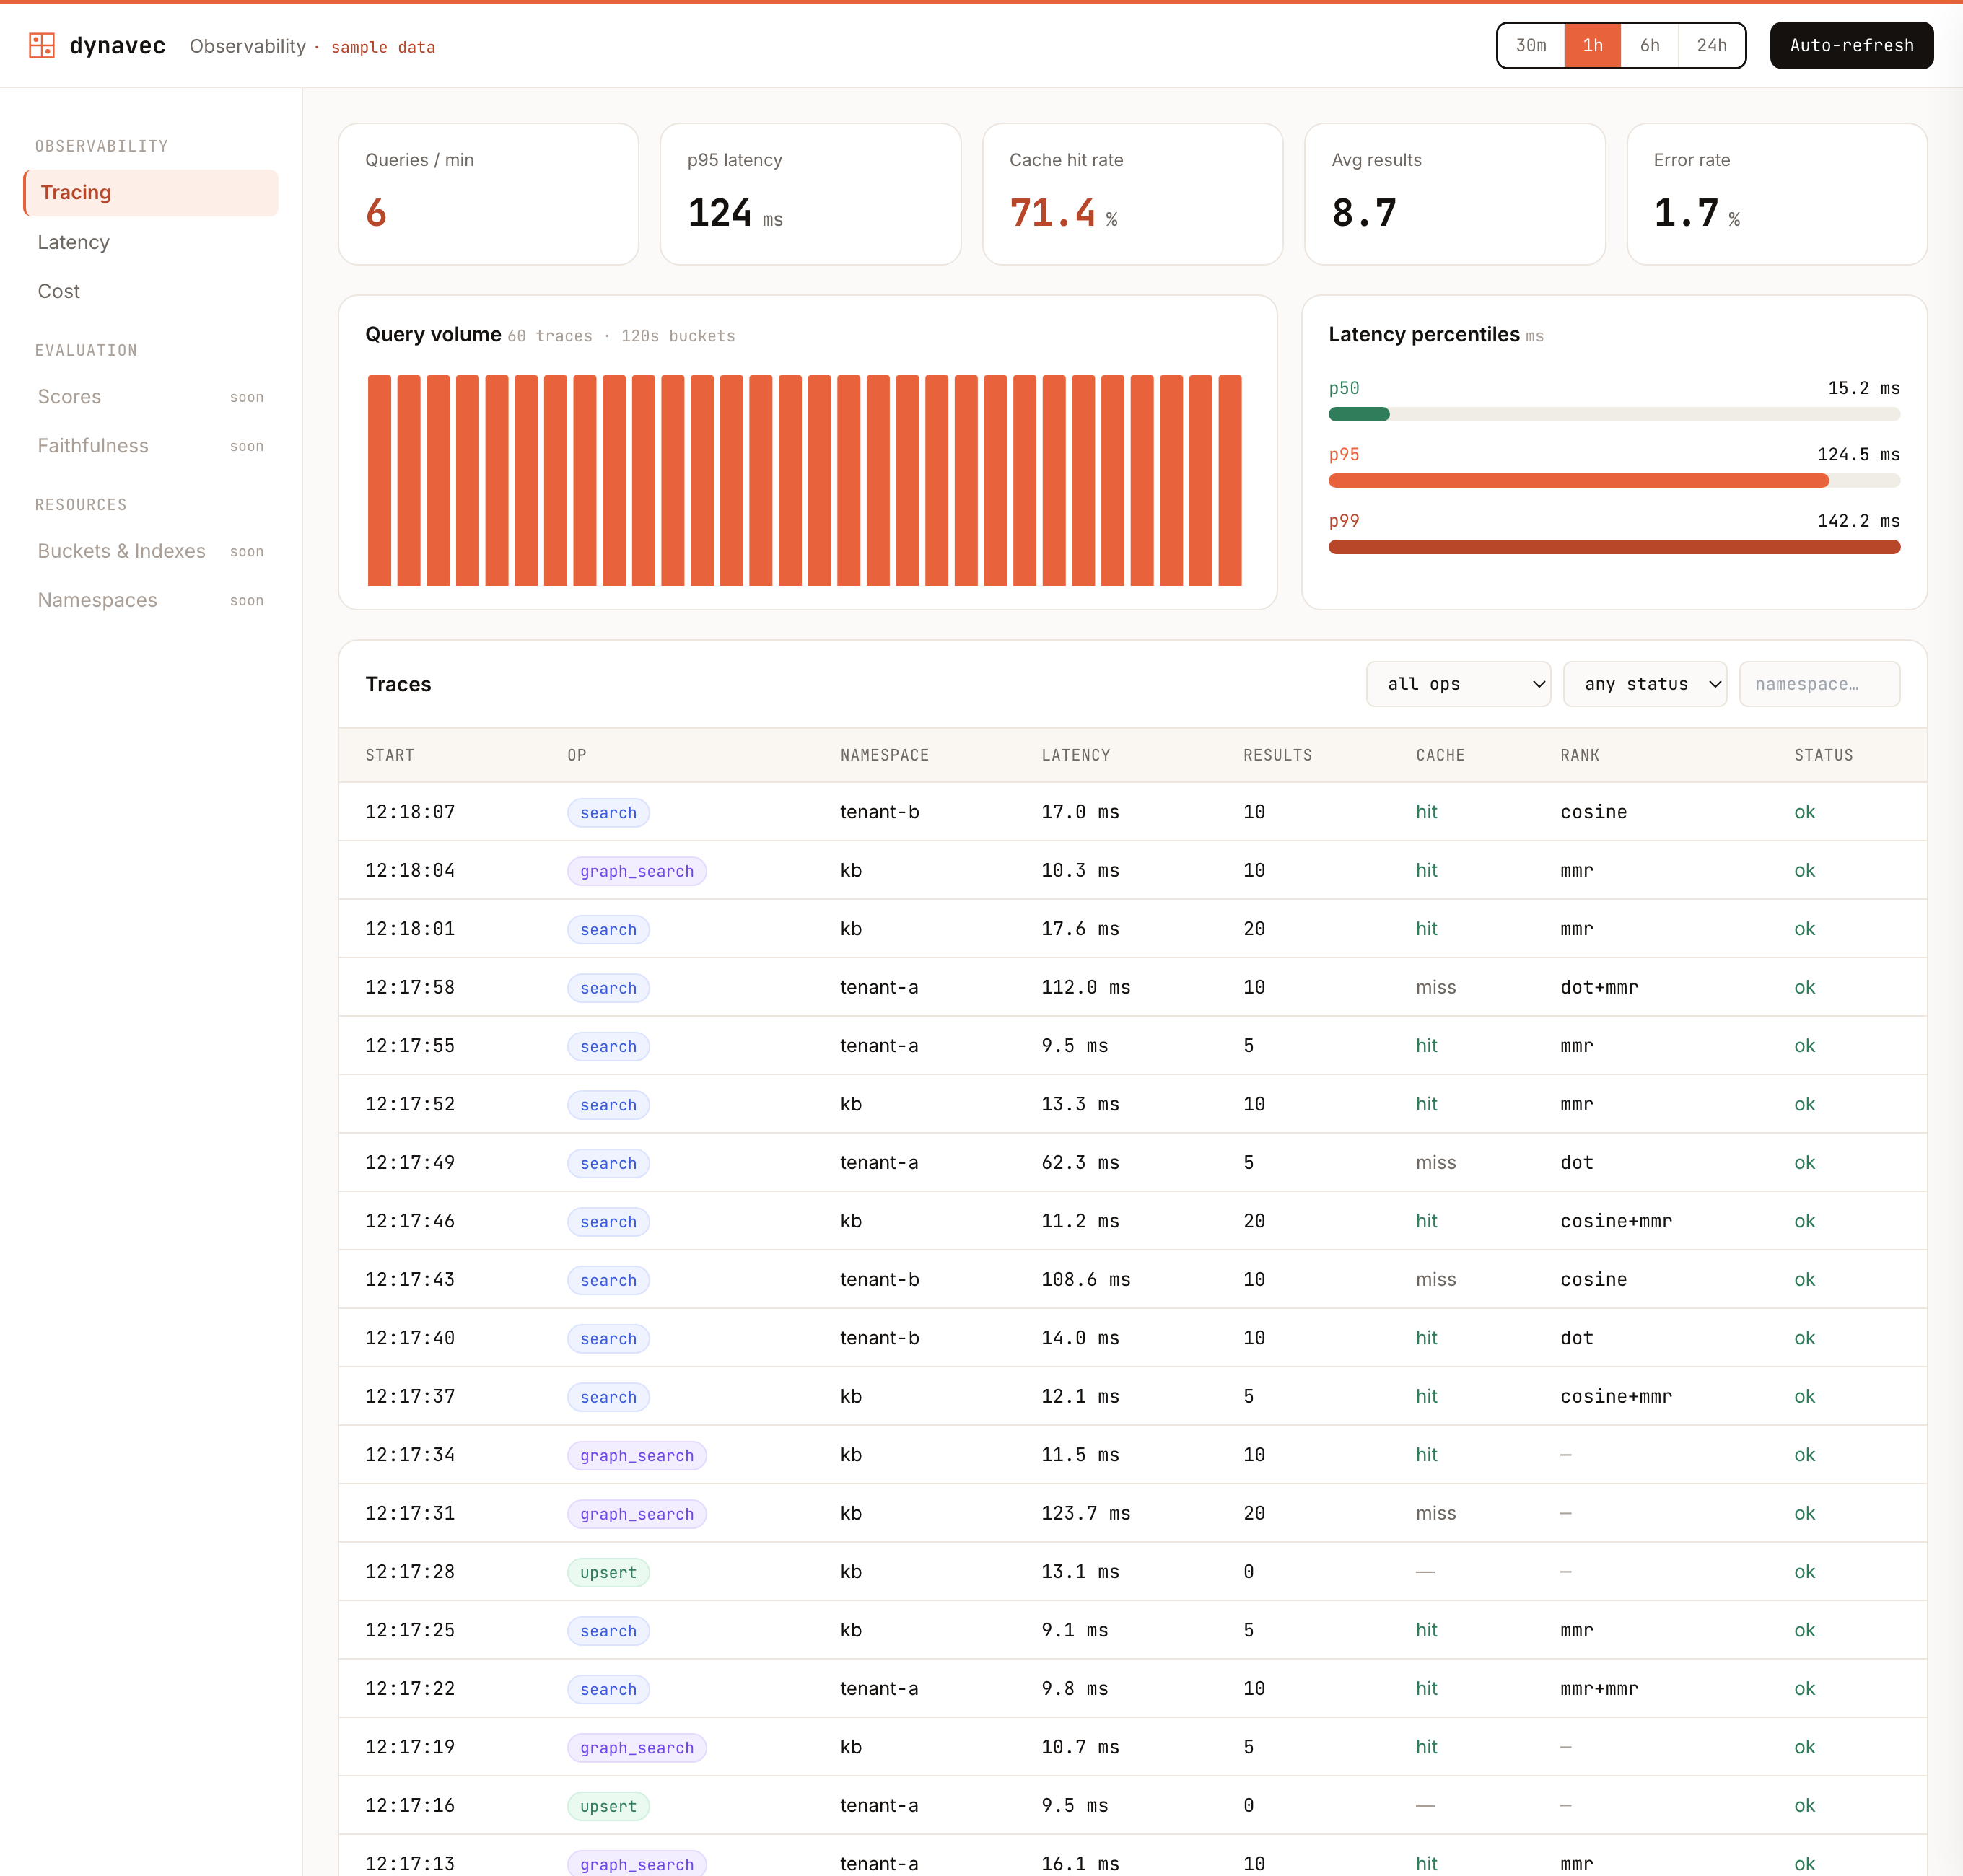
+**## Observability dashboard**
-### LangChain
-```python
-from dynavec.integrations.langchain import DynavecVectorStore
-store = DynavecVectorStore(db, namespace="kb")
-retriever = store.as_retriever(search_kwargs={"k": 4})
-```
+A native, in-your-brand **\*\*observability dashboard\*\*** — a Langfuse-style view of
-### FastMCP Server (Claude Desktop, Cursor, AI agents)
+**\*\*real\*\*** query telemetry (no simulated data). Attach a recorder and every search
-Expose `dynavec_search` and `dynavec_graph_search` tools to any MCP client over stdio:
+is captured with latency, cache outcome, result count, and score stats.
-```bash
-# Launch MCP server from environment variables
-dynavec mcp
-```
-```json
-{
- "mcpServers": {
- "dynavec": {
- "command": "uvx",
- "args": ["--with", "dynavec[all]", "dynavec", "mcp"],
- "env": {
- "AWS_ACCESS_KEY_ID": "AKIA...",
- "AWS_SECRET_ACCESS_KEY": "...",
- "AWS_REGION": "us-east-1",
- "OPENAI_API_KEY": "sk-...",
- "DYNAVEC_VECTOR_BUCKET": "my-vectors",
- "DYNAVEC_INDEX": "docs",
- "DYNAVEC_TABLE": "dynavec_docs"
- }
- }
- }
-}
-```
-### Strands Agents
+![dynavec observability dashboard]\(https\://raw\.githubusercontent.com/codeforstartups/dynavec/development/docs/assets/dashboard.png)
-Use the framework-agnostic `make_retriever_fn` as a native Strands tool:
-```bash
-pip install "dynavec[sentence-transformers]" strands-agents
-```
-```python
-from strands import Agent, tool
+**\*\*▶ [Live interactive preview]\(**https\://codeforstartups.github.io/dynavec/dashboard/**)\*\*** — in the landing-page theme.
-from dynavec.integrations.tools import make_retriever_fn
-retrieve = make_retriever_fn(db, namespace="kb", top_k=2)
-@tool
-def search_knowledge_base(query: str) -> str:
- """Search the dynavec knowledge base for relevant passages."""
- return retrieve(query)
+The dashboard is a **\*\*Next.js + TypeScript + Tailwind + Recharts\*\*** app in [\`dashboard/\`]\(dashboard); the data comes from a tiny Python telemetry API. Two steps:
-agent = Agent(tools=[search_knowledge_base])
-agent("Where is dynavec vector data stored?")
-```
-See [`examples/strands_retriever.py`](examples/strands_retriever.py) for a complete example that provisions a database and indexes sample documents. LlamaIndex integration remains on the roadmap; the core client works in any agent framework today.
----
+**\*\*1. Expose real telemetry\*\*** — attach a recorder to your client and serve the API:
-## Query expansion: Multi-Query and HyDE
-Single-query vector search frequently misses relevant documents when queries are short, colloquial, or use different terminology than the corpus. Dynavec provides two first-class query expansion adapters:
-### MultiQueryRetriever
-Expands a user query into diverse reformulations using an LLM, fans out searches concurrently, and merges results via Reciprocal Rank Fusion (RRF):
+\`\`\`python
-```python
-from dynavec import MultiQueryRetriever
+from dynavec import Dynavec, DynavecConfig, SemanticCache
-retriever = MultiQueryRetriever(
- db.namespace("docs"),
- generate_queries=lambda q: my_llm.generate_variations(q, n=3),
- top_k=4,
-)
-hits = retriever.search("car won't start")
-```
+from dynavec.telemetry import TelemetryRecorder
-### HyDERetriever
-Hypothetical Document Embeddings (HyDE) asks an LLM to generate an answer passage, embeds it as a document (via `embed_documents`), and retrieves nearest neighbours. Supports single-passage or multi-passage Centroid averaging (`strategy="average"`) and multi-search fusion (`strategy="fuse"`):
+from dynavec.dashboard import serve
-```python
-from dynavec import HyDERetriever
-hyde = HyDERetriever(
- db.namespace("docs"),
- generate_hypothetical=lambda q: my_llm.generate_answer(q),
- top_k=4,
- strategy="average",
- include_original=True,
-)
-hits = hyde.search("explain dynamo db storage pricing breakdown")
-```
-You can also instantiate retrievers directly via `db.as_multiquery_retriever(...)` or `db.namespace("docs").as_hyde_retriever(...)`.
+rec = TelemetryRecorder()
----
+db = Dynavec(cfg, embedder=emb, cache=SemanticCache(), telemetry=rec)
-## Choosing an embedding dimension
+\# ... your app runs searches; the recorder fills automatically ...
-Embedding dimension trades off recall against storage cost and latency. A larger dimension usually gives higher recall, but the right choice is the **smallest dimension that meets your recall target** — not the largest. See [EMBEDDING_DIMENSIONS.md](docs/EMBEDDING_DIMENSIONS.md) for a comparison table, the S3 Vectors 4096-dim ceiling, and a step-by-step picking guide.
+serve(rec, port=8779) # JSON API at http\://127.0.0.1:8779
----
+\`\`\`
-## Namespaces & multi-tenancy
-Every write/read takes a `namespace`. dynavec tags each vector with its namespace and scopes queries to it automatically, so a single index can host many tenants (or many embedding "collections") with clean isolation. DynamoDB keys use escaped `"{namespace}#{id}"` components for even partition distribution, so `#` in namespaces, document IDs, and graph entity IDs remains unambiguous.
----
+**\*\*2. Run the dashboard\*\*** (points at that API; falls back to sample data if unset):
-## Provisioning & IAM
-`auto_provision=True` (or `db.provision()`) creates the S3 vector bucket, the vector index, and the DynamoDB table idempotently. The caller needs `s3vectors:*` on the bucket/index and `dynamodb:*` on the table (scope these down in production — see [ARCHITECTURE.md](ARCHITECTURE.md)). For supported AWS regions and regional configuration, see [REGIONS.md](docs/REGIONS.md).
-### Inspecting what's provisioned
+\`\`\`bash
-`db.describe()` returns an `IndexInfo` dataclass with the live bucket/index/table
-config — dimension, distance metric, non-filterable metadata keys, and the
-DynamoDB table's status and item count. Useful for a quick sanity check after
-`provision()`, or for debugging a dimension-mismatch in production.
+cd dashboard
-```python
-info = db.describe()
-print(info.dimension, info.distance_metric, info.table_status)
-```
+npm install
----
+NEXT_PUBLIC_DYNAVEC_API=http\://127.0.0.1:8779 npm run dev # http\://localhost:3000
-## Benchmarks
+\`\`\`
-`benchmarks/` measures recall@k, latency (p50/p95/p99), and estimated \$/month, with a cost model comparing dynavec to Pinecone / Qdrant / Milvus / Weaviate / OpenSearch. See [benchmarks/README.md](benchmarks/README.md).
-### Cost by scale
-dynavec has **no idle floor** — you pay storage + per-request, so it stays far below cluster- and OCU-based systems, and tracks serverless Pinecone while keeping your data in-account.
+No AWS? \`python examples/dashboard_demo.py\` runs real searches against in-memory
-
+stand-ins and serves the API on \`:8779\` for the dashboard to read.
-### Quality & latency
-
-### Comparison (1M × 768d, 1M queries/mo)
+It shows a query-volume histogram, latency percentiles (p50/p95/p99), cache
-| Metric | dynavec | Pinecone | OpenSearch | Qdrant | Weaviate | Milvus/Zilliz |
-|---|---|---|---|---|---|---|
-| Recall@10 | 0.90 | 0.95 | 0.97 | **0.98** | 0.97 | 0.98 |
-| Latency p50 (ms) | 45 | 30 | 15 | 8 | 10 | **7** |
-| Latency p95 (ms) | 120 | 70 | 40 | 20 | 25 | **18** |
-| Cost ($/mo) | **$3** | $9 | $701 | $160 | $175 | $150 |
-| Serverless (scale-to-zero) | Yes | Yes | No (OCU floor) | No (nodes) | No (nodes) | No (CU) |
-| Data in your AWS account | Yes | No | Yes | Self-host only | Self-host only | Self-host only |
+hit-rate, and a filterable **\*\*traces\*\*** table with per-trace drill-down.
-> **Honesty note:** the **cost** row is computed by the repo's cost model from public list prices (order-of-magnitude; verify before quoting). **Recall/latency** are representative figures pending a live AWS run — regenerate real numbers with the commands below.
+**\*\*Contributors welcome:\*\*** the Evaluation (recall\@k, faithfulness), Resource
-### Scaling: every embedding dimension, 100K → 1 billion vectors
+(buckets/indexes/namespaces), and Cost panels are open under the
-Cost across the common embedding dimensions (384 / 768 / 1024 / 1536 / 3072) and the full scale ladder. dynavec stays lowest at **every** point because its storage is priced like S3, not RAM — while cluster/OCU systems grow linearly with data held in memory.
+[dashboard epic (#122)]\(https\://github.com/codeforstartups/dynavec/issues/122).
-
-| | Cost by dimension @ 100M vectors | Raw storage footprint |
-|---|---|---|
-| |  |  |
-**1536-dim (e.g. OpenAI `text-embedding-3-small`) — $/month @ 1M queries/mo:**
+\---
-| Product | 100K | 1M | 10M | 100M | 1B |
-|---|---|---|---|---|---|
-| **dynavec** | **$3** | **$3** | **$8** | **$50** | **$469** |
-| Pinecone | $9 | $10 | $27 | $197 | $1,897 |
-| OpenSearch | $701 | $701 | $877 | $8,423 | $83,708 |
-| Qdrant | $160 | $160 | $960 | $8,640 | $85,920 |
-| Weaviate | $175 | $175 | $1,050 | $9,450 | $93,975 |
-| Milvus/Zilliz | $150 | $150 | $900 | $8,100 | $80,550 |
-| _raw float32 size_ | 1 GB | 6 GB | 57 GB | 572 GB | 5,722 GB |
-Full tables for all five dimensions: [scaling.md](https://github.com/codeforstartups/dynavec/blob/development/docs/assets/scaling.md). At 1B × 1536-d that's ~5.7 TB of raw vectors — where dynavec's product quantization and the S3-priced tier matter most.
-```bash
-pip install "dynavec[benchmark]" # or: uv add "dynavec[benchmark]"
+**## Capabilities**
-# reproduce the charts + table above
-python -m benchmarks.report --vectors 1_000_000 --dim 768 --qpm 1_000_000
-# measure real recall + latency against your own AWS account
-python -m benchmarks.run_benchmark --backend dynavec \
- --bucket my-vectors --index bench --table dynavec_bench --n 100000 --dim 768
-```
----
+\| Area | What you get | API |
-## Observability dashboard
+\|------|--------------|-----|
-A native, in-your-brand **observability dashboard** — a Langfuse-style view of
-**real** query telemetry (no simulated data). Attach a recorder and every search
-is captured with latency, cache outcome, result count, and score stats.
+\| **\*\*Distance metrics\*\*** | Index on cosine/euclidean (S3 Vectors native); client-side rescore in cosine / dot / euclidean / manhattan or a **\*\*weighted combination\*\***, with optional result-set normalization | \`search(..., rescore="dot", normalize_scores=True)\` |
-
+\| **\*\*Concurrency\*\*** | GIL-aware thread pool — real parallelism for I/O-bound AWS calls; parallel batched writes + \`search_many\`; tunable botocore connection pool (default 10, raise for high concurrency) | \`DynavecConfig(max_workers=8, max_pool_connections=50)\`, \`db.search_many([...])\` |
-**▶ [Live interactive preview](https://codeforstartups.github.io/dynavec/dashboard/)** — in the landing-page theme.
+\| **\*\*Streaming\*\*** | Results yielded page-by-page as S3 Vectors paginates, so agents start consuming early | \`for hit in db.search_stream(q): ...\` |
-The dashboard is a **Next.js + TypeScript + Tailwind + Recharts** app in [`dashboard/`](dashboard); the data comes from a tiny Python telemetry API. Two steps:
+\| **\*\*Namespace RAG\*\*** | Per-tenant/collection handles; isolation + even partitioning | \`kb = db.namespace("kb"); kb.search(...)\` |
-**1. Expose real telemetry** — attach a recorder to your client and serve the API:
+\| **\*\*Product quantization\*\*** | Compress cached/hot-tier vectors up to 32× (ADC distance) | \`ProductQuantizer(m=96).fit(X)\` |
-```python
-from dynavec import Dynavec, DynavecConfig, SemanticCache
-from dynavec.telemetry import TelemetryRecorder
-from dynavec.dashboard import serve
+\| **\*\*Knowledge graph / ER\*\*** | Entities + relations in DynamoDB linked to embeddings; traverse to scope/guide vector search (GraphRAG) | \`db.graph_add_edge(...)\`, \`db.graph_search(q, seed_entities=[...])\` |
-rec = TelemetryRecorder()
-db = Dynavec(cfg, embedder=emb, cache=SemanticCache(), telemetry=rec)
-# ... your app runs searches; the recorder fills automatically ...
-serve(rec, port=8779) # JSON API at http://127.0.0.1:8779
-```
+\| **\*\*Query cache\*\*** | DynamoDB-TTL exact cache, in-process **\*\*semantic\*\*** cache (serves near-duplicate queries), or Redis/**\*\*ElastiCache\*\***; writes evict the affected namespace's entries | \`Dynavec(..., cache=SemanticCache())\` |
-**2. Run the dashboard** (points at that API; falls back to sample data if unset):
+\| **\*\*Ingestion / MCP\*\*** | Pull + chunk + embed from any source; **\*\*any MCP server's resources\*\*** (Notion, Confluence, Drive, …) become a corpus | \`ingest(db, MCPResourceSource(session))\` |
-```bash
-cd dashboard
-npm install
-NEXT_PUBLIC_DYNAVEC_API=http://127.0.0.1:8779 npm run dev # http://localhost:3000
-```
+\| **\*\*Updates + Lambda\*\*** | Update text/vector/metadata (merge or replace) with **\*\*optimistic concurrency\*\*** (versioned conditional writes; \`ConflictError\` instead of lost updates); transform pipeline incl. **\*\*in-account AWS Lambda\*\*** | \`db.update(id, ..., expected_version=v)\`, \`Dynavec(..., transform=LambdaTransform(...))\` |
-No AWS? `python examples/dashboard_demo.py` runs real searches against in-memory
-stand-ins and serves the API on `:8779` for the dashboard to read.
+\| **\*\*IAM / credentials\*\*** | Access keys, session tokens, named profiles, cross-account **\*\*assume-role\*\*** | \`Dynavec(..., credentials=AWSCredentials(...))\` |
+
+\| **\*\*Frameworks\*\*** | LangChain + LlamaIndex vector stores; a framework-agnostic tool for LangGraph/CrewAI/Strands | \`dynavec.integrations.\*\` |
+
+\| **\*\*Benchmark report\*\*** | Comparison table + recall/latency + cost-by-scale (log) charts | \`python -m benchmarks.report\` |
+
+
+
+\`SemanticCache\` can be bounded by both entry count and approximate in-memory
+
+size. Pass \`max_bytes\` to account for each cached float32 query vector and its
+
+result object graph, and inspect \`size_bytes\` for the current accounted size:
+
+
+
+\`\`\`python
+
+cache = SemanticCache(max_size=2_048, max_bytes=64 \* 1024 \* 1024)
+
+\`\`\`
+
+
+
+\`upsert\`/\`update\`/\`delete\` evict the written namespace's cached queries, so
-It shows a query-volume histogram, latency percentiles (p50/p95/p99), cache
-hit-rate, and a filterable **traces** table with per-trace drill-down.
-**Contributors welcome:** the Evaluation (recall@k, faithfulness), Resource
-(buckets/indexes/namespaces), and Cost panels are open under the
-[dashboard epic (#122)](https://github.com/codeforstartups/dynavec/issues/122).
-
----
-
-## Capabilities
-
-| Area | What you get | API |
-|------|--------------|-----|
-| **Distance metrics** | Index on cosine/euclidean (S3 Vectors native); client-side rescore in cosine / dot / euclidean / manhattan or a **weighted combination**, with optional result-set normalization | `search(..., rescore="dot", normalize_scores=True)` |
-| **Concurrency** | GIL-aware thread pool — real parallelism for I/O-bound AWS calls; parallel batched writes + `search_many`; tunable botocore connection pool (default 10, raise for high concurrency) | `DynavecConfig(max_workers=8, max_pool_connections=50)`, `db.search_many([...])` |
-| **Streaming** | Results yielded page-by-page as S3 Vectors paginates, so agents start consuming early | `for hit in db.search_stream(q): ...` |
-| **Namespace RAG** | Per-tenant/collection handles; isolation + even partitioning | `kb = db.namespace("kb"); kb.search(...)` |
-| **Product quantization** | Compress cached/hot-tier vectors up to 32× (ADC distance) | `ProductQuantizer(m=96).fit(X)` |
-| **Knowledge graph / ER** | Entities + relations in DynamoDB linked to embeddings; traverse to scope/guide vector search (GraphRAG) | `db.graph_add_edge(...)`, `db.graph_search(q, seed_entities=[...])` |
-| **Query cache** | DynamoDB-TTL exact cache, in-process **semantic** cache (serves near-duplicate queries), or Redis/**ElastiCache**; writes evict the affected namespace's entries | `Dynavec(..., cache=SemanticCache())` |
-| **Ingestion / MCP** | Pull + chunk + embed from any source; **any MCP server's resources** (Notion, Confluence, Drive, …) become a corpus | `ingest(db, MCPResourceSource(session))` |
-| **Updates + Lambda** | Update text/vector/metadata (merge or replace) with **optimistic concurrency** (versioned conditional writes; `ConflictError` instead of lost updates); transform pipeline incl. **in-account AWS Lambda** | `db.update(id, ..., expected_version=v)`, `Dynavec(..., transform=LambdaTransform(...))` |
-| **IAM / credentials** | Access keys, session tokens, named profiles, cross-account **assume-role** | `Dynavec(..., credentials=AWSCredentials(...))` |
-| **Frameworks** | LangChain + LlamaIndex vector stores; a framework-agnostic tool for LangGraph/CrewAI/Strands | `dynavec.integrations.*` |
-| **Benchmark report** | Comparison table + recall/latency + cost-by-scale (log) charts | `python -m benchmarks.report` |
-
-`SemanticCache` can be bounded by both entry count and approximate in-memory
-size. Pass `max_bytes` to account for each cached float32 query vector and its
-result object graph, and inspect `size_bytes` for the current accounted size:
-
-```python
-cache = SemanticCache(max_size=2_048, max_bytes=64 * 1024 * 1024)
-```
-
-`upsert`/`update`/`delete` evict the written namespace's cached queries, so
writes are never hidden behind stale entries. Set
-`DynavecConfig(cache_invalidate_on_write=False)` to opt out.
-Pre-populate the cache from a list of common queries at startup with `warm_cache()` —
-it runs each query once (through `search`, so results land in the cache) and
+\`DynavecConfig(cache_invalidate_on_write=False)\` to opt out.
+
+
+
+Pre-populate the cache from a list of common queries at startup with \`warm_cache()\` —
+
+it runs each query once (through \`search\`, so results land in the cache) and
+
returns the number of queries processed:
-```python
+
+
+\`\`\`python
+
from dynavec import Dynavec, DynavecConfig, SemanticCache, warm_cache
+
+
db = Dynavec(DynavecConfig(...), embedder=..., cache=SemanticCache())
+
warm_cache(db, ["what is vector search", "how do i upsert documents"], top_k=10)
-```
-Pass the same `filter` / `rescore` / `rerank` options you use at runtime so the
+\`\`\`
+
+
+
+Pass the same \`filter\` / \`rescore\` / \`rerank\` options you use at runtime so the
+
warmed entries share cache keys with real queries.
-Remove graph entities and relations with `graph_delete_node()` and
-`graph_delete_edge()`. Both are idempotent and return the number of edges removed.
+
+
+Remove graph entities and relations with \`graph_delete_node()\` and
+
+\`graph_delete_edge()\`. Both are idempotent and return the number of edges removed.
+
Deleting a node also strips every edge pointing at it (a namespace scan) but
+
leaves its linked documents and their embeddings untouched:
-```python
+
+
+\`\`\`python
+
db.graph_delete_edge("acme", "competes_with", "globex", namespace="kb", bidirectional=True)
+
db.graph_delete_node("globex", namespace="kb")
-```
+
+\`\`\`
+
+
Load graph records with grouped DynamoDB updates:
-```python
+
+
+\`\`\`python
+
result = db.graph_import(
- namespace="kb",
- nodes=[{"id": "acme", "ntype": "company", "props": {"country": "US"}}],
- edges=[{"src": "acme", "relation": "supplies", "dst": "globex",
- "weight": 2.5, "props": {"created_at": "2026-10-07T12:00:00Z"}}],
- batch_size=100,
+
+ namespace="kb",
+
+ nodes=[{"id": "acme", "ntype": "company", "props": {"country": "US"}}],
+
+ edges=[{"src": "acme", "relation": "supplies", "dst": "globex",
+
+ "weight": 2.5, "props": {"created_at": "2026-10-07T12:00:00Z"}}],
+
+ batch_size=100,
+
)
-print(result.nodes_processed, result.edges_appended) # 2, 1
+
+print(result.nodes_processed, result.edges_appended) # 2, 1
+
+
db.graph_import_file(namespace="kb", json_file="graph.json")
+
db.graph_import_file(namespace="kb", nodes_csv="nodes.csv", edges_csv="edges.csv")
-# Either CSV file can also be supplied alone.
-```
-Both client methods default to namespace `"default"`. The storage APIs are
-`GraphStore.import_graph(ns, *, nodes=None, edges=None, batch_size=100)` and
-`GraphStore.import_graph_file(ns, *, json_file=None, nodes_csv=None, edges_csv=None,
-batch_size=100)`. They return `GraphImportResult`: `nodes_processed` counts unique
+\# Either CSV file can also be supplied alone.
+
+\`\`\`
+
+
+
+Both client methods default to namespace \`"default"\`. The storage APIs are
+
+\`GraphStore.import_graph(ns, \*, nodes=None, edges=None, batch_size=100)\` and
+
+\`GraphStore.import_graph_file(ns, \*, json_file=None, nodes_csv=None, edges_csv=None,
+
+batch_size=100)\`. They return \`GraphImportResult\`: \`nodes_processed\` counts unique
+
IDs, including inferred edge endpoints and already-existing nodes;
-`edges_appended` counts input edge records. Empty record collections return zeros.
-
-- **Python:** `nodes` and `edges` are sequences of dictionaries. Nodes require a
- non-empty string `id`; optional `ntype` is a string or `None`, and `props` is a
- dictionary or `None`. Edges require non-empty strings `src`, `relation`, and
- `dst`; optional `weight` defaults to `1.0`, and omitted/`None` `props` defaults
- to `{}`. Identifiers are stored unchanged, including spaces.
-- **JSON:** a UTF-8 object containing optional `nodes` and `edges` arrays using
- those same fields. Missing arrays mean empty collections; `null` arrays are
- invalid. For example: `{"nodes": [{"id": "acme"}], "edges": [{"src": "acme",
- "relation": "supplies", "dst": "globex"}]}`.
-- **CSV:** separate UTF-8 files. Node headers: required `id`, optional `ntype,props`.
- Edge headers: required `src,relation,dst`, optional `weight,props`. A `props`
- cell must contain a JSON object; use standard CSV quoting, e.g.
- `acme,company,"{""country"":""US""}"`. Blank optional cells mean omitted values.
- Supply JSON or CSV files in one call; combining formats is invalid.
-
-Existing edges and document links are preserved. Omitted/`None` node attributes
-preserve existing values; explicit node `props` replaces the entire dictionary,
-so `{}` clears it. For repeated node IDs, later supplied attributes win, while
+
+\`edges_appended\` counts input edge records. Empty record collections return zeros.
+
+
+
+\- **\*\*Python:\*\*** \`nodes\` and \`edges\` are sequences of dictionaries. Nodes require a
+
+ non-empty string \`id\`; optional \`ntype\` is a string or \`None\`, and \`props\` is a
+
+ dictionary or \`None\`. Edges require non-empty strings \`src\`, \`relation\`, and
+
+ \`dst\`; optional \`weight\` defaults to \`1.0\`, and omitted/\`None\` \`props\` defaults
+
+ to \`{}\`. Identifiers are stored unchanged, including spaces.
+
+\- **\*\*JSON:\*\*** a UTF-8 object containing optional \`nodes\` and \`edges\` arrays using
+
+ those same fields. Missing arrays mean empty collections; \`null\` arrays are
+
+ invalid. For example: \`{"nodes": [{"id": "acme"}], "edges": [{"src": "acme",
+
+ "relation": "supplies", "dst": "globex"}]}\`.
+
+\- **\*\*CSV:\*\*** separate UTF-8 files. Node headers: required \`id\`, optional \`ntype,props\`.
+
+ Edge headers: required \`src,relation,dst\`, optional \`weight,props\`. A \`props\`
+
+ cell must contain a JSON object; use standard CSV quoting, e.g.
+
+ \`acme,company,"{""country"":""US""}"\`. Blank optional cells mean omitted values.
+
+ Supply JSON or CSV files in one call; combining formats is invalid.
+
+
+
+Existing edges and document links are preserved. Omitted/\`None\` node attributes
+
+preserve existing values; explicit node \`props\` replaces the entire dictionary,
+
+so \`{}\` clears it. For repeated node IDs, later supplied attributes win, while
+
omitted values preserve earlier ones. Missing edge endpoints are created without
+
overwriting existing endpoint metadata. Duplicate edges remain duplicates, and
-repeating an import appends them again: imports are **not idempotent**.
+
+repeating an import appends them again: imports are **\*\*not idempotent\*\***.
+
+
Finite numeric weights may be negative or greater than one; booleans, NaN,
+
infinity, and numbers outside DynamoDB's supported precision/range are rejected.
-Nested floats in properties are copied as `Decimal` values for DynamoDB, caller
+
+Nested floats in properties are copied as \`Decimal\` values for DynamoDB, caller
+
inputs are not mutated, and timestamp strings remain caller-provided strings.
+
Unsupported DynamoDB values are rejected before writing.
+
+
Every supplied record/file is loaded and validated before any database writes,
+
including when both CSV files are supplied. Errors identify a record index or
+
filename/CSV row. Complete prevalidation uses memory proportional to the import.
+
Each unique node is prepared once, then edges are grouped by source and appended
-in input order within that source. `batch_size` must be a positive integer
+
+in input order within that source. \`batch_size\` must be a positive integer
+
(excluding booleans) and limits edges per append request. Three edges from one
-source to three destinations use five `UpdateItem` requests with the default
-batch size, versus nine via three `add_edge()` calls. This is grouping, not
-compression or a single AWS request; `BatchWriteItem` is not used.
-The existing **400 KB DynamoDB item limit** still applies to each node's complete
+source to three destinations use five \`UpdateItem\` requests with the default
+
+batch size, versus nine via three \`add_edge()\` calls. This is grouping, not
+
+compression or a single AWS request; \`BatchWriteItem\` is not used.
+
+
+
+The existing **\*\*400 KB DynamoDB item limit\*\*** still applies to each node's complete
+
adjacency list, even with small chunks. AWS failures can leave partial writes;
+
there is no whole-import rollback or exactly-once guarantee. Safe node preparation
+
uses the existing retry policy, but the importer does not retry edge appends or
+
restart completed chunks. SDK retries can still make ambiguous append failures
+
unsafe to replay; inspect the stored graph before deciding how to recover.
-## Ecosystem
+
+
+**## Ecosystem**
+
+
dynavec started as a vector database, and it's growing into a full agent stack that runs inside your own cloud account. The plan has four parts:
-| Project | Tagline | What it covers | Status |
-|---------|---------|----------------|--------|
-| dynavec | Remember | The vector database: S3 Vectors for search, DynamoDB for documents, plus caching, GraphRAG and hybrid retrieval | Available |
-| dynaflow | Build & run | An orchestration engine for agents, with a visual builder | Planned ([#273](https://github.com/codeforstartups/dynavec/issues/273)) |
-| dynalogs | Observe | Traces, logs, run history and metrics, kept in your own account | Early version: the [observability dashboard](#observability-dashboard) ([#274](https://github.com/codeforstartups/dynavec/issues/274)) |
-| dynaevals | Measure & improve | Retrieval and RAG metrics, test datasets and CI checks | Retrieval metrics available ([#275](https://github.com/codeforstartups/dynavec/issues/275)) |
-The roadmap is tracked in [#276](https://github.com/codeforstartups/dynavec/issues/276). It's a proposed order rather than a fixed schedule, and help is welcome on any of the linked issues. See [CONTRIBUTING.md](CONTRIBUTING.md) to get started.
-## Status
+\| Project | Tagline | What it covers | Status |
+
+\|---------|---------|----------------|--------|
+
+\| dynavec | Remember | The vector database: S3 Vectors for search, DynamoDB for documents, plus caching, GraphRAG and hybrid retrieval | Available |
+
+\| dynaflow | Build & run | An orchestration engine for agents, with a visual builder | Planned ([#273]\(https\://github.com/codeforstartups/dynavec/issues/273)) |
+
+\| dynalogs | Observe | Traces, logs, run history and metrics, kept in your own account | Early version: the [observability dashboard]\(#observability-dashboard) ([#274]\(https\://github.com/codeforstartups/dynavec/issues/274)) |
-**v0.7.0 (current)** — adds a **native async client** (`AsyncDynavec`), a **BM25 lexical retriever + dense hybrid fusion** (`hybrid_search`), **per-document TTL** with automatic provisioning, a **Semantic Kernel** connector, concurrent **`search_many()`**, **optimistic concurrency** on `update()`, **weighted graph edges**, **client-side rate limiting**, and parallelized `put_vectors` ingest — plus a graph metadata-preservation fix — on top of the v0.6 feature set and the v0.1 hybrid core.
+\| dynaevals | Measure & improve | Retrieval and RAG metrics, test datasets and CI checks | Retrieval metrics available ([#275]\(https\://github.com/codeforstartups/dynavec/issues/275)) |
-See the full history in **[CHANGELOG.md](CHANGELOG.md)**, the browsable **[Release notes](https://codeforstartups.github.io/dynavec/docs/release-notes.html)** page, or the **[GitHub Releases](https://github.com/codeforstartups/dynavec/releases)** tab.
-**Roadmap (v0.7):** native async client (`AsyncDynavec` on aioboto3), optional `hnswlib`/`faiss` hot-tier backend, and sparse/BM25 hybrid computed from DynamoDB.
-## Publishing (maintainers)
+The roadmap is tracked in [#276]\(https\://github.com/codeforstartups/dynavec/issues/276). It's a proposed order rather than a fixed schedule, and help is welcome on any of the linked issues. See [CONTRIBUTING.md]\(CONTRIBUTING.md) to get started.
-`dynavec` publishes to **PyPI**; both `pip` and `uv` install from there (there is no separate "uv registry").
-**Automated (recommended)** — a GitHub Release triggers [`.github/workflows/publish.yml`](.github/workflows/publish.yml), which builds and uploads via **PyPI Trusted Publishing (OIDC)** — no API token stored anywhere. One-time setup: on PyPI, add a *pending publisher* for project `dynavec`, repo `codeforstartups/dynavec`, workflow `publish.yml`, environment `pypi`. Then:
-```bash
-git tag v0.3.0 && git push origin v0.3.0 # then publish a GitHub Release for the tag
-```
+**## Status**
-**Manual** — if you'd rather push from your machine with a token:
-```bash
-uv build # -> dist/*.whl, dist/*.tar.gz
-uv publish # uses UV_PUBLISH_TOKEN / prompts
-# or: python -m twine upload dist/*
-```
-Bump the version in **both** `pyproject.toml` and `src/dynavec/__init__.py` before releasing.
+**\*\*v0.7.0 (current)\*\*** — adds a **\*\*native async client\*\*** (\`AsyncDynavec\`), a **\*\*BM25 lexical retriever + dense hybrid fusion\*\*** (\`hybrid_search\`), **\*\*per-document TTL\*\*** with automatic provisioning, a **\*\*Semantic Kernel\*\*** connector, concurrent **\*\*\`search_many()\`\*\***, **\*\*optimistic concurrency\*\*** on \`update()\`, **\*\*weighted graph edges\*\***, **\*\*client-side rate limiting\*\***, and parallelized \`put_vectors\` ingest — plus a graph metadata-preservation fix — on top of the v0.6 feature set and the v0.1 hybrid core.
-## 🫂 Community
-If you want to get more involved with dynavec, join our [WhatsApp community](https://chat.whatsapp.com/D73Mf1aDyIZHHMCgd32XHg). It's a friendly space to talk about vector search, RAG, AWS costs, production issues, and everything in between — ask questions, share what you're building, or help others out.
-## Contributors
+See the full history in **\*\*[CHANGELOG.md]\(**CHANGELOG.md**)\*\***, the browsable **\*\*[Release notes]\(**https\://codeforstartups.github.io/dynavec/docs/release-notes.html**)\*\*** page, or the **\*\*[GitHub Releases]\(**https\://github.com/codeforstartups/dynavec/releases**)\*\*** tab.
+
+
+
+**\*\*Roadmap (v0.7):\*\*** native async client (\`AsyncDynavec\` on aioboto3), optional \`hnswlib\`/\`faiss\` hot-tier backend, and sparse/BM25 hybrid computed from DynamoDB.
+
+
+
+**## Publishing (maintainers)**
+
+
+
+\`dynavec\` publishes to **\*\*PyPI\*\***; both \`pip\` and \`uv\` install from there (there is no separate "uv registry").
+
+
+
+**\*\*Automated (recommended)\*\*** — a GitHub Release triggers [\`.github/workflows/publish.yml\`]\(.github/workflows/publish.yml), which builds and uploads via **\*\*PyPI Trusted Publishing (OIDC)\*\*** — no API token stored anywhere. One-time setup: on PyPI, add a *\*pending publisher\** for project \`dynavec\`, repo \`codeforstartups/dynavec\`, workflow \`publish.yml\`, environment \`pypi\`. Then:
+
+
+
+\`\`\`bash
+
+git tag v0.3.0 && git push origin v0.3.0 # then publish a GitHub Release for the tag
+
+\`\`\`
+
+
+
+**\*\*Manual\*\*** — if you'd rather push from your machine with a token:
+
+
+
+\`\`\`bash
+
+uv build # -> dist/\*.whl, dist/\*.tar.gz
+
+uv publish # uses UV_PUBLISH_TOKEN / prompts
+
+\# or: python -m twine upload dist/\*
+
+\`\`\`
+
+
+
+Bump the version in **\*\*both\*\*** \`pyproject.toml\` and \`src/dynavec/\_\_init\_\_.py\` before releasing.
+
+
+
+**## 🫂 Community**
+
+
+
+If you want to get more involved with dynavec, join our [WhatsApp community]\(https\://chat.whatsapp.com/D73Mf1aDyIZHHMCgd32XHg). It's a friendly space to talk about vector search, RAG, AWS costs, production issues, and everything in between — ask questions, share what you're building, or help others out.
+
+
+
+**## Contributors**
+
+
+
+\`\`\`
-```
+----------------------------------------------------------------------------+
-| +----------------------------------------------------------------+ |
-| | Developers: Those who built with `dynavec`. | |
-| | (You have `import dynavec` somewhere in your project) | |
-| | +----------------------------------------------------+ | |
-| | | Contributors: Those who make `dynavec` better. | | |
-| | | (You make a PR to this repo) | | |
-| | +----------------------------------------------------+ | |
-| +----------------------------------------------------------------+ |
+
+\| +----------------------------------------------------------------+ |
+
+\| | Developers: Those who built with \`dynavec\`. | |
+
+\| | (You have \`import dynavec\` somewhere in your project) | |
+
+\| | +----------------------------------------------------+ | |
+
+\| | | Contributors: Those who make \`dynavec\` better. | | |
+
+\| | | (You make a PR to this repo) | | |
+
+\| | +----------------------------------------------------+ | |
+
+\| +----------------------------------------------------------------+ |
+
+----------------------------------------------------------------------------+
-```
-We welcome contributions from the community! Whether it's bug fixes, feature additions, or documentation improvements, your input is valuable. See [CONTRIBUTING.md](CONTRIBUTING.md) for the full guide, and browse [good first issues](https://github.com/codeforstartups/dynavec/issues?q=is%3Aissue+is%3Aopen+label%3A%22good+first+issue%22) to get started.
+\`\`\`
+
+
+
+We welcome contributions from the community! Whether it's bug fixes, feature additions, or documentation improvements, your input is valuable. See [CONTRIBUTING.md]\(CONTRIBUTING.md) for the full guide, and browse [good first issues]\(https\://github.com/codeforstartups/dynavec/issues?q=is%3Aissue+is%3Aopen+label%3A%22good+first+issue%22) to get started.
+
+
+
+1\. Fork the repository
+
+2\. Create your feature branch (\`git checkout -b feature/AmazingFeature\`)
+
+3\. Commit your changes (\`git commit -m 'Add some AmazingFeature'\`)
+
+4\. Push to the branch (\`git push origin feature/AmazingFeature\`)
+
+5\. Open a Pull Request
+
+
+
+**## License**
-1. Fork the repository
-2. Create your feature branch (`git checkout -b feature/AmazingFeature`)
-3. Commit your changes (`git commit -m 'Add some AmazingFeature'`)
-4. Push to the branch (`git push origin feature/AmazingFeature`)
-5. Open a Pull Request
-## License
Apache-2.0
diff --git a/benchmarks/benchmark_opq.py b/benchmarks/benchmark_opq.py
index 573da69..8617e9f 100644
--- a/benchmarks/benchmark_opq.py
+++ b/benchmarks/benchmark_opq.py
@@ -1,4 +1,3 @@
-
"""Benchmark PQ vs OPQ + PQ."""
from __future__ import annotations
@@ -63,9 +62,7 @@ def recall_at_k(
truth_set = set(truth[:k])
prediction_set = set(prediction[:k])
- recalls.append(
- len(truth_set & prediction_set) / k
- )
+ recalls.append(len(truth_set & prediction_set) / k)
return float(np.mean(recalls))
@@ -115,9 +112,7 @@ def benchmark_quantizer(
k=10,
)
- reconstruction_error = quantizer.reconstruction_error(
- database
- )
+ reconstruction_error = quantizer.reconstruction_error(database)
print(f"Fit time : {fit_time:.4f}s")
print(f"Encode time : {encode_time:.4f}s")
@@ -147,13 +142,9 @@ def main() -> None:
m = 8
nbits = 8
- database = rng.normal(
- size=(num_database, dimension)
- ).astype(np.float32)
+ database = rng.normal(size=(num_database, dimension)).astype(np.float32)
- queries = rng.normal(
- size=(num_queries, dimension)
- ).astype(np.float32)
+ queries = rng.normal(size=(num_queries, dimension)).astype(np.float32)
print("=== PQ vs OPQ + PQ Benchmark ===")
print(f"Database : {num_database} vectors")
@@ -223,25 +214,13 @@ def main() -> None:
print("\n=== Comparison ===")
- recall_improvement = (
- opq_results["recall_10"]
- - pq_results["recall_10"]
- )
+ recall_improvement = opq_results["recall_10"] - pq_results["recall_10"]
- error_improvement = (
- pq_results["reconstruction_error"]
- - opq_results["reconstruction_error"]
- )
+ error_improvement = pq_results["reconstruction_error"] - opq_results["reconstruction_error"]
- print(
- f"Recall@10 improvement : "
- f"{recall_improvement:+.4f}"
- )
+ print(f"Recall@10 improvement : {recall_improvement:+.4f}")
- print(
- f"Reconstruction improvement: "
- f"{error_improvement:+.6f}"
- )
+ print(f"Reconstruction improvement: {error_improvement:+.6f}")
if __name__ == "__main__":
diff --git a/benchmarks/benchmark_quantization.py b/benchmarks/benchmark_quantization.py
index f3340ff..684d9cd 100644
--- a/benchmarks/benchmark_quantization.py
+++ b/benchmarks/benchmark_quantization.py
@@ -14,9 +14,7 @@ def generate_dataset(n_vectors=10_000, dim=32, seed=0):
centers = rng.normal(size=(8, dim)).astype(np.float32)
assign = rng.integers(0, 8, size=n_vectors)
- x = centers[assign] + 0.05 * rng.normal(
- size=(n_vectors, dim)
- ).astype(np.float32)
+ x = centers[assign] + 0.05 * rng.normal(size=(n_vectors, dim)).astype(np.float32)
return x.astype(np.float32)
@@ -94,15 +92,11 @@ def benchmark():
scalar_codes,
)
- scalar_reconstruction_error = scalar.reconstruction_error(
- vectors
- )
+ scalar_reconstruction_error = scalar.reconstruction_error(vectors)
scalar_bytes_per_vector = scalar.code_size_bytes
scalar_total_bytes = scalar_codes.nbytes
- scalar_compression = (
- raw_bytes_per_vector / scalar_bytes_per_vector
- )
+ scalar_compression = raw_bytes_per_vector / scalar_bytes_per_vector
# ---------------------------------------------------------
# Product Quantizer
@@ -130,15 +124,11 @@ def benchmark():
pq_codes,
)
- pq_reconstruction_error = pq.reconstruction_error(
- vectors
- )
+ pq_reconstruction_error = pq.reconstruction_error(vectors)
pq_bytes_per_vector = pq.code_size_bytes
pq_total_bytes = pq_codes.nbytes
- pq_compression = (
- raw_bytes_per_vector / pq_bytes_per_vector
- )
+ pq_compression = raw_bytes_per_vector / pq_bytes_per_vector
# ---------------------------------------------------------
# Results
@@ -148,10 +138,7 @@ def benchmark():
print(f" Fit time: {scalar_fit_time:.4f} sec")
print(f" Encode time: {scalar_encode_time:.4f} sec")
print(f" Decode time: {scalar_decode_time:.4f} sec")
- print(
- f" Reconstruction error: "
- f"{scalar_reconstruction_error:.8f}"
- )
+ print(f" Reconstruction error: {scalar_reconstruction_error:.8f}")
print(f" Bytes/vector: {scalar_bytes_per_vector}")
print(f" Total encoded size: {scalar_total_bytes / 1024:.2f} KB")
print(f" Compression: {scalar_compression:.2f}x")
@@ -161,32 +148,20 @@ def benchmark():
print(f" Fit time: {pq_fit_time:.4f} sec")
print(f" Encode time: {pq_encode_time:.4f} sec")
print(f" Decode time: {pq_decode_time:.4f} sec")
- print(
- f" Reconstruction error: "
- f"{pq_reconstruction_error:.8f}"
- )
+ print(f" Reconstruction error: {pq_reconstruction_error:.8f}")
print(f" Bytes/vector: {pq_bytes_per_vector}")
print(f" Total encoded size: {pq_total_bytes / 1024:.2f} KB")
print(f" Compression: {pq_compression:.2f}x")
print()
print("Comparison")
- print(
- f" Scalar/PQ compression: "
- f"{scalar_compression / pq_compression:.2f}x"
- )
+ print(f" Scalar/PQ compression: {scalar_compression / pq_compression:.2f}x")
if scalar_encode_time > 0:
- print(
- f" PQ encode / Scalar encode: "
- f"{pq_encode_time / scalar_encode_time:.2f}x"
- )
+ print(f" PQ encode / Scalar encode: {pq_encode_time / scalar_encode_time:.2f}x")
if scalar_decode_time > 0:
- print(
- f" PQ decode / Scalar decode: "
- f"{pq_decode_time / scalar_decode_time:.2f}x"
- )
+ print(f" PQ decode / Scalar decode: {pq_decode_time / scalar_decode_time:.2f}x")
print()
print("=" * 80)
diff --git a/benchmarks/cost_model.py b/benchmarks/cost_model.py
index c839c01..ff758dd 100644
--- a/benchmarks/cost_model.py
+++ b/benchmarks/cost_model.py
@@ -19,12 +19,12 @@
@dataclass
class Workload:
- vectors: int # number of stored vectors
- dim: int # embedding dimension
+ vectors: int # number of stored vectors
+ dim: int # embedding dimension
queries_per_month: int
writes_per_month: int = 0
- metadata_bytes: int = 500 # avg full metadata + text per doc (DynamoDB)
- filterable_bytes: int = 120 # avg filterable metadata per vector (S3 Vectors)
+ metadata_bytes: int = 500 # avg full metadata + text per doc (DynamoDB)
+ filterable_bytes: int = 120 # avg filterable metadata per vector (S3 Vectors)
@property
def vector_bytes(self) -> int:
@@ -147,12 +147,15 @@ def main() -> None:
p.add_argument("--wpm", type=int, default=100_000, help="writes per month")
args = p.parse_args()
- w = Workload(vectors=args.vectors, dim=args.dim,
- queries_per_month=args.qpm, writes_per_month=args.wpm)
+ w = Workload(
+ vectors=args.vectors, dim=args.dim, queries_per_month=args.qpm, writes_per_month=args.wpm
+ )
- print(f"\nWorkload: {w.vectors:,} vectors × {w.dim}d "
- f"({w.raw_vector_gb:.1f} GB raw), {w.queries_per_month:,} queries/mo, "
- f"{w.writes_per_month:,} writes/mo\n")
+ print(
+ f"\nWorkload: {w.vectors:,} vectors × {w.dim}d "
+ f"({w.raw_vector_gb:.1f} GB raw), {w.queries_per_month:,} queries/mo, "
+ f"{w.writes_per_month:,} writes/mo\n"
+ )
print("dynavec breakdown:")
for k, v in dynavec_cost(w).items():
print(f" {k:<22} ${v:>10,.2f}")
diff --git a/benchmarks/datasets.py b/benchmarks/datasets.py
index 9ab3386..c88384c 100644
--- a/benchmarks/datasets.py
+++ b/benchmarks/datasets.py
@@ -9,8 +9,8 @@
@dataclass
class Dataset:
- vectors: np.ndarray # (N, dim) float32
- queries: np.ndarray # (Q, dim) float32
+ vectors: np.ndarray # (N, dim) float32
+ queries: np.ndarray # (Q, dim) float32
ids: list[str]
ground_truth: np.ndarray # (Q, k) int indices into vectors (exact NN)
@@ -55,7 +55,7 @@ def _l2_normalize(x: np.ndarray) -> np.ndarray:
def _exact_topk(vectors: np.ndarray, queries: np.ndarray, k: int) -> np.ndarray:
# cosine similarity == dot product on L2-normalized vectors
- sims = queries @ vectors.T # (Q, N)
+ sims = queries @ vectors.T # (Q, N)
return np.argpartition(-sims, kth=k - 1, axis=1)[:, :k]
diff --git a/benchmarks/report.py b/benchmarks/report.py
index 7c4f068..3201563 100644
--- a/benchmarks/report.py
+++ b/benchmarks/report.py
@@ -35,12 +35,12 @@
# Representative quality/latency profile (EDIT with measured values).
# recall@10, warm p50/p95/p99 ms for a ~1M x 768 workload.
_PROFILE = {
- "dynavec": {"recall": 0.90, "p50": 45, "p95": 120, "p99": 180},
- "pinecone_serverless": {"recall": 0.95, "p50": 30, "p95": 70, "p99": 110},
- "opensearch_serverless": {"recall": 0.97, "p50": 15, "p95": 40, "p99": 70},
- "qdrant_cloud": {"recall": 0.98, "p50": 8, "p95": 20, "p99": 35},
- "weaviate_cloud": {"recall": 0.97, "p50": 10, "p95": 25, "p99": 45},
- "milvus_zilliz": {"recall": 0.98, "p50": 7, "p95": 18, "p99": 30},
+ "dynavec": {"recall": 0.90, "p50": 45, "p95": 120, "p99": 180},
+ "pinecone_serverless": {"recall": 0.95, "p50": 30, "p95": 70, "p99": 110},
+ "opensearch_serverless": {"recall": 0.97, "p50": 15, "p95": 40, "p99": 70},
+ "qdrant_cloud": {"recall": 0.98, "p50": 8, "p95": 20, "p99": 35},
+ "weaviate_cloud": {"recall": 0.97, "p50": 10, "p95": 25, "p99": 45},
+ "milvus_zilliz": {"recall": 0.98, "p50": 7, "p95": 18, "p99": 30},
}
_LABELS = {
@@ -73,16 +73,32 @@ def markdown_table(inp: ReportInputs) -> str:
("Latency p50 (ms)", {p: _PROFILE[p]["p50"] for p in products}, "min", "{:.0f}"),
("Latency p95 (ms)", {p: _PROFILE[p]["p95"] for p in products}, "min", "{:.0f}"),
("Cost ($/mo)", {p: costs[p] for p in products}, "min", "${:,.0f}"),
- ("Serverless (scale-to-zero)", {
- "dynavec": "Yes", "pinecone_serverless": "Yes",
- "opensearch_serverless": "No (OCU floor)", "qdrant_cloud": "No (nodes)",
- "weaviate_cloud": "No (nodes)", "milvus_zilliz": "No (CU)",
- }, None, "{}"),
- ("Data in your AWS account", {
- "dynavec": "Yes", "pinecone_serverless": "No",
- "opensearch_serverless": "Yes", "qdrant_cloud": "Self-host only",
- "weaviate_cloud": "Self-host only", "milvus_zilliz": "Self-host only",
- }, None, "{}"),
+ (
+ "Serverless (scale-to-zero)",
+ {
+ "dynavec": "Yes",
+ "pinecone_serverless": "Yes",
+ "opensearch_serverless": "No (OCU floor)",
+ "qdrant_cloud": "No (nodes)",
+ "weaviate_cloud": "No (nodes)",
+ "milvus_zilliz": "No (CU)",
+ },
+ None,
+ "{}",
+ ),
+ (
+ "Data in your AWS account",
+ {
+ "dynavec": "Yes",
+ "pinecone_serverless": "No",
+ "opensearch_serverless": "Yes",
+ "qdrant_cloud": "Self-host only",
+ "weaviate_cloud": "Self-host only",
+ "milvus_zilliz": "Self-host only",
+ },
+ None,
+ "{}",
+ ),
]
header = "| Metric | " + " | ".join(_LABELS[p] for p in products) + " |"
@@ -148,21 +164,30 @@ def cost_scale_chart(inp: ReportInputs, out_path: str) -> str:
fig, ax = plt.subplots(figsize=(11, 6))
for p in products:
ax.plot(
- scales, series[p], marker="o",
- color=_COLORS[p], linewidth=2.5 if p == "dynavec" else 1.6,
+ scales,
+ series[p],
+ marker="o",
+ color=_COLORS[p],
+ linewidth=2.5 if p == "dynavec" else 1.6,
label=_LABELS[p],
)
ax.set_xscale("log")
ax.set_yscale("log")
ax.set_xlabel("Number of vectors (log scale)")
ax.set_ylabel("Estimated cost ($/month, log scale)")
- ax.set_title(f"Monthly cost by scale — {inp.dim}d, {inp.qpm:,} queries/mo",
- fontsize=14, weight="bold")
+ ax.set_title(
+ f"Monthly cost by scale — {inp.dim}d, {inp.qpm:,} queries/mo", fontsize=14, weight="bold"
+ )
ax.grid(True, which="both", alpha=0.25)
ax.legend()
- fig.text(0.5, -0.02,
- "APPROX public list prices (see cost_model.py). Order-of-magnitude only.",
- ha="center", fontsize=8, style="italic")
+ fig.text(
+ 0.5,
+ -0.02,
+ "APPROX public list prices (see cost_model.py). Order-of-magnitude only.",
+ ha="center",
+ fontsize=8,
+ style="italic",
+ )
fig.tight_layout()
fig.savefig(out_path, dpi=140, bbox_inches="tight")
plt.close(fig)
@@ -196,9 +221,14 @@ def cost_matrix_chart(out_path: str, qpm: int = 1_000_000, wpm: int = 100_000) -
for ax, dim in zip(axes, DIMENSIONS):
for p in products:
ys = [compare(Workload(n, dim, qpm, wpm))[p] for n in SCALES]
- ax.plot(SCALES, ys, marker="o",
- color=_COLORS[p], linewidth=2.4 if p == "dynavec" else 1.4,
- label=_LABELS[p])
+ ax.plot(
+ SCALES,
+ ys,
+ marker="o",
+ color=_COLORS[p],
+ linewidth=2.4 if p == "dynavec" else 1.4,
+ label=_LABELS[p],
+ )
ax.set_xscale("log")
ax.set_yscale("log")
ax.set_title(f"{dim}-dim embeddings", weight="bold")
@@ -212,8 +242,11 @@ def cost_matrix_chart(out_path: str, qpm: int = 1_000_000, wpm: int = 100_000) -
handles, labels = axes[0].get_legend_handles_labels()
legend_ax.legend(handles, labels, loc="center", fontsize=12, title="Product")
- fig.suptitle(f"Estimated monthly cost by scale & dimension · {qpm:,} queries/mo",
- fontsize=16, weight="bold")
+ fig.suptitle(
+ f"Estimated monthly cost by scale & dimension · {qpm:,} queries/mo",
+ fontsize=16,
+ weight="bold",
+ )
fig.supxlabel("Number of vectors (log scale)")
fig.supylabel("Cost $/month (log scale)")
fig.tight_layout()
@@ -228,19 +261,31 @@ def cost_by_dimension_chart(out_path: str, scale: int = 100_000_000, qpm: int =
fig, ax = plt.subplots(figsize=(11, 6))
for p in products:
ys = [compare(Workload(scale, d, qpm, 100_000))[p] for d in DIMENSIONS]
- ax.plot(DIMENSIONS, ys, marker="s",
- color=_COLORS[p], linewidth=2.4 if p == "dynavec" else 1.4,
- label=_LABELS[p])
+ ax.plot(
+ DIMENSIONS,
+ ys,
+ marker="s",
+ color=_COLORS[p],
+ linewidth=2.4 if p == "dynavec" else 1.4,
+ label=_LABELS[p],
+ )
ax.set_yscale("log")
ax.set_xticks(DIMENSIONS)
ax.set_xlabel("Embedding dimension")
ax.set_ylabel("Cost $/month (log scale)")
- ax.set_title(f"Cost by embedding dimension @ {_fmt_count(scale)} vectors",
- fontsize=14, weight="bold")
+ ax.set_title(
+ f"Cost by embedding dimension @ {_fmt_count(scale)} vectors", fontsize=14, weight="bold"
+ )
ax.grid(True, which="both", alpha=0.25)
ax.legend()
- fig.text(0.5, -0.02, "APPROX list prices — see cost_model.py.", ha="center",
- fontsize=8, style="italic")
+ fig.text(
+ 0.5,
+ -0.02,
+ "APPROX list prices — see cost_model.py.",
+ ha="center",
+ fontsize=8,
+ style="italic",
+ )
fig.tight_layout()
fig.savefig(out_path, dpi=140, bbox_inches="tight")
plt.close(fig)
@@ -303,8 +348,10 @@ def generate(out_dir: str = "benchmarks/out", inp: ReportInputs | None = None) -
table_md = markdown_table(inp)
table_path = os.path.join(out_dir, "comparison.md")
with open(table_path, "w") as f:
- f.write(f"# dynavec benchmark comparison\n\n"
- f"_Workload: {inp.vectors:,} × {inp.dim}d, {inp.qpm:,} queries/mo._\n\n")
+ f.write(
+ f"# dynavec benchmark comparison\n\n"
+ f"_Workload: {inp.vectors:,} × {inp.dim}d, {inp.qpm:,} queries/mo._\n\n"
+ )
f.write(table_md + "\n")
bars = bar_chart(inp, os.path.join(out_dir, "quality_latency.png"))
cost = cost_scale_chart(inp, os.path.join(out_dir, "cost_by_scale.png"))
@@ -316,15 +363,21 @@ def generate(out_dir: str = "benchmarks/out", inp: ReportInputs | None = None) -
scaling_path = os.path.join(out_dir, "scaling.md")
with open(scaling_path, "w") as f:
f.write("# dynavec scaling: dimensions × vector count (100K → 1B)\n")
- f.write("\n_Cost from the cost model (APPROX public list prices). "
- "Recall/latency unaffected by this sweep._\n")
+ f.write(
+ "\n_Cost from the cost model (APPROX public list prices). "
+ "Recall/latency unaffected by this sweep._\n"
+ )
f.write(scaling_tables_md(qpm=inp.qpm))
f.write("\n")
return {
- "table_md": table_path, "bar_chart": bars, "cost_chart": cost,
- "cost_matrix": matrix, "cost_by_dimension": by_dim,
- "storage_footprint": footprint, "scaling_md": scaling_path,
+ "table_md": table_path,
+ "bar_chart": bars,
+ "cost_chart": cost,
+ "cost_matrix": matrix,
+ "cost_by_dimension": by_dim,
+ "storage_footprint": footprint,
+ "scaling_md": scaling_path,
}
diff --git a/benchmarks/run_benchmark.py b/benchmarks/run_benchmark.py
index e6e05e5..5035673 100644
--- a/benchmarks/run_benchmark.py
+++ b/benchmarks/run_benchmark.py
@@ -76,10 +76,7 @@ def __init__(self, args):
def build(self, vectors, ids):
self._id_to_index = {vid: i for i, vid in enumerate(ids)}
- docs = [
- self._Document(id=vid, vector=vectors[i].tolist())
- for i, vid in enumerate(ids)
- ]
+ docs = [self._Document(id=vid, vector=vectors[i].tolist()) for i, vid in enumerate(ids)]
# upsert in batches so we don't build one giant list in memory
B = 500
for s in range(0, len(docs), B):
@@ -91,8 +88,10 @@ def query(self, q, k):
def run(args) -> None:
- print(f"Generating synthetic dataset: {args.n:,} × {args.dim}d, "
- f"{args.queries} queries, k={args.k}")
+ print(
+ f"Generating synthetic dataset: {args.n:,} × {args.dim}d, "
+ f"{args.queries} queries, k={args.k}"
+ )
ds = make_synthetic(n=args.n, dim=args.dim, n_queries=args.queries, k=args.k)
if args.backend == "local":
@@ -122,18 +121,23 @@ def run(args) -> None:
print(f"backend : {args.backend}")
print(f"dataset : {args.n:,} vectors × {args.dim}d")
print(f"recall@{args.k:<8}: {recall:.4f}")
- print(f"latency (ms) : p50={pct['p50']:.2f} p95={pct['p95']:.2f} "
- f"p99={pct['p99']:.2f} mean={pct['mean']:.2f}")
+ print(
+ f"latency (ms) : p50={pct['p50']:.2f} p95={pct['p95']:.2f} "
+ f"p99={pct['p99']:.2f} mean={pct['mean']:.2f}"
+ )
print(f"build time : {build_s:.2f}s")
if args.backend == "local":
- print("\nNote: local backend is exact NN (recall≈1.0). Use --backend "
- "dynavec for real S3 Vectors recall & end-to-end latency.")
+ print(
+ "\nNote: local backend is exact NN (recall≈1.0). Use --backend "
+ "dynavec for real S3 Vectors recall & end-to-end latency."
+ )
print("=========================================\n")
def main() -> None:
- p = argparse.ArgumentParser(description=__doc__,
- formatter_class=argparse.RawDescriptionHelpFormatter)
+ p = argparse.ArgumentParser(
+ description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter
+ )
p.add_argument("--backend", choices=["local", "dynavec"], default="local")
p.add_argument("--n", type=int, default=10_000, help="number of vectors")
p.add_argument("--dim", type=int, default=384)
diff --git a/src/dynavec/agents/base.py b/src/dynavec/agents/base.py
index fe4e84a..ad9ecfe 100644
--- a/src/dynavec/agents/base.py
+++ b/src/dynavec/agents/base.py
@@ -119,9 +119,7 @@ def __init__(
self.fn = fn
self.name = name or fn.__name__
self.description = description or (fn.__doc__ or f"Execute {self.name}").strip()
- self.parameters = (
- parameters if parameters is not None else _generate_json_schema(fn)
- )
+ self.parameters = parameters if parameters is not None else _generate_json_schema(fn)
self.tags = tags or []
def to_chat_tool(self) -> Tool:
@@ -174,14 +172,15 @@ def execute(self, arguments: dict[str, Any] | str | None = None) -> str:
try:
parsed_args = self._parse_arguments(arguments)
kwargs = self._prepare_call(parsed_args)
-
+
if inspect.iscoroutinefunction(self.fn):
import asyncio
+
try:
loop = asyncio.get_running_loop()
except RuntimeError:
loop = None
-
+
if loop and loop.is_running():
return f"Error: Cannot execute async tool {self.name!r} synchronously in a running event loop."
result = asyncio.run(self.fn(**kwargs))
@@ -199,11 +198,12 @@ async def aexecute(self, arguments: dict[str, Any] | str | None = None) -> str:
try:
parsed_args = self._parse_arguments(arguments)
kwargs = self._prepare_call(parsed_args)
-
+
if inspect.iscoroutinefunction(self.fn):
result = await self.fn(**kwargs)
else:
import asyncio
+
result = await asyncio.to_thread(self.fn, **kwargs)
if isinstance(result, str):
diff --git a/src/dynavec/agents/connectors.py b/src/dynavec/agents/connectors.py
index debd4b9..5308efd 100644
--- a/src/dynavec/agents/connectors.py
+++ b/src/dynavec/agents/connectors.py
@@ -52,6 +52,7 @@ def http_request(
if params:
import urllib.parse
+
query_string = urllib.parse.urlencode(params)
sep = "&" if "?" in full_url else "?"
full_url = f"{full_url}{sep}{query_string}"
@@ -112,13 +113,14 @@ def python_repl(code: str) -> str:
with contextlib.redirect_stdout(out), contextlib.redirect_stderr(out):
# We use a restricted globals dict to avoid polluting the main namespace
exec_globals: dict[str, Any] = {"__builtins__": __builtins__}
-
+
import ast
+
# Parse to check if the last statement is an expression
tree = ast.parse(code)
if not tree.body:
return ""
-
+
last_node = tree.body[-1]
if isinstance(last_node, ast.Expr):
# Compile all but the last node as statements
@@ -131,10 +133,10 @@ def python_repl(code: str) -> str:
print(repr(result))
else:
exec(code, exec_globals)
-
+
except Exception:
traceback.print_exc(file=out)
-
+
return out.getvalue()
return python_repl
@@ -145,13 +147,13 @@ def mcp_tools_from_session(
tags: list[str] | None = None,
) -> list[AgentTool]:
"""Extract and adapt MCP tools from an MCP Client Session.
-
+
Args:
session: An MCP Client session exposing `list_tools()` and `call_tool(name, arguments)`.
tags: Optional tags to apply to the generated tools.
"""
listing = session.list_tools()
-
+
# Handle async listing if needed (e.g. if list_tools is a coroutine)
if hasattr(listing, "__await__"):
raise ValueError(
@@ -161,15 +163,21 @@ def mcp_tools_from_session(
tools = getattr(listing, "tools", listing)
agent_tools = []
-
+
for t in tools:
name = getattr(t, "name", None) or (t.get("name") if isinstance(t, dict) else None)
if not name:
continue
-
- description = getattr(t, "description", None) or (t.get("description") if isinstance(t, dict) else "")
- schema = getattr(t, "inputSchema", None) or getattr(t, "input_schema", None) or (t.get("inputSchema") if isinstance(t, dict) else None)
-
+
+ description = getattr(t, "description", None) or (
+ t.get("description") if isinstance(t, dict) else ""
+ )
+ schema = (
+ getattr(t, "inputSchema", None)
+ or getattr(t, "input_schema", None)
+ or (t.get("inputSchema") if isinstance(t, dict) else None)
+ )
+
# We create a closure to bind the session and name
def _make_caller(tool_name: str) -> Callable[..., str]:
def call_mcp_tool(**kwargs: Any) -> str:
@@ -180,17 +188,20 @@ def call_mcp_tool(**kwargs: Any) -> str:
if isinstance(content, (list, tuple)):
texts = []
for p in content:
- txt = getattr(p, "text", None) or (p.get("text") if isinstance(p, dict) else None)
+ txt = getattr(p, "text", None) or (
+ p.get("text") if isinstance(p, dict) else None
+ )
if txt:
texts.append(txt)
return "\n\n".join(texts)
return str(result)
+
return call_mcp_tool
-
+
fn = _make_caller(name)
fn.__name__ = name
fn.__doc__ = description
-
+
agent_tool = AgentTool(
fn=fn,
name=name,
@@ -199,7 +210,7 @@ def call_mcp_tool(**kwargs: Any) -> str:
tags=tags,
)
agent_tools.append(agent_tool)
-
+
return agent_tools
@@ -211,36 +222,45 @@ async def mcp_tools_from_session_async(
listing = await session.list_tools()
tools = getattr(listing, "tools", listing)
agent_tools = []
-
+
for t in tools:
name = getattr(t, "name", None) or (t.get("name") if isinstance(t, dict) else None)
if not name:
continue
-
- description = getattr(t, "description", None) or (t.get("description") if isinstance(t, dict) else "")
- schema = getattr(t, "inputSchema", None) or getattr(t, "input_schema", None) or (t.get("inputSchema") if isinstance(t, dict) else None)
-
+
+ description = getattr(t, "description", None) or (
+ t.get("description") if isinstance(t, dict) else ""
+ )
+ schema = (
+ getattr(t, "inputSchema", None)
+ or getattr(t, "input_schema", None)
+ or (t.get("inputSchema") if isinstance(t, dict) else None)
+ )
+
def _make_async_caller(tool_name: str) -> Callable[..., Any]:
async def acall_mcp_tool(**kwargs: Any) -> str:
result = await session.call_tool(tool_name, arguments=kwargs)
content = getattr(result, "content", result)
is_error = getattr(result, "isError", False)
prefix = "Error: " if is_error else ""
-
+
if isinstance(content, (list, tuple)):
texts = []
for p in content:
- txt = getattr(p, "text", None) or (p.get("text") if isinstance(p, dict) else None)
+ txt = getattr(p, "text", None) or (
+ p.get("text") if isinstance(p, dict) else None
+ )
if txt:
texts.append(txt)
return prefix + "\n\n".join(texts)
return prefix + str(result)
+
return acall_mcp_tool
-
+
fn = _make_async_caller(name)
fn.__name__ = name
fn.__doc__ = description
-
+
agent_tool = AgentTool(
fn=fn,
name=name,
@@ -249,5 +269,5 @@ async def acall_mcp_tool(**kwargs: Any) -> str:
tags=tags,
)
agent_tools.append(agent_tool)
-
+
return agent_tools
diff --git a/src/dynavec/agents/react.py b/src/dynavec/agents/react.py
index d8be15c..c13f13e 100644
--- a/src/dynavec/agents/react.py
+++ b/src/dynavec/agents/react.py
@@ -111,7 +111,7 @@ def _init_messages(
user_content = goal
if state is not None and state.data:
shared_context = json.dumps(state.data, default=str, sort_keys=True)
- user_content = f"{goal}\n\n" f"Shared workflow context (JSON):\n{shared_context}"
+ user_content = f"{goal}\n\nShared workflow context (JSON):\n{shared_context}"
messages.append(Message(role="user", content=user_content))
return messages
@@ -195,18 +195,10 @@ def run(
checkpoint_state = existing_cp.state
if checkpoint_state is not None:
if "messages" in checkpoint_state:
- messages = [
- _dict_to_message(m)
- for m in checkpoint_state["messages"]
- ]
+ messages = [_dict_to_message(m) for m in checkpoint_state["messages"]]
if "steps" in checkpoint_state:
- steps = [
- _dict_to_step(s)
- for s in checkpoint_state["steps"]
- ]
- total_tool_calls = int(
- checkpoint_state.get("total_tool_calls", 0)
- )
+ steps = [_dict_to_step(s) for s in checkpoint_state["steps"]]
+ total_tool_calls = int(checkpoint_state.get("total_tool_calls", 0))
start_step = existing_cp.step + 1
if not messages:
@@ -327,18 +319,10 @@ async def arun(
checkpoint_state = existing_cp.state
if checkpoint_state is not None:
if "messages" in checkpoint_state:
- messages = [
- _dict_to_message(m)
- for m in checkpoint_state["messages"]
- ]
+ messages = [_dict_to_message(m) for m in checkpoint_state["messages"]]
if "steps" in checkpoint_state:
- steps = [
- _dict_to_step(s)
- for s in checkpoint_state["steps"]
- ]
- total_tool_calls = int(
- checkpoint_state.get("total_tool_calls", 0)
- )
+ steps = [_dict_to_step(s) for s in checkpoint_state["steps"]]
+ total_tool_calls = int(checkpoint_state.get("total_tool_calls", 0))
start_step = existing_cp.step + 1
if not messages:
diff --git a/src/dynavec/agents/registry.py b/src/dynavec/agents/registry.py
index 76e09e3..606d065 100644
--- a/src/dynavec/agents/registry.py
+++ b/src/dynavec/agents/registry.py
@@ -70,9 +70,7 @@ def execute(self, name: str, arguments: dict[str, Any] | str | None = None) -> s
return f"Error: Tool {name!r} is not registered."
return t.execute(arguments)
- async def aexecute(
- self, name: str, arguments: dict[str, Any] | str | None = None
- ) -> str:
+ async def aexecute(self, name: str, arguments: dict[str, Any] | str | None = None) -> str:
"""Execute a tool by name asynchronously."""
t = self.get(name)
if not t:
@@ -98,4 +96,5 @@ def __len__(self) -> int:
def __iter__(self) -> Iterator[str]:
return iter(self._tools)
+
default_registry = ToolRegistry()
diff --git a/src/dynavec/agents/supervisor.py b/src/dynavec/agents/supervisor.py
index 06cb5eb..fc76bcf 100644
--- a/src/dynavec/agents/supervisor.py
+++ b/src/dynavec/agents/supervisor.py
@@ -69,9 +69,7 @@ def run(self, goal: str, *, state: AgentState) -> list[AgentResult]:
if self.router is not None:
if not isinstance(self.agents, dict):
- raise TypeError(
- "A router requires agents to be provided as a named dictionary."
- )
+ raise TypeError("A router requires agents to be provided as a named dictionary.")
selected = self.router(goal, state)
agent_names = [selected] if isinstance(selected, str) else selected
@@ -86,10 +84,7 @@ def run(self, goal: str, *, state: AgentState) -> list[AgentResult]:
f"Registered agents: {list(self.agents)}"
)
- return [
- self.agents[name].run(goal, state=state)
- for name in agent_names
- ]
+ return [self.agents[name].run(goal, state=state) for name in agent_names]
agents = self.agents.values() if isinstance(self.agents, dict) else self.agents
return [agent.run(goal, state=state) for agent in agents]
@@ -128,8 +123,7 @@ def handoff(
agent = self.agents.get(request.target)
if agent is None:
raise ValueError(
- f"Unknown handoff target {request.target!r}. "
- f"Registered agents: {list(self.agents)}"
+ f"Unknown handoff target {request.target!r}. Registered agents: {list(self.agents)}"
)
return agent.run(request.goal, state=state)
diff --git a/src/dynavec/async_client.py b/src/dynavec/async_client.py
index f901d45..83d277d 100644
--- a/src/dynavec/async_client.py
+++ b/src/dynavec/async_client.py
@@ -72,18 +72,11 @@ def __init__(
self._default_transform = as_pipeline(transform)
self._cache = cache
self._telemetry = telemetry
- self._hot = (
- HotTier(config)
- if config.hot_tier
- else None
- )
+ self._hot = HotTier(config) if config.hot_tier else None
self._exit_stack: AsyncExitStack | None = None
- if (
- embedder is not None
- and embedder.dimension != config.dimension
- ):
+ if embedder is not None and embedder.dimension != config.dimension:
raise ConfigurationError(
f"Embedder dimension ({embedder.dimension}) "
f"!= index dimension ({config.dimension}). "
@@ -146,10 +139,7 @@ def _require_open(self) -> None:
)
def _invalidate_cache(self, namespace: str) -> None:
- if (
- self._cache is not None
- and self.config.cache_invalidate_on_write
- ):
+ if self._cache is not None and self.config.cache_invalidate_on_write:
self._cache.invalidate(namespace)
async def _resolve_query_vector(
@@ -160,15 +150,12 @@ async def _resolve_query_vector(
if vector is not None:
if len(vector) != self.config.dimension:
raise DimensionMismatchError(
- f"Query vector dimension {len(vector)} "
- f"!= {self.config.dimension}."
+ f"Query vector dimension {len(vector)} != {self.config.dimension}."
)
return vector
if query is None:
- raise ValueError(
- "Provide either 'query' text or a 'vector'."
- )
+ raise ValueError("Provide either 'query' text or a 'vector'.")
if self.embedder is None:
raise ConfigurationError(
@@ -270,11 +257,7 @@ async def asearch_stream(
yielded = 0
- effective_page_size = (
- page_size
- if page_size is not None
- else self.config.top_k_page_size
- )
+ effective_page_size = page_size if page_size is not None else self.config.top_k_page_size
async for page in self._vectors.query_pages(
query_vector=query_vector,
@@ -336,10 +319,7 @@ async def _prepare(
list[str],
list[HotPayload],
]:
- pipeline = (
- as_pipeline(transform)
- or self._default_transform
- )
+ pipeline = as_pipeline(transform) or self._default_transform
apply_transform_pipeline(
docs,
@@ -359,9 +339,7 @@ async def _prepare(
texts = embedding_texts(to_embed)
- vectors = await self.embedder.aembed_documents(
- texts
- )
+ vectors = await self.embedder.aembed_documents(texts)
assign_embeddings(
docs,
@@ -379,10 +357,7 @@ async def _prepare(
async def aupsert(
self,
- documents: Sequence[
- Document | dict[str, Any]
- ]
- | None = None,
+ documents: Sequence[Document | dict[str, Any]] | None = None,
*,
namespace: str = "default",
auto_metadata: bool = False,
@@ -391,9 +366,7 @@ async def aupsert(
) -> UpsertResult:
"""Insert or overwrite documents asynchronously."""
if ttl_seconds is not None and ttl_seconds <= 0:
- raise ValueError(
- f"ttl_seconds must be positive, got {ttl_seconds}."
- )
+ raise ValueError(f"ttl_seconds must be positive, got {ttl_seconds}.")
if not documents:
return UpsertResult(
@@ -404,9 +377,7 @@ async def aupsert(
self._require_open()
docs = [
- document
- if isinstance(document, Document)
- else Document(**document)
+ document if isinstance(document, Document) else Document(**document)
for document in documents
]
diff --git a/src/dynavec/bm25.py b/src/dynavec/bm25.py
index ae0d4e8..1e7b373 100644
--- a/src/dynavec/bm25.py
+++ b/src/dynavec/bm25.py
@@ -19,11 +19,43 @@
_TOKEN_RE = re.compile(r"[a-zA-Z0-9]+(?:[-_.:][a-zA-Z0-9]+)*")
_SUBTOKEN_RE = re.compile(r"[a-zA-Z0-9]+")
-DEFAULT_STOPWORDS: frozenset[str] = frozenset({
- "a", "an", "and", "are", "as", "at", "be", "but", "by", "for", "if", "in",
- "into", "is", "it", "no", "not", "of", "on", "or", "such", "that", "the",
- "their", "then", "there", "these", "they", "this", "to", "was", "will", "with"
-})
+DEFAULT_STOPWORDS: frozenset[str] = frozenset(
+ {
+ "a",
+ "an",
+ "and",
+ "are",
+ "as",
+ "at",
+ "be",
+ "but",
+ "by",
+ "for",
+ "if",
+ "in",
+ "into",
+ "is",
+ "it",
+ "no",
+ "not",
+ "of",
+ "on",
+ "or",
+ "such",
+ "that",
+ "the",
+ "their",
+ "then",
+ "there",
+ "these",
+ "they",
+ "this",
+ "to",
+ "was",
+ "will",
+ "with",
+ }
+)
def default_tokenize(
diff --git a/src/dynavec/chat/anthropic.py b/src/dynavec/chat/anthropic.py
index 99c4743..28e8ab5 100644
--- a/src/dynavec/chat/anthropic.py
+++ b/src/dynavec/chat/anthropic.py
@@ -29,17 +29,13 @@ def __init__(
try:
from anthropic import Anthropic, AsyncAnthropic
except ImportError as exc:
- raise MissingDependencyError(
- "AnthropicChatModel", "anthropic", "anthropic"
- ) from exc
+ raise MissingDependencyError("AnthropicChatModel", "anthropic", "anthropic") from exc
self.model = model
self._client = Anthropic(api_key=api_key)
self._async_client = AsyncAnthropic(api_key=api_key)
- def _convert_messages(
- self, messages: list[Message]
- ) -> tuple[str, list[dict[str, Any]]]:
+ def _convert_messages(self, messages: list[Message]) -> tuple[str, list[dict[str, Any]]]:
system_prompt = ""
anthropic_msgs = []
diff --git a/src/dynavec/chat/base.py b/src/dynavec/chat/base.py
index 876c126..57ce5ee 100644
--- a/src/dynavec/chat/base.py
+++ b/src/dynavec/chat/base.py
@@ -10,80 +10,80 @@
Role = Literal["system", "user", "assistant", "tool"]
+
@dataclass
class ToolCall:
"""A tool invocation requested by the model."""
+
id: str
name: str
arguments: str # JSON string
+
@dataclass
class Message:
"""A single message in a chat conversation."""
+
role: Role
content: str | None = None
tool_calls: list[ToolCall] = field(default_factory=list)
tool_call_id: str | None = None
+
@dataclass
class Tool:
"""A tool/function specification provided to the model."""
+
name: str
description: str
parameters: dict[str, Any] # JSON schema dict
+
@dataclass
class ChatResult:
"""The final result of a chat invocation."""
+
message: Message
finish_reason: str | None = None
+
@dataclass
class ChatChunk:
"""A streamed chunk from a chat invocation."""
+
content: str | None = None
tool_calls: list[ToolCall] = field(default_factory=list)
+
class ChatModel(ABC):
"""Base class for all chat/LLM backends."""
@abstractmethod
def invoke(
- self,
- messages: list[Message],
- tools: list[Tool] | None = None,
- **kwargs: Any
+ self, messages: list[Message], tools: list[Tool] | None = None, **kwargs: Any
) -> ChatResult:
"""Invoke the chat model synchronously."""
@abstractmethod
def stream(
- self,
- messages: list[Message],
- tools: list[Tool] | None = None,
- **kwargs: Any
+ self, messages: list[Message], tools: list[Tool] | None = None, **kwargs: Any
) -> Iterator[ChatChunk]:
"""Stream the chat model response."""
async def ainvoke(
- self,
- messages: list[Message],
- tools: list[Tool] | None = None,
- **kwargs: Any
+ self, messages: list[Message], tools: list[Tool] | None = None, **kwargs: Any
) -> ChatResult:
"""Invoke the chat model asynchronously. Default delegates to thread."""
return await asyncio.to_thread(self.invoke, messages, tools, **kwargs)
async def astream(
- self,
- messages: list[Message],
- tools: list[Tool] | None = None,
- **kwargs: Any
+ self, messages: list[Message], tools: list[Tool] | None = None, **kwargs: Any
) -> AsyncIterator[ChatChunk]:
"""Stream the chat model response asynchronously. Default delegates to thread."""
+
def _sync_stream() -> list[ChatChunk]:
return list(self.stream(messages, tools, **kwargs))
-
+
chunks = await asyncio.to_thread(_sync_stream)
for chunk in chunks:
yield chunk
diff --git a/src/dynavec/chat/bedrock.py b/src/dynavec/chat/bedrock.py
index 710ecc8..9f4787b 100644
--- a/src/dynavec/chat/bedrock.py
+++ b/src/dynavec/chat/bedrock.py
@@ -34,7 +34,9 @@ def __init__(
self.model = model
self._client = boto3.client("bedrock-runtime", region_name=region_name)
- def _convert_messages(self, messages: list[Message]) -> tuple[list[dict[str, Any]], list[dict[str, Any]]]:
+ def _convert_messages(
+ self, messages: list[Message]
+ ) -> tuple[list[dict[str, Any]], list[dict[str, Any]]]:
system_prompts: list[dict[str, Any]] = []
bedrock_msgs: list[dict[str, Any]] = []
@@ -50,32 +52,35 @@ def _convert_messages(self, messages: list[Message]) -> tuple[list[dict[str, Any
if msg.tool_calls:
for tc in msg.tool_calls:
- content_blocks.append({
- "toolUse": {
- "toolUseId": tc.id,
- "name": tc.name,
- "input": json.loads(tc.arguments) if tc.arguments else {}
+ content_blocks.append(
+ {
+ "toolUse": {
+ "toolUseId": tc.id,
+ "name": tc.name,
+ "input": json.loads(tc.arguments) if tc.arguments else {},
+ }
}
- })
+ )
if msg.role == "tool" and msg.tool_call_id:
- content_blocks.append({
- "toolResult": {
- "toolUseId": msg.tool_call_id,
- "content": [{"text": msg.content or ""}],
- "status": "success"
+ content_blocks.append(
+ {
+ "toolResult": {
+ "toolUseId": msg.tool_call_id,
+ "content": [{"text": msg.content or ""}],
+ "status": "success",
+ }
}
- })
- bedrock_msgs.append({
- "role": "user",
- "content": content_blocks
- })
+ )
+ bedrock_msgs.append({"role": "user", "content": content_blocks})
continue
- bedrock_msgs.append({
- "role": "assistant" if msg.role == "assistant" else "user",
- "content": content_blocks
- })
+ bedrock_msgs.append(
+ {
+ "role": "assistant" if msg.role == "assistant" else "user",
+ "content": content_blocks,
+ }
+ )
return system_prompts, bedrock_msgs
@@ -88,9 +93,7 @@ def _convert_tools(self, tools: list[Tool] | None) -> dict[str, Any] | None:
"toolSpec": {
"name": t.name,
"description": t.description,
- "inputSchema": {
- "json": t.parameters
- }
+ "inputSchema": {"json": t.parameters},
}
}
for t in tools
@@ -103,39 +106,33 @@ def invoke(
system, bedrock_msgs = self._convert_messages(messages)
bedrock_tools = self._convert_tools(tools)
- args: dict[str, Any] = {
- "modelId": self.model,
- "messages": bedrock_msgs,
- **kwargs
- }
+ args: dict[str, Any] = {"modelId": self.model, "messages": bedrock_msgs, **kwargs}
if system:
args["system"] = system
if bedrock_tools:
args["toolConfig"] = bedrock_tools
resp = self._client.converse(**args)
-
+
output_msg = resp["output"]["message"]
role = output_msg["role"]
-
+
text_content = ""
tool_calls = []
-
+
for block in output_msg.get("content", []):
if "text" in block:
text_content += block["text"]
elif "toolUse" in block:
tu = block["toolUse"]
tool_calls.append(
- ToolCall(
- id=tu["toolUseId"],
- name=tu["name"],
- arguments=json.dumps(tu["input"])
- )
+ ToolCall(id=tu["toolUseId"], name=tu["name"], arguments=json.dumps(tu["input"]))
)
stop_reason = resp.get("stopReason")
- out = Message(role=role, content=text_content if text_content else None, tool_calls=tool_calls)
+ out = Message(
+ role=role, content=text_content if text_content else None, tool_calls=tool_calls
+ )
return ChatResult(message=out, finish_reason=stop_reason)
def stream(
@@ -144,11 +141,7 @@ def stream(
system, bedrock_msgs = self._convert_messages(messages)
bedrock_tools = self._convert_tools(tools)
- args: dict[str, Any] = {
- "modelId": self.model,
- "messages": bedrock_msgs,
- **kwargs
- }
+ args: dict[str, Any] = {"modelId": self.model, "messages": bedrock_msgs, **kwargs}
if system:
args["system"] = system
if bedrock_tools:
@@ -167,10 +160,6 @@ def stream(
elif "toolUse" in delta:
yield ChatChunk(
tool_calls=[
- ToolCall(
- id="",
- name="",
- arguments=delta["toolUse"].get("input", "")
- )
+ ToolCall(id="", name="", arguments=delta["toolUse"].get("input", ""))
]
)
diff --git a/src/dynavec/chat/openai.py b/src/dynavec/chat/openai.py
index c4aa4ab..873d39b 100644
--- a/src/dynavec/chat/openai.py
+++ b/src/dynavec/chat/openai.py
@@ -78,9 +78,7 @@ def _convert_tools(self, tools: list[Tool] | None) -> list[dict[str, Any]] | Non
]
def _format_result(self, choice: Any) -> ChatResult:
- out_msg = Message(
- role=choice.message.role or "assistant", content=choice.message.content
- )
+ out_msg = Message(role=choice.message.role or "assistant", content=choice.message.content)
if choice.message.tool_calls:
out_msg.tool_calls = [
ToolCall(
@@ -153,9 +151,7 @@ def stream(
tool_calls.append(
ToolCall(
id=tc.id or "",
- name=tc.function.name
- if (tc.function and tc.function.name)
- else "",
+ name=tc.function.name if (tc.function and tc.function.name) else "",
arguments=tc.function.arguments
if (tc.function and tc.function.arguments)
else "",
@@ -195,9 +191,7 @@ async def astream(
tool_calls.append(
ToolCall(
id=tc.id or "",
- name=tc.function.name
- if (tc.function and tc.function.name)
- else "",
+ name=tc.function.name if (tc.function and tc.function.name) else "",
arguments=tc.function.arguments
if (tc.function and tc.function.arguments)
else "",
diff --git a/src/dynavec/cli.py b/src/dynavec/cli.py
index 817b6d6..77d7539 100644
--- a/src/dynavec/cli.py
+++ b/src/dynavec/cli.py
@@ -13,297 +13,306 @@
def _parser() -> argparse.ArgumentParser:
- parser = argparse.ArgumentParser(prog="dynavec")
- subparsers = parser.add_subparsers(dest="command")
- subparsers.add_parser("version", help="show the installed dynavec version")
- doctor = subparsers.add_parser("doctor", help="check AWS credentials and resource access")
- doctor.add_argument("--bucket", help="S3 Vectors bucket name")
- doctor.add_argument("--index", help="S3 Vectors index name")
- doctor.add_argument("--table", help="DynamoDB table name")
- doctor.add_argument("--region", help="AWS region")
- doctor.add_argument("--profile", help="AWS profile name")
-
- export_cmd = subparsers.add_parser(
- "export", help="dump vectors and documents for a namespace to JSONL"
- )
- export_cmd.add_argument(
- "--namespace",
- "-n",
- default="default",
- help="namespace to export (default: 'default')",
- )
- export_cmd.add_argument(
- "--output",
- "-o",
- help="output JSONL file path (default: stdout)",
- )
- export_cmd.add_argument("--bucket", help="S3 Vectors bucket name (or DYNAVEC_VECTOR_BUCKET)")
- export_cmd.add_argument("--index", help="S3 Vectors index name (or DYNAVEC_INDEX)")
- export_cmd.add_argument("--table", help="DynamoDB table name (or DYNAVEC_TABLE)")
- export_cmd.add_argument("--dimension", type=int, help="vector dimension (default: 1536)")
- export_cmd.add_argument("--region", help="AWS region")
- export_cmd.add_argument("--profile", help="AWS profile name")
-
- import_cmd = subparsers.add_parser(
- "import", help="restore vectors and documents for a namespace from JSONL"
- )
- import_cmd.add_argument(
- "--namespace",
- "-n",
- default="default",
- help="target namespace (default: 'default')",
- )
- import_cmd.add_argument(
- "--input",
- "-i",
- help="input JSONL file path (default: stdin)",
- )
- import_cmd.add_argument(
- "--batch-size",
- type=int,
- default=100,
- help="batch size for upserting records (default: 100)",
- )
- import_cmd.add_argument("--bucket", help="S3 Vectors bucket name (or DYNAVEC_VECTOR_BUCKET)")
- import_cmd.add_argument("--index", help="S3 Vectors index name (or DYNAVEC_INDEX)")
- import_cmd.add_argument("--table", help="DynamoDB table name (or DYNAVEC_TABLE)")
- import_cmd.add_argument(
- "--dimension", type=int, help="vector dimension (inferred from input if omitted)"
- )
- import_cmd.add_argument("--region", help="AWS region")
- import_cmd.add_argument("--profile", help="AWS profile name")
-
- mcp = subparsers.add_parser("mcp", help="run the FastMCP server for AI clients")
- mcp.add_argument(
- "--transport",
- choices=["stdio", "sse"],
- default="stdio",
- help="Transport mode (default: stdio)",
- )
- mcp.add_argument(
- "--port",
- type=int,
- default=8000,
- help="Port for SSE transport (default: 8000)",
- )
- return parser
+ parser = argparse.ArgumentParser(prog="dynavec")
+ subparsers = parser.add_subparsers(dest="command")
+ subparsers.add_parser("version", help="show the installed dynavec version")
+ doctor = subparsers.add_parser("doctor", help="check AWS credentials and resource access")
+ doctor.add_argument("--bucket", help="S3 Vectors bucket name")
+ doctor.add_argument("--index", help="S3 Vectors index name")
+ doctor.add_argument("--table", help="DynamoDB table name")
+ doctor.add_argument("--region", help="AWS region")
+ doctor.add_argument("--profile", help="AWS profile name")
+
+ export_cmd = subparsers.add_parser(
+ "export", help="dump vectors and documents for a namespace to JSONL"
+ )
+ export_cmd.add_argument(
+ "--namespace",
+ "-n",
+ default="default",
+ help="namespace to export (default: 'default')",
+ )
+ export_cmd.add_argument(
+ "--output",
+ "-o",
+ help="output JSONL file path (default: stdout)",
+ )
+ export_cmd.add_argument("--bucket", help="S3 Vectors bucket name (or DYNAVEC_VECTOR_BUCKET)")
+ export_cmd.add_argument("--index", help="S3 Vectors index name (or DYNAVEC_INDEX)")
+ export_cmd.add_argument("--table", help="DynamoDB table name (or DYNAVEC_TABLE)")
+ export_cmd.add_argument("--dimension", type=int, help="vector dimension (default: 1536)")
+ export_cmd.add_argument("--region", help="AWS region")
+ export_cmd.add_argument("--profile", help="AWS profile name")
+
+ import_cmd = subparsers.add_parser(
+ "import", help="restore vectors and documents for a namespace from JSONL"
+ )
+ import_cmd.add_argument(
+ "--namespace",
+ "-n",
+ default="default",
+ help="target namespace (default: 'default')",
+ )
+ import_cmd.add_argument(
+ "--input",
+ "-i",
+ help="input JSONL file path (default: stdin)",
+ )
+ import_cmd.add_argument(
+ "--batch-size",
+ type=int,
+ default=100,
+ help="batch size for upserting records (default: 100)",
+ )
+ import_cmd.add_argument("--bucket", help="S3 Vectors bucket name (or DYNAVEC_VECTOR_BUCKET)")
+ import_cmd.add_argument("--index", help="S3 Vectors index name (or DYNAVEC_INDEX)")
+ import_cmd.add_argument("--table", help="DynamoDB table name (or DYNAVEC_TABLE)")
+ import_cmd.add_argument(
+ "--dimension", type=int, help="vector dimension (inferred from input if omitted)"
+ )
+ import_cmd.add_argument("--region", help="AWS region")
+ import_cmd.add_argument("--profile", help="AWS profile name")
+
+ mcp = subparsers.add_parser("mcp", help="run the FastMCP server for AI clients")
+ mcp.add_argument(
+ "--transport",
+ choices=["stdio", "sse"],
+ default="stdio",
+ help="Transport mode (default: stdio)",
+ )
+ mcp.add_argument(
+ "--port",
+ type=int,
+ default=8000,
+ help="Port for SSE transport (default: 8000)",
+ )
+ mcp.add_argument(
+ "--enable-write",
+ action="store_true",
+ help="Enable memory write and management tools",
+ )
+ return parser
def _session(profile: str | None, region: str | None) -> Any:
- import boto3
+ import boto3
- kwargs: dict[str, str] = {}
- if profile:
- kwargs["profile_name"] = profile
- if region:
- kwargs["region_name"] = region
- return boto3.Session(**kwargs)
+ kwargs: dict[str, str] = {}
+ if profile:
+ kwargs["profile_name"] = profile
+ if region:
+ kwargs["region_name"] = region
+ return boto3.Session(**kwargs)
def _resolve_resources(args: argparse.Namespace) -> tuple[str, str, str]:
- import os
-
- bucket = args.bucket or os.environ.get("DYNAVEC_VECTOR_BUCKET") or os.environ.get("DYNAVEC_BUCKET")
- index = args.index or os.environ.get("DYNAVEC_INDEX")
- table = args.table or os.environ.get("DYNAVEC_TABLE")
-
- missing = []
- if not bucket:
- missing.append("--bucket")
- if not index:
- missing.append("--index")
- if not table:
- missing.append("--table")
-
- if missing:
- raise ValueError(
- f"Missing required resource configuration: {', '.join(missing)} "
- "(provide via flags or DYNAVEC_* environment variables)."
- )
- return str(bucket), str(index), str(table)
+ import os
+
+ bucket = (
+ args.bucket or os.environ.get("DYNAVEC_VECTOR_BUCKET") or os.environ.get("DYNAVEC_BUCKET")
+ )
+ index = args.index or os.environ.get("DYNAVEC_INDEX")
+ table = args.table or os.environ.get("DYNAVEC_TABLE")
+
+ missing = []
+ if not bucket:
+ missing.append("--bucket")
+ if not index:
+ missing.append("--index")
+ if not table:
+ missing.append("--table")
+
+ if missing:
+ raise ValueError(
+ f"Missing required resource configuration: {', '.join(missing)} "
+ "(provide via flags or DYNAVEC_* environment variables)."
+ )
+ return str(bucket), str(index), str(table)
def _export(args: argparse.Namespace) -> int:
- try:
- bucket, index, table = _resolve_resources(args)
- except ValueError as exc:
- print(f"[FAIL] {exc}", file=sys.stderr)
- return 1
-
- session = _session(args.profile, args.region)
- dimension = args.dimension or 1536
- config = DynavecConfig(
- vector_bucket=bucket,
- index=index,
- table=table,
- dimension=dimension,
- region=args.region,
- )
- db = Dynavec(config, boto_session=session)
-
- try:
- if args.output and args.output != "-":
- count = db.export_namespace(args.output, namespace=args.namespace)
- print(f"Exported {count} documents from namespace '{args.namespace}' to {args.output}")
- else:
- count = db.export_namespace(sys.stdout, namespace=args.namespace)
- print(f"Exported {count} documents from namespace '{args.namespace}'", file=sys.stderr)
- return 0
- except Exception as exc:
- print(f"[FAIL] Export failed: {exc}", file=sys.stderr)
- return 1
+ try:
+ bucket, index, table = _resolve_resources(args)
+ except ValueError as exc:
+ print(f"[FAIL] {exc}", file=sys.stderr)
+ return 1
+
+ session = _session(args.profile, args.region)
+ dimension = args.dimension or 1536
+ config = DynavecConfig(
+ vector_bucket=bucket,
+ index=index,
+ table=table,
+ dimension=dimension,
+ region=args.region,
+ )
+ db = Dynavec(config, boto_session=session)
+
+ try:
+ if args.output and args.output != "-":
+ count = db.export_namespace(args.output, namespace=args.namespace)
+ print(f"Exported {count} documents from namespace '{args.namespace}' to {args.output}")
+ else:
+ count = db.export_namespace(sys.stdout, namespace=args.namespace)
+ print(f"Exported {count} documents from namespace '{args.namespace}'", file=sys.stderr)
+ return 0
+ except Exception as exc:
+ print(f"[FAIL] Export failed: {exc}", file=sys.stderr)
+ return 1
def _import(args: argparse.Namespace) -> int:
- import json
-
- try:
- bucket, index, table = _resolve_resources(args)
- except ValueError as exc:
- print(f"[FAIL] {exc}", file=sys.stderr)
- return 1
-
- session = _session(args.profile, args.region)
- dimension = args.dimension
-
- if dimension is None and args.input and args.input != "-":
- try:
- with open(args.input, encoding="utf-8") as f:
- for line in f:
- line = line.strip()
- if line:
- first_item = json.loads(line)
- if "vector" in first_item and isinstance(first_item["vector"], list):
- dimension = len(first_item["vector"])
- break
- except Exception:
- pass
-
- if dimension is None:
- try:
- client = session.client("s3vectors", region_name=args.region)
- idx = client.get_index(vectorBucketName=bucket, indexName=index)
- dimension = idx.get("index", {}).get("dimension")
- except Exception:
- pass
-
- if dimension is None:
- dimension = 1536
-
- config = DynavecConfig(
- vector_bucket=bucket,
- index=index,
- table=table,
- dimension=dimension,
- region=args.region,
- )
- db = Dynavec(config, boto_session=session)
-
- try:
- if args.input and args.input != "-":
- count = db.import_namespace(
- args.input, namespace=args.namespace, batch_size=args.batch_size
- )
- print(f"Imported {count} documents into namespace '{args.namespace}' from {args.input}")
- else:
- count = db.import_namespace(
- sys.stdin, namespace=args.namespace, batch_size=args.batch_size
- )
- print(f"Imported {count} documents into namespace '{args.namespace}'")
- return 0
- except Exception as exc:
- print(f"[FAIL] Import failed: {exc}", file=sys.stderr)
- return 1
+ import json
+
+ try:
+ bucket, index, table = _resolve_resources(args)
+ except ValueError as exc:
+ print(f"[FAIL] {exc}", file=sys.stderr)
+ return 1
+
+ session = _session(args.profile, args.region)
+ dimension = args.dimension
+
+ if dimension is None and args.input and args.input != "-":
+ try:
+ with open(args.input, encoding="utf-8") as f:
+ for line in f:
+ line = line.strip()
+ if line:
+ first_item = json.loads(line)
+ if "vector" in first_item and isinstance(first_item["vector"], list):
+ dimension = len(first_item["vector"])
+ break
+ except Exception:
+ pass
+
+ if dimension is None:
+ try:
+ client = session.client("s3vectors", region_name=args.region)
+ idx = client.get_index(vectorBucketName=bucket, indexName=index)
+ dimension = idx.get("index", {}).get("dimension")
+ except Exception:
+ pass
+
+ if dimension is None:
+ dimension = 1536
+
+ config = DynavecConfig(
+ vector_bucket=bucket,
+ index=index,
+ table=table,
+ dimension=dimension,
+ region=args.region,
+ )
+ db = Dynavec(config, boto_session=session)
+
+ try:
+ if args.input and args.input != "-":
+ count = db.import_namespace(
+ args.input, namespace=args.namespace, batch_size=args.batch_size
+ )
+ print(f"Imported {count} documents into namespace '{args.namespace}' from {args.input}")
+ else:
+ count = db.import_namespace(
+ sys.stdin, namespace=args.namespace, batch_size=args.batch_size
+ )
+ print(f"Imported {count} documents into namespace '{args.namespace}'")
+ return 0
+ except Exception as exc:
+ print(f"[FAIL] Import failed: {exc}", file=sys.stderr)
+ return 1
def _check(label: str, callback: Callable[[], str]) -> bool:
- try:
- detail = callback()
- except Exception as exc: # noqa: BLE001
- print(f"[FAIL] {label}\n {exc}")
- return False
- print(f"[PASS] {label}")
- if detail:
- print(f" {detail}")
- return True
+ try:
+ detail = callback()
+ except Exception as exc: # noqa: BLE001
+ print(f"[FAIL] {label}\n {exc}")
+ return False
+ print(f"[PASS] {label}")
+ if detail:
+ print(f" {detail}")
+ return True
def _doctor(args: argparse.Namespace) -> int:
- print("Dynavec doctor\n")
- session = None
- checks_passed = True
-
- def get_session() -> Any:
- nonlocal session
- if session is None:
- session = _session(args.profile, args.region)
- return session
-
- checks_passed &= _check(
- "AWS credentials / STS identity",
- lambda: _identity(get_session()),
- )
-
- if args.bucket or args.index:
- if not args.bucket or not args.index:
- print("[FAIL] S3 Vectors configuration\n --bucket and --index must be provided together")
- checks_passed = False
- else:
- checks_passed &= _check(
- f"S3 Vectors index: {args.index}",
- lambda: _check_s3vectors(get_session(), args.bucket, args.index, args.region),
- )
-
- if args.table:
- checks_passed &= _check(
- f"DynamoDB table: {args.table}",
- lambda: _check_dynamodb(get_session(), args.table, args.region),
- )
-
- print("\nDoctor checks passed." if checks_passed else "\nDoctor checks failed.")
- return 0 if checks_passed else 1
+ print("Dynavec doctor\n")
+ session = None
+ checks_passed = True
+
+ def get_session() -> Any:
+ nonlocal session
+ if session is None:
+ session = _session(args.profile, args.region)
+ return session
+
+ checks_passed &= _check(
+ "AWS credentials / STS identity",
+ lambda: _identity(get_session()),
+ )
+
+ if args.bucket or args.index:
+ if not args.bucket or not args.index:
+ print(
+ "[FAIL] S3 Vectors configuration\n --bucket and --index must be provided together"
+ )
+ checks_passed = False
+ else:
+ checks_passed &= _check(
+ f"S3 Vectors index: {args.index}",
+ lambda: _check_s3vectors(get_session(), args.bucket, args.index, args.region),
+ )
+
+ if args.table:
+ checks_passed &= _check(
+ f"DynamoDB table: {args.table}",
+ lambda: _check_dynamodb(get_session(), args.table, args.region),
+ )
+
+ print("\nDoctor checks passed." if checks_passed else "\nDoctor checks failed.")
+ return 0 if checks_passed else 1
def _identity(session: Any) -> str:
- identity = session.client("sts").get_caller_identity()
- return f"Account: {identity.get('Account', 'unknown')}"
+ identity = session.client("sts").get_caller_identity()
+ return f"Account: {identity.get('Account', 'unknown')}"
def _check_s3vectors(session: Any, bucket: str, index: str, region: str | None) -> str:
- client = session.client("s3vectors", region_name=region)
- client.get_index(vectorBucketName=bucket, indexName=index)
- return f"Bucket: {bucket}"
+ client = session.client("s3vectors", region_name=region)
+ client.get_index(vectorBucketName=bucket, indexName=index)
+ return f"Bucket: {bucket}"
def _check_dynamodb(session: Any, table: str, region: str | None) -> str:
- session.client("dynamodb", region_name=region).describe_table(TableName=table)
- return "Accessible"
+ session.client("dynamodb", region_name=region).describe_table(TableName=table)
+ return "Accessible"
def main(argv: list[str] | None = None) -> int:
- args = _parser().parse_args(argv)
- if args.command == "version":
- print(__version__)
- return 0
- if args.command == "doctor":
- return _doctor(args)
- if args.command == "export":
- return _export(args)
- if args.command == "import":
- return _import(args)
- if args.command == "mcp":
- from .mcp.server import create_mcp_server
-
- server = create_mcp_server()
- if args.transport == "sse":
- server.settings.port = args.port
- server.run(transport="sse")
- else:
- server.run(transport="stdio")
- return 0
- _parser().print_help()
- return 0
+ args = _parser().parse_args(argv)
+ if args.command == "version":
+ print(__version__)
+ return 0
+ if args.command == "doctor":
+ return _doctor(args)
+ if args.command == "export":
+ return _export(args)
+ if args.command == "import":
+ return _import(args)
+ if args.command == "mcp":
+ from .mcp.server import create_mcp_server
+
+ server = create_mcp_server(enable_write=args.enable_write)
+ if args.transport == "sse":
+ server.settings.port = args.port
+ server.run(transport="sse")
+ else:
+ server.run(transport="stdio")
+ return 0
+ _parser().print_help()
+ return 0
if __name__ == "__main__":
- sys.exit(main())
+ sys.exit(main())
diff --git a/src/dynavec/client_common.py b/src/dynavec/client_common.py
index 878510c..7485c21 100644
--- a/src/dynavec/client_common.py
+++ b/src/dynavec/client_common.py
@@ -21,11 +21,7 @@
def s3_key(namespace: str, doc_id: str) -> str:
- return (
- f"{encode_key_component(namespace)}"
- f"{KEY_SEPARATOR}"
- f"{encode_key_component(doc_id)}"
- )
+ return f"{encode_key_component(namespace)}{KEY_SEPARATOR}{encode_key_component(doc_id)}"
def split_key(key: str) -> tuple[str, str]:
@@ -63,11 +59,7 @@ def apply_transform_pipeline(
def documents_to_embed(
docs: list[Document],
) -> list[EmbeddingTarget]:
- return [
- (index, doc.text)
- for index, doc in enumerate(docs)
- if doc.vector is None
- ]
+ return [(index, doc.text) for index, doc in enumerate(docs) if doc.vector is None]
def embedding_texts(
@@ -76,15 +68,9 @@ def embedding_texts(
optional_texts = [text for _, text in targets]
if any(text is None for text in optional_texts):
- raise ConfigurationError(
- "A document has neither text nor vector."
- )
+ raise ConfigurationError("A document has neither text nor vector.")
- return [
- text
- for text in optional_texts
- if text is not None
- ]
+ return [text for text in optional_texts if text is not None]
def assign_embeddings(
@@ -94,8 +80,7 @@ def assign_embeddings(
) -> None:
if len(vectors) != len(targets):
raise ConfigurationError(
- f"Embedder returned {len(vectors)} vectors for "
- f"{len(targets)} documents."
+ f"Embedder returned {len(vectors)} vectors for {len(targets)} documents."
)
for (index, _), vector in zip(targets, vectors):
@@ -105,8 +90,7 @@ def assign_embeddings(
def single_embedding(vectors: list[list[float]], doc_id: str) -> list[float]:
if len(vectors) != 1:
raise ConfigurationError(
- f"Embedder returned {len(vectors)} vectors for 1 document "
- f"({doc_id!r})."
+ f"Embedder returned {len(vectors)} vectors for 1 document ({doc_id!r})."
)
return vectors[0]
@@ -133,10 +117,7 @@ def build_write_payloads(
vector = doc.vector
if vector is None:
- raise ConfigurationError(
- f"Embedder did not return a vector for document "
- f"{doc.id!r}."
- )
+ raise ConfigurationError(f"Embedder did not return a vector for document {doc.id!r}.")
if len(vector) != config.dimension:
raise DimensionMismatchError(
@@ -158,23 +139,14 @@ def build_write_payloads(
doc.text,
)
- doc_ttl_seconds = (
- doc.ttl_seconds
- if doc.ttl_seconds is not None
- else default_ttl_seconds
- )
+ doc_ttl_seconds = doc.ttl_seconds if doc.ttl_seconds is not None else default_ttl_seconds
if doc_ttl_seconds is not None and doc_ttl_seconds <= 0:
raise ValueError(
- f"Document {doc.id!r} ttl_seconds must be positive, "
- f"got {doc_ttl_seconds}."
+ f"Document {doc.id!r} ttl_seconds must be positive, got {doc_ttl_seconds}."
)
- ttl_timestamp = (
- int(time.time() + doc_ttl_seconds)
- if doc_ttl_seconds is not None
- else None
- )
+ ttl_timestamp = int(time.time() + doc_ttl_seconds) if doc_ttl_seconds is not None else None
if ttl_timestamp is not None:
ddb_metadata["_ttl"] = ttl_timestamp
diff --git a/src/dynavec/config.py b/src/dynavec/config.py
index bcd1fbd..57a6fef 100644
--- a/src/dynavec/config.py
+++ b/src/dynavec/config.py
@@ -158,15 +158,16 @@ def __post_init__(self) -> None:
valid_log_levels = {"DEBUG", "INFO", "WARNING", "ERROR", "CRITICAL"}
if self.log_level.upper() not in valid_log_levels:
raise ValueError(f"log_level must be one of {valid_log_levels}")
-
+
if self.dimension > 4096:
logger = logging.getLogger(__name__)
- logger.warning("Amazon S3 Vectors currently supports a maximum embedding dimension of 4096. You have configured a dimension of %d. This may result in an API error during provisioning or writing data.", self.dimension)
+ logger.warning(
+ "Amazon S3 Vectors currently supports a maximum embedding dimension of 4096. You have configured a dimension of %d. This may result in an API error during provisioning or writing data.",
+ self.dimension,
+ )
if self.put_rps is not None and self.put_rps <= 0:
raise ValueError("put_rps must be positive")
if self.query_rps is not None and self.query_rps <= 0:
raise ValueError("query_rps must be positive")
-
-
diff --git a/src/dynavec/embeddings/cache.py b/src/dynavec/embeddings/cache.py
index f65d364..05c59db 100644
--- a/src/dynavec/embeddings/cache.py
+++ b/src/dynavec/embeddings/cache.py
@@ -93,7 +93,7 @@ def __init__(self, max_size: int | None = 10_000) -> None:
def get(self, key: str) -> Vector | None:
if key not in self._store:
return None
- self._store.move_to_end(key) # mark as recently used
+ self._store.move_to_end(key) # mark as recently used
return self._store[key]
def set(self, key: str, vector: Vector) -> None:
@@ -101,7 +101,7 @@ def set(self, key: str, vector: Vector) -> None:
self._store.move_to_end(key)
else:
if self.max_size is not None and len(self._store) >= self.max_size:
- self._store.popitem(last=False) # evict LRU
+ self._store.popitem(last=False) # evict LRU
self._store[key] = vector
def __len__(self) -> int:
diff --git a/src/dynavec/embeddings/cached.py b/src/dynavec/embeddings/cached.py
index 2357c66..cd2f2e3 100644
--- a/src/dynavec/embeddings/cached.py
+++ b/src/dynavec/embeddings/cached.py
@@ -133,7 +133,4 @@ def inner(self) -> Embedder:
return self._inner
def __repr__(self) -> str:
- return (
- f"CachedEmbedder(inner={self._inner!r}, "
- f"model_key={self._model_key!r})"
- )
+ return f"CachedEmbedder(inner={self._inner!r}, model_key={self._model_key!r})"
diff --git a/src/dynavec/embeddings/huggingface.py b/src/dynavec/embeddings/huggingface.py
index 207cddf..749385d 100644
--- a/src/dynavec/embeddings/huggingface.py
+++ b/src/dynavec/embeddings/huggingface.py
@@ -30,9 +30,7 @@ def __init__(
) -> None:
"""Initialize HFInferenceEmbedder."""
self.model_name = model_name
- self.api_key = (
- api_key or os.getenv("HF_TOKEN") or os.getenv("HUGGINGFACE_TOKEN")
- )
+ self.api_key = api_key or os.getenv("HF_TOKEN") or os.getenv("HUGGINGFACE_TOKEN")
self.batch_size = batch_size
self.dimension = dimension or _MODEL_DIMS.get(model_name, 384)
@@ -41,7 +39,9 @@ def __init__(
"Hugging Face API token is required. Pass api_key or set HF_TOKEN environment variable."
)
- self.api_url = f"https://api-inference.huggingface.co/pipeline/feature-extraction/{self.model_name}"
+ self.api_url = (
+ f"https://api-inference.huggingface.co/pipeline/feature-extraction/{self.model_name}"
+ )
self.headers = {"Authorization": f"Bearer {self.api_key}"}
def embed_documents(self, texts: Sequence[str]) -> list[Vector]:
@@ -62,13 +62,9 @@ def embed_documents(self, texts: Sequence[str]) -> list[Vector]:
if response.status_code != 200:
if response.status_code in (401, 403):
- raise ValueError(
- "Invalid Hugging Face API token or unauthorized request."
- )
+ raise ValueError("Invalid Hugging Face API token or unauthorized request.")
elif response.status_code == 404:
- raise ValueError(
- f"Model '{self.model_name}' not found on Hugging Face Hub."
- )
+ raise ValueError(f"Model '{self.model_name}' not found on Hugging Face Hub.")
else:
raise RuntimeError(
f"Hugging Face API request failed ({response.status_code}): {response.text}"
diff --git a/src/dynavec/embeddings/openai.py b/src/dynavec/embeddings/openai.py
index 05ad713..8360bd8 100644
--- a/src/dynavec/embeddings/openai.py
+++ b/src/dynavec/embeddings/openai.py
@@ -18,13 +18,13 @@
"text-embedding-ada-002": 1536,
}
+
def _is_openai_retryable(exc: Exception) -> bool:
"""Return True for OpenAI rate-limit and server errors."""
status_code = getattr(exc, "status_code", None)
- return status_code == 429 or (
- isinstance(status_code, int) and 500 <= status_code < 600
- )
+ return status_code == 429 or (isinstance(status_code, int) and 500 <= status_code < 600)
+
def _openai_retry_after(exc: Exception) -> float | None:
"""Return the server-provided Retry-After delay, if available."""
@@ -88,7 +88,6 @@ def embed_documents(self, texts: list[str]) -> list[Vector]:
out.extend(d.embedding for d in resp.data)
return out
-
@retry(
retry_on=_is_openai_retryable,
retry_delay=_openai_retry_after,
@@ -98,6 +97,4 @@ def _create_embeddings(
) -> CreateEmbeddingResponse:
if dimensions is None:
return self._client.embeddings.create(model=model, input=input)
- return self._client.embeddings.create(
- model=model, input=input, dimensions=dimensions
- )
+ return self._client.embeddings.create(model=model, input=input, dimensions=dimensions)
diff --git a/src/dynavec/eval/chart.py b/src/dynavec/eval/chart.py
index 32b6140..8772436 100644
--- a/src/dynavec/eval/chart.py
+++ b/src/dynavec/eval/chart.py
@@ -229,5 +229,3 @@ def plot_retrieval_metrics(
plt.close(fig)
return output_path
-
-
diff --git a/src/dynavec/eval/trend.py b/src/dynavec/eval/trend.py
index 5d91ab0..5ad92c8 100644
--- a/src/dynavec/eval/trend.py
+++ b/src/dynavec/eval/trend.py
@@ -33,9 +33,9 @@ class EvalRun:
"""A recorded eval run with metadata tags and metric snapshots."""
run_id: str
- ts: float # epoch seconds when the run was recorded
- tags: dict[str, str] # e.g. {"dataset": "squad", "model": "ada-002"}
- metrics: dict[str, Any] # flat metric snapshot (recall@k, ndcg@k, faithfulness, …)
+ ts: float # epoch seconds when the run was recorded
+ tags: dict[str, str] # e.g. {"dataset": "squad", "model": "ada-002"}
+ metrics: dict[str, Any] # flat metric snapshot (recall@k, ndcg@k, faithfulness, …)
def to_dict(self) -> dict[str, Any]:
return {
@@ -121,7 +121,7 @@ def record(
)
self._runs.append(run)
if len(self._runs) > self._max_runs:
- self._runs = self._runs[-self._max_runs:]
+ self._runs = self._runs[-self._max_runs :]
return run
# ------------------------------------------------------------------ filter
diff --git a/src/dynavec/fusion.py b/src/dynavec/fusion.py
index 5e73b99..b17d63b 100644
--- a/src/dynavec/fusion.py
+++ b/src/dynavec/fusion.py
@@ -35,6 +35,7 @@
# FitResult
# ---------------------------------------------------------------------------
+
@dataclass
class FitResult:
"""Result of an ``RRFWeightFitter.fit()`` call.
@@ -85,6 +86,7 @@ def load(cls, path: str | Path) -> FitResult:
# RRFWeightFitter
# ---------------------------------------------------------------------------
+
class RRFWeightFitter:
"""Learn per-retriever RRF weights from labeled evaluation queries.
@@ -125,10 +127,7 @@ def score(self, weights: list[float]) -> float:
for query_idx, labeled_query in enumerate(self.labeled_queries):
# result_lists[retriever_idx][query_idx] → list[SearchResult]
- per_retriever = [
- self.result_lists[r][query_idx]
- for r in range(len(self.result_lists))
- ]
+ per_retriever = [self.result_lists[r][query_idx] for r in range(len(self.result_lists))]
fused = reciprocal_rank_fusion(per_retriever, k=self.k, weights=weights)
ranked_ids = [r.id for r in fused]
@@ -241,7 +240,9 @@ def _neg_ndcg(x: np.ndarray) -> float:
best_w = _softmax(result.x)
best_score = -float(result.fun)
- return FitResult(weights=best_w, score=best_score, method="bayesian", n_evaluations=eval_count)
+ return FitResult(
+ weights=best_w, score=best_score, method="bayesian", n_evaluations=eval_count
+ )
# -- public API ----------------------------------------------------------
diff --git a/src/dynavec/graph.py b/src/dynavec/graph.py
index 78b61bf..534e8dd 100644
--- a/src/dynavec/graph.py
+++ b/src/dynavec/graph.py
@@ -105,9 +105,7 @@ def _mermaid_aliases(nodes: list[str]) -> dict[str, str]:
reserved keyword) gets an `nN` alias carrying the real id as its label.
Alias numbering follows sorted id order, so it is stable across exports.
"""
- bare = {
- n for n in nodes if _MERMAID_SAFE_ID.match(n) and n.lower() not in _MERMAID_RESERVED
- }
+ bare = {n for n in nodes if _MERMAID_SAFE_ID.match(n) and n.lower() not in _MERMAID_RESERVED}
aliases: dict[str, str] = {}
counter = 0
for node in nodes:
@@ -368,8 +366,7 @@ def _drop_edges(self, ns: str, src: str, dst: str, relation: str | None = None)
edge
for edge in edges
if not (
- edge.get("target") == dst
- and (relation is None or edge.get("relation") == relation)
+ edge.get("target") == dst and (relation is None or edge.get("relation") == relation)
)
]
if len(kept) == len(edges):
diff --git a/src/dynavec/integrations/dspy.py b/src/dynavec/integrations/dspy.py
index 821ed83..041d819 100644
--- a/src/dynavec/integrations/dspy.py
+++ b/src/dynavec/integrations/dspy.py
@@ -1,13 +1,13 @@
"""DSPy retrieval module backed by dynavec.
- import dspy
- from dynavec.integrations.dspy import DynavecRM
+import dspy
+from dynavec.integrations.dspy import DynavecRM
- rm = DynavecRM(dynavec_client, namespace="kb", k=4)
- dspy.configure(rm=rm)
+rm = DynavecRM(dynavec_client, namespace="kb", k=4)
+dspy.configure(rm=rm)
- retriever = dspy.Retrieve(k=4)
- passages = retriever("what is retrieval-augmented generation?").passages
+retriever = dspy.Retrieve(k=4)
+passages = retriever("what is retrieval-augmented generation?").passages
"""
from __future__ import annotations
diff --git a/src/dynavec/integrations/haystack.py b/src/dynavec/integrations/haystack.py
index 247ec4e..7846e07 100644
--- a/src/dynavec/integrations/haystack.py
+++ b/src/dynavec/integrations/haystack.py
@@ -1,4 +1,5 @@
"""Haystack integration for Dynavec."""
+
from __future__ import annotations
from dataclasses import asdict
@@ -38,8 +39,11 @@ def _convert_filter(
return {field: filters["value"]}
return filters
+
+
class DynavecDocumentStore:
"""Haystack DocumentStore backed by Dynavec."""
+
def __init__(self, client: Dynavec, namespace: str = "default") -> None:
self.client = client
self.namespace = namespace
@@ -53,6 +57,7 @@ def count_documents(self) -> int:
hydrate=False,
)
)
+
def write_documents(
self,
documents: list[Document],
@@ -77,9 +82,7 @@ def write_documents(
elif policy == DuplicatePolicy.FAIL:
duplicates = [document.id for document in documents if document.id in existing]
if duplicates:
- raise DuplicateDocumentError(
- f"Documents with IDs already exist: {duplicates}"
- )
+ raise DuplicateDocumentError(f"Documents with IDs already exist: {duplicates}")
dynavec_documents = [
DynavecDocument(
@@ -111,8 +114,7 @@ def filter_documents(
namespace=self.namespace,
hydrate=True,
):
- if filters and any(result.metadata.get(key) != value for key, value in filters.items()
- ):
+ if filters and any(result.metadata.get(key) != value for key, value in filters.items()):
continue
documents.append(
@@ -134,8 +136,7 @@ def to_dict(self) -> dict[str, Any]:
"config": asdict(self.client.config),
"namespace": self.namespace,
},
- }
-
+ }
@classmethod
def from_dict(cls, data: dict[str, Any]) -> DynavecDocumentStore:
@@ -151,7 +152,6 @@ def from_dict(cls, data: dict[str, Any]) -> DynavecDocumentStore:
)
-
class DynavecRetriever:
"""Haystack retriever backed by Dynavec."""
diff --git a/src/dynavec/integrations/langchain.py b/src/dynavec/integrations/langchain.py
index bafaf2e..96f7cbc 100644
--- a/src/dynavec/integrations/langchain.py
+++ b/src/dynavec/integrations/langchain.py
@@ -70,10 +70,7 @@ def add_texts(
texts = list(texts)
ids = ids or [str(uuid.uuid4()) for _ in texts]
metadatas = metadatas or [{} for _ in texts]
- docs = [
- DVDocument(id=i, text=t, metadata=m)
- for i, t, m in zip(ids, texts, metadatas)
- ]
+ docs = [DVDocument(id=i, text=t, metadata=m) for i, t, m in zip(ids, texts, metadatas)]
self._client.upsert(docs, namespace=self._namespace)
return ids
@@ -86,11 +83,11 @@ def delete(self, ids: list[str] | None = None, **kwargs: Any) -> bool | None:
def similarity_search(
self, query: str, k: int = 4, filter: dict[str, Any] | None = None, **kwargs: Any
) -> list[LCDocument]:
- results = self._client.search(
- query, top_k=k, namespace=self._namespace, filter=filter
- )
+ results = self._client.search(query, top_k=k, namespace=self._namespace, filter=filter)
return [
- LCDocument(page_content=r.text or "", metadata={**r.metadata, "id": r.id, "score": r.score})
+ LCDocument(
+ page_content=r.text or "", metadata={**r.metadata, "id": r.id, "score": r.score}
+ )
for r in results
]
@@ -119,9 +116,7 @@ async def asimilarity_search(
def similarity_search_with_score(
self, query: str, k: int = 4, filter: dict[str, Any] | None = None, **kwargs: Any
) -> list[tuple[LCDocument, float]]:
- results = self._client.search(
- query, top_k=k, namespace=self._namespace, filter=filter
- )
+ results = self._client.search(query, top_k=k, namespace=self._namespace, filter=filter)
return [
(
LCDocument(page_content=r.text or "", metadata={**r.metadata, "id": r.id}),
@@ -173,7 +168,9 @@ def max_marginal_relevance_search(
mmr_lambda=lambda_mult,
)
return [
- LCDocument(page_content=r.text or "", metadata={**r.metadata, "id": r.id, "score": r.score})
+ LCDocument(
+ page_content=r.text or "", metadata={**r.metadata, "id": r.id, "score": r.score}
+ )
for r in results
]
diff --git a/src/dynavec/integrations/llamaindex.py b/src/dynavec/integrations/llamaindex.py
index 8443ff6..55f9d14 100644
--- a/src/dynavec/integrations/llamaindex.py
+++ b/src/dynavec/integrations/llamaindex.py
@@ -86,8 +86,7 @@ def _translate_filters(metadata_filters: MetadataFilters) -> dict[str, Any]:
return {"$or": translated}
raise ValueError(
- "Unsupported LlamaIndex metadata filter condition for S3 Vectors: "
- f"{condition.value}"
+ f"Unsupported LlamaIndex metadata filter condition for S3 Vectors: {condition.value}"
)
diff --git a/src/dynavec/mcp/__init__.py b/src/dynavec/mcp/__init__.py
index 0df5c80..fe39777 100644
--- a/src/dynavec/mcp/__init__.py
+++ b/src/dynavec/mcp/__init__.py
@@ -9,4 +9,3 @@
from .server import client_from_env, create_mcp_server, main
__all__ = ["client_from_env", "create_mcp_server", "main"]
-
diff --git a/src/dynavec/mcp/server.py b/src/dynavec/mcp/server.py
index af2d9df..fa7daec 100644
--- a/src/dynavec/mcp/server.py
+++ b/src/dynavec/mcp/server.py
@@ -6,6 +6,7 @@
import json
import os
import sys
+import uuid
from collections.abc import Mapping
from typing import Any, cast
@@ -13,6 +14,7 @@
from ..config import DistanceMetric, DynavecConfig
from ..embeddings.base import Embedder
from ..exceptions import ConfigurationError, MissingDependencyError
+from ..models import Document
def _resolve_embedder(env: Mapping[str, str]) -> Embedder | None:
@@ -37,7 +39,9 @@ def _resolve_embedder(env: Mapping[str, str]) -> Embedder | None:
if embedder_type == "openai":
from ..embeddings.openai import OpenAIEmbedder
- return OpenAIEmbedder(model=model or "text-embedding-3-small", api_key=env.get("OPENAI_API_KEY"))
+ return OpenAIEmbedder(
+ model=model or "text-embedding-3-small", api_key=env.get("OPENAI_API_KEY")
+ )
if embedder_type == "gemini":
from ..embeddings.gemini import GeminiEmbedder
@@ -124,7 +128,11 @@ def _format_hits(hits: list[Any], query: str, context_label: str = "") -> str:
return "\n".join(lines).strip()
-def create_mcp_server(db: Dynavec | None = None, name: str = "dynavec") -> Any:
+def create_mcp_server(
+ db: Dynavec | None = None,
+ name: str = "dynavec",
+ enable_write: bool = False,
+) -> Any:
"""Create and configure a FastMCP server exposing dynavec search and graph search tools."""
try:
from mcp.server.fastmcp import FastMCP
@@ -136,6 +144,100 @@ def create_mcp_server(db: Dynavec | None = None, name: str = "dynavec") -> Any:
def _get_db() -> Dynavec:
return db if db is not None else client_from_env()
+ def dynavec_remember(
+ text: str,
+ doc_id: str | None = None,
+ namespace: str = "default",
+ metadata_json: str | None = None,
+ ttl_seconds: int | None = None,
+ ) -> str:
+ """Store a memory document in the Dynavec database."""
+ try:
+ if not text.strip():
+ return "Error remembering document: text cannot be empty"
+
+ metadata: dict[str, Any] = {}
+
+ if metadata_json:
+ try:
+ parsed: object = json.loads(metadata_json)
+
+ if not isinstance(parsed, dict):
+ return "Error parsing metadata_json: expected a JSON object"
+
+ metadata = cast(dict[str, Any], parsed)
+
+ except (json.JSONDecodeError, TypeError) as exc:
+ return f"Error parsing metadata_json: {exc}"
+
+ document_id = doc_id or str(uuid.uuid4())
+
+ document = Document(
+ id=document_id,
+ text=text,
+ metadata=metadata,
+ ttl_seconds=ttl_seconds,
+ )
+
+ client = _get_db()
+
+ client.upsert(
+ [document],
+ namespace=namespace,
+ ttl_seconds=ttl_seconds,
+ )
+
+ return f"Successfully remembered document '{document_id}'."
+
+ except Exception as exc:
+ return f"Error remembering document: {exc}"
+
+ def dynavec_get(
+ ids: list[str],
+ namespace: str = "default",
+ ) -> str:
+ """Retrieve stored memory documents by their IDs."""
+ try:
+ if not ids:
+ return "Error retrieving documents: ids cannot be empty"
+
+ client = _get_db()
+ documents = client.get(ids, namespace)
+
+ if not documents:
+ return "No documents found."
+
+ lines = []
+
+ for document in documents:
+ lines.append(
+ f"ID: {document.id}\n"
+ f"Text: {document.text or ''}\n"
+ f"Metadata: {json.dumps(document.metadata, default=str)}"
+ )
+
+ return "\n\n".join(lines)
+
+ except Exception as exc:
+ return f"Error retrieving documents: {exc}"
+
+ def dynavec_forget(
+ ids: list[str],
+ namespace: str = "default",
+ ) -> str:
+ """Delete stored memory documents by their IDs."""
+ try:
+ if not ids:
+ return "Error deleting documents: ids cannot be empty"
+
+ client = _get_db()
+ client.delete(ids, namespace)
+
+ return f"Successfully deleted {len(ids)} document(s) from namespace '{namespace}'."
+
+ except Exception as exc:
+ return f"Error deleting documents: {exc}"
+
def dynavec_search(
query: str,
top_k: int = 5,
@@ -214,14 +316,23 @@ def dynavec_graph_search(
)
return _format_hits(hits, query, f" (seeds: {seed_entities}, hops: {hops})")
+ # Register existing MCP tools
mcp.tool()(dynavec_search)
mcp.tool()(dynavec_graph_search)
+
+ if enable_write:
+ mcp.tool()(dynavec_remember)
+ mcp.tool()(dynavec_get)
+ mcp.tool()(dynavec_forget)
+
return mcp
def main(argv: list[str] | None = None) -> int:
"""Run the FastMCP server with stdio or SSE transport."""
- parser = argparse.ArgumentParser(prog="dynavec mcp", description="Run the dynavec FastMCP server.")
+ parser = argparse.ArgumentParser(
+ prog="dynavec mcp", description="Run the dynavec FastMCP server."
+ )
parser.add_argument(
"--transport",
choices=["stdio", "sse"],
@@ -234,9 +345,15 @@ def main(argv: list[str] | None = None) -> int:
default=8000,
help="Port for SSE transport (default: 8000)",
)
+ parser.add_argument(
+ "--enable-write",
+ action="store_true",
+ help="Enable memory write and management tools",
+ )
args = parser.parse_args(argv)
- server = create_mcp_server()
+ server = create_mcp_server(enable_write=args.enable_write)
+
if args.transport == "sse":
server.settings.port = args.port
server.run(transport="sse")
diff --git a/src/dynavec/models.py b/src/dynavec/models.py
index 3d34bb0..db29545 100644
--- a/src/dynavec/models.py
+++ b/src/dynavec/models.py
@@ -25,9 +25,7 @@ class Document:
def __post_init__(self) -> None:
if self.text is None and self.vector is None:
- raise ValueError(
- f"Document {self.id!r} must have either 'text' or 'vector' set."
- )
+ raise ValueError(f"Document {self.id!r} must have either 'text' or 'vector' set.")
if self.ttl_seconds is not None and self.ttl_seconds <= 0:
raise ValueError(
f"Document {self.id!r} ttl_seconds must be positive, got {self.ttl_seconds}."
diff --git a/src/dynavec/namespace.py b/src/dynavec/namespace.py
index 45d6c6e..7fa91ac 100644
--- a/src/dynavec/namespace.py
+++ b/src/dynavec/namespace.py
@@ -38,9 +38,7 @@ def upsert(
ttl_seconds: int | None = None,
**kw: Any,
) -> UpsertResult:
- return self._db.upsert(
- documents, namespace=self._ns, ttl_seconds=ttl_seconds, **kw
- )
+ return self._db.upsert(documents, namespace=self._ns, ttl_seconds=ttl_seconds, **kw)
def update(
self,
diff --git a/src/dynavec/nodes/graph.py b/src/dynavec/nodes/graph.py
index b7c6684..54195e4 100644
--- a/src/dynavec/nodes/graph.py
+++ b/src/dynavec/nodes/graph.py
@@ -168,8 +168,7 @@ def run(
state: GraphRunState | dict[str, Any] | None = None,
return_state: Literal[False] = False,
raise_on_failure: bool = True,
- ) -> dict[str, Any]:
- ...
+ ) -> dict[str, Any]: ...
@overload
def run(
@@ -178,8 +177,7 @@ def run(
state: GraphRunState | dict[str, Any] | None = None,
return_state: Literal[True] = ...,
raise_on_failure: bool = True,
- ) -> GraphRunState:
- ...
+ ) -> GraphRunState: ...
@overload
def run(
@@ -188,8 +186,7 @@ def run(
state: GraphRunState | dict[str, Any] | None = None,
return_state: bool = False,
raise_on_failure: bool = True,
- ) -> dict[str, Any] | GraphRunState:
- ...
+ ) -> dict[str, Any] | GraphRunState: ...
def run(
self,
diff --git a/src/dynavec/quantization.py b/src/dynavec/quantization.py
index 2ba26a1..87105f6 100644
--- a/src/dynavec/quantization.py
+++ b/src/dynavec/quantization.py
@@ -264,9 +264,7 @@ def encode(self, vectors: np.ndarray) -> np.ndarray:
if vectors.ndim != 2:
raise ValueError("vectors must be a 2D array")
- codes = np.round(
- (vectors - mins) / scales - 128
- )
+ codes = np.round((vectors - mins) / scales - 128)
return np.asarray(np.clip(codes, -128, 127), dtype=np.int8)
@@ -276,8 +274,7 @@ def decode(self, codes: np.ndarray) -> np.ndarray:
codes = np.asarray(codes, dtype=np.int8)
return np.asarray(
- (codes.astype(np.float32) + 128) * scales
- + mins,
+ (codes.astype(np.float32) + 128) * scales + mins,
dtype=np.float32,
)
@@ -315,15 +312,11 @@ def fit(self, vectors: np.ndarray) -> OPQRotation:
raise ValueError("vectors must be a 2D array")
if x.shape[1] != self.dim:
- raise ValueError(
- f"Expected dimension={self.dim}, got {x.shape[1]}"
- )
+ raise ValueError(f"Expected dimension={self.dim}, got {x.shape[1]}")
rng = np.random.default_rng(self.seed)
- random_matrix = rng.normal(
- size=(self.dim, self.dim)
- ).astype(np.float32)
+ random_matrix = rng.normal(size=(self.dim, self.dim)).astype(np.float32)
q, _ = np.linalg.qr(random_matrix)
@@ -349,12 +342,9 @@ def inverse_transform(self, vectors: np.ndarray) -> np.ndarray:
def _fitted_rotation(self) -> np.ndarray:
if self._rotation is None:
- raise RuntimeError(
- "OPQRotation must be .fit() before use"
- )
+ raise RuntimeError("OPQRotation must be .fit() before use")
return self._rotation
-
def _update_rotation(
self,
original: np.ndarray,
@@ -402,9 +392,7 @@ def fit(self, vectors: np.ndarray) -> OptimizedProductQuantizer:
self._dim = x.shape[1]
if self._dim % self.m != 0:
- raise ValueError(
- f"m={self.m} must divide dimension={self._dim}"
- )
+ raise ValueError(f"m={self.m} must divide dimension={self._dim}")
self._opq = OPQRotation(
dim=self._dim,
@@ -428,11 +416,7 @@ def fit(self, vectors: np.ndarray) -> OptimizedProductQuantizer:
codes = self._pq.encode(rotated)
reconstructed = self._pq.decode(codes)
- error = float(
- ((rotated - reconstructed) ** 2)
- .sum(axis=1)
- .mean()
- )
+ error = float(((rotated - reconstructed) ** 2).sum(axis=1).mean())
self._training_errors.append(error)
self._opq._update_rotation(
@@ -464,9 +448,7 @@ def asymmetric_distances(
) -> np.ndarray:
pq, opq = self._fitted_components()
- rotated_query = opq.transform(
- np.asarray(query, dtype=np.float32)
- )
+ rotated_query = opq.transform(np.asarray(query, dtype=np.float32))
return pq.asymmetric_distances(
rotated_query,
@@ -476,15 +458,9 @@ def asymmetric_distances(
def reconstruction_error(self, vectors: np.ndarray) -> float:
x = np.asarray(vectors, dtype=np.float32)
- reconstructed = self.decode(
- self.encode(x)
- )
+ reconstructed = self.decode(self.encode(x))
- return float(
- ((x - reconstructed) ** 2)
- .sum(axis=1)
- .mean()
- )
+ return float(((x - reconstructed) ** 2).sum(axis=1).mean())
@property
def training_errors(self) -> list[float]:
@@ -493,7 +469,5 @@ def training_errors(self) -> list[float]:
def _fitted_components(self) -> tuple[ProductQuantizer, OPQRotation]:
if self._pq is None or self._opq is None:
- raise RuntimeError(
- "OptimizedProductQuantizer must be .fit() before use"
- )
+ raise RuntimeError("OptimizedProductQuantizer must be .fit() before use")
return self._pq, self._opq
diff --git a/src/dynavec/retrievers.py b/src/dynavec/retrievers.py
index 79005cb..6cf6209 100644
--- a/src/dynavec/retrievers.py
+++ b/src/dynavec/retrievers.py
@@ -600,7 +600,9 @@ def __init__(
if hasattr(weights, "weights"):
weights = weights.weights
if len(weights) != 2:
- raise ValueError("weights must contain exactly 2 elements [dense_weight, sparse_weight]")
+ raise ValueError(
+ "weights must contain exactly 2 elements [dense_weight, sparse_weight]"
+ )
dense_weight, sparse_weight = float(weights[0]), float(weights[1])
if dense_weight <= 0 or sparse_weight <= 0:
@@ -668,7 +670,9 @@ def search(
if hasattr(weights, "weights"):
weights = weights.weights
if len(weights) != 2:
- raise ValueError("weights must contain exactly 2 elements [dense_weight, sparse_weight]")
+ raise ValueError(
+ "weights must contain exactly 2 elements [dense_weight, sparse_weight]"
+ )
w_dense, w_sparse = float(weights[0]), float(weights[1])
# Run dense vector search and sparse BM25 search in parallel
diff --git a/src/dynavec/stores/async_dynamodb.py b/src/dynavec/stores/async_dynamodb.py
index 496cdcb..4469c39 100644
--- a/src/dynavec/stores/async_dynamodb.py
+++ b/src/dynavec/stores/async_dynamodb.py
@@ -124,8 +124,7 @@ async def put_many(
self,
namespace: str,
items: Sequence[
- tuple[str, str | None, Metadata]
- | tuple[str, str | None, Metadata, int | None]
+ tuple[str, str | None, Metadata] | tuple[str, str | None, Metadata, int | None]
],
) -> None:
"""Upsert document tuples using DynamoDB's async batch writer."""
@@ -195,10 +194,7 @@ async def get_many(
ddb = self._require_ddb()
- keys = [
- {"pk": self._pk(namespace, doc_id)}
- for doc_id in ids
- ]
+ keys = [{"pk": self._pk(namespace, doc_id)} for doc_id in ids]
out: dict[str, dict[str, Any]] = {}
@@ -222,9 +218,7 @@ async def get_many(
):
entry: dict[str, Any] = {
"text": _read_text(item),
- "metadata": _from_dynamo(
- item.get("metadata", {})
- ),
+ "metadata": _from_dynamo(item.get("metadata", {})),
}
ttl_attr = self._config.dynamodb_ttl_attribute
@@ -233,15 +227,9 @@ async def get_many(
out[item["id"]] = entry
- unprocessed = (
- response.get("UnprocessedKeys") or {}
- )
+ unprocessed = response.get("UnprocessedKeys") or {}
- request = (
- unprocessed
- if unprocessed
- else None
- )
+ request = unprocessed if unprocessed else None
log_store_event(
self._logger,
diff --git a/src/dynavec/stores/async_s3vectors.py b/src/dynavec/stores/async_s3vectors.py
index f3fd66e..03eede0 100644
--- a/src/dynavec/stores/async_s3vectors.py
+++ b/src/dynavec/stores/async_s3vectors.py
@@ -24,15 +24,9 @@ class AsyncS3VectorsStore:
def __init__(self, config: DynavecConfig, boto_session: Any) -> None:
self._config = config
self._session = boto_session
- self._put_limiter = (
- TokenBucket(config.put_rps)
- if config.put_rps is not None
- else None
- )
+ self._put_limiter = TokenBucket(config.put_rps) if config.put_rps is not None else None
self._query_limiter = (
- TokenBucket(config.query_rps)
- if config.query_rps is not None
- else None
+ TokenBucket(config.query_rps) if config.query_rps is not None else None
)
self._client_context: Any | None = None
self._client: Any | None = None
@@ -119,10 +113,7 @@ async def put_vectors(
raise ValueError("max_workers must be greater than 0.")
t0 = time.perf_counter()
- chunks = [
- vectors[i : i + _PUT_LIMIT]
- for i in range(0, len(vectors), _PUT_LIMIT)
- ]
+ chunks = [vectors[i : i + _PUT_LIMIT] for i in range(0, len(vectors), _PUT_LIMIT)]
semaphore = asyncio.Semaphore(min(max_workers, len(chunks)))
@@ -141,10 +132,7 @@ async def upload_chunk(
async with semaphore:
await self._put_batch(payload)
- tasks = [
- asyncio.create_task(upload_chunk(chunk))
- for chunk in chunks
- ]
+ tasks = [asyncio.create_task(upload_chunk(chunk)) for chunk in chunks]
try:
await asyncio.gather(*tasks)
@@ -166,7 +154,6 @@ async def upload_chunk(
duration_ms=round((time.perf_counter() - t0) * 1000, 2),
)
-
def _query_kwargs(
self,
query_vector: list[float],
@@ -215,8 +202,7 @@ async def query(
if top_k > _MAX_TOP_K:
raise ValueError(
- f"top_k ({top_k}) exceeds Amazon S3 Vectors "
- f"maximum limit of {_MAX_TOP_K}."
+ f"top_k ({top_k}) exceeds Amazon S3 Vectors maximum limit of {_MAX_TOP_K}."
)
results: list[dict[str, Any]] = []
@@ -263,15 +249,10 @@ async def query_pages(
if top_k > _MAX_TOP_K:
raise ValueError(
- f"top_k ({top_k}) exceeds Amazon S3 Vectors "
- f"maximum limit of {_MAX_TOP_K}."
+ f"top_k ({top_k}) exceeds Amazon S3 Vectors maximum limit of {_MAX_TOP_K}."
)
- effective_page_size = (
- page_size
- if page_size is not None
- else self._config.top_k_page_size
- )
+ effective_page_size = page_size if page_size is not None else self._config.top_k_page_size
if effective_page_size is not None and effective_page_size <= 0:
raise ValueError("page_size must be a positive integer.")
@@ -324,10 +305,7 @@ async def query_pages(
else:
buffer.extend(vectors)
- while (
- len(buffer) >= effective_page_size
- and yielded < top_k
- ):
+ while len(buffer) >= effective_page_size and yielded < top_k:
chunk = buffer[:effective_page_size]
buffer = buffer[effective_page_size:]
@@ -345,15 +323,10 @@ async def query_pages(
if page.get("NextToken") is None:
break
- if (
- effective_page_size is not None
- and buffer
- and yielded < top_k
- ):
+ if effective_page_size is not None and buffer and yielded < top_k:
remaining = top_k - yielded
yield buffer[:remaining]
-
@async_retry()
async def get_vectors(
self,
diff --git a/src/dynavec/stores/s3vectors.py b/src/dynavec/stores/s3vectors.py
index 79fb276..c4dd8a9 100644
--- a/src/dynavec/stores/s3vectors.py
+++ b/src/dynavec/stores/s3vectors.py
@@ -46,9 +46,7 @@ def __init__(self, config: DynavecConfig, boto_session: Any | None = None) -> No
session = boto_session or boto3.Session()
self._config = config
- self._put_limiter = (
- TokenBucket(config.put_rps) if config.put_rps is not None else None
- )
+ self._put_limiter = TokenBucket(config.put_rps) if config.put_rps is not None else None
self._query_limiter = (
TokenBucket(config.query_rps) if config.query_rps is not None else None
)
@@ -78,7 +76,6 @@ def _put_batch(self, payload: list[dict[str, Any]]) -> None:
vectors=payload,
)
-
def put_vectors(
self,
vectors: list[tuple[str, list[float], Metadata]],
@@ -215,9 +212,7 @@ def query_pages(
f"top_k ({top_k}) exceeds Amazon S3 Vectors maximum limit of {_MAX_TOP_K}."
)
- effective_page_size = (
- page_size if page_size is not None else self._config.top_k_page_size
- )
+ effective_page_size = page_size if page_size is not None else self._config.top_k_page_size
if effective_page_size is not None and effective_page_size <= 0:
raise ValueError("page_size must be a positive integer.")
@@ -313,9 +308,7 @@ def list_pages(
leaves the page size to Amazon S3 Vectors.
"""
if page_size is not None and not _LIST_PAGE_MIN <= page_size <= _LIST_PAGE_MAX:
- raise ValueError(
- f"page_size must be between {_LIST_PAGE_MIN} and {_LIST_PAGE_MAX}."
- )
+ raise ValueError(f"page_size must be between {_LIST_PAGE_MIN} and {_LIST_PAGE_MAX}.")
kwargs: dict[str, Any] = {
"vectorBucketName": self._config.vector_bucket,
diff --git a/src/dynavec/utils.py b/src/dynavec/utils.py
index 70e8715..9d5199f 100644
--- a/src/dynavec/utils.py
+++ b/src/dynavec/utils.py
@@ -28,6 +28,7 @@ def decode_key_component(value: str) -> str:
"""Restore a component produced by :func:`encode_key_component`."""
return value.replace("%23", KEY_SEPARATOR).replace("%25", "%")
+
# botocore error codes that are safe to retry (throttling / transient).
_RETRYABLE_CODES = frozenset(
{
@@ -181,7 +182,6 @@ def __init__(
self.last_time = time.monotonic()
self._lock = threading.Lock()
-
def _acquire_wait_time(self) -> float | None:
with self._lock:
now = time.monotonic()
diff --git a/tests/integration/test_live_aws.py b/tests/integration/test_live_aws.py
index bee083c..2d0f79c 100644
--- a/tests/integration/test_live_aws.py
+++ b/tests/integration/test_live_aws.py
@@ -97,7 +97,7 @@ def test_provision_upsert_search_roundtrip(live_db):
hits = _query_with_retry(live_db, vecs[0].tolist(), top_k=5)
assert hits, "no results returned from live S3 Vectors index"
assert hits[0].id == "v0"
- assert hits[0].text == "document number 0" # hydrated from DynamoDB
+ assert hits[0].text == "document number 0" # hydrated from DynamoDB
# metadata pre-filter must scope results
even_hits = _query_with_retry(live_db, vecs[0].tolist(), top_k=10, filter={"even": True})
@@ -110,7 +110,9 @@ def test_update_and_delete(live_db):
rng = np.random.default_rng(1)
v = _unit(rng, 1, DIM)[0].tolist()
- live_db.upsert([Document(id="u1", vector=v, text="original", metadata={"tag": "a"})], namespace="it")
+ live_db.upsert(
+ [Document(id="u1", vector=v, text="original", metadata={"tag": "a"})], namespace="it"
+ )
live_db.update("u1", namespace="it", metadata={"tag": "b"}, merge_metadata=False)
got = live_db.get(["u1"], namespace="it")[0]
diff --git a/tests/test_async_client.py b/tests/test_async_client.py
index c625910..3700406 100644
--- a/tests/test_async_client.py
+++ b/tests/test_async_client.py
@@ -38,9 +38,7 @@ def embed_query(
self,
text: str,
) -> list[float]:
- raise AssertionError(
- "AsyncDynavec must not call sync embed_query()."
- )
+ raise AssertionError("AsyncDynavec must not call sync embed_query().")
async def aembed_query(
self,
@@ -53,9 +51,7 @@ def embed_documents(
self,
texts: list[str],
) -> list[list[float]]:
- raise AssertionError(
- "AsyncDynavec must not call sync embed_documents()."
- )
+ raise AssertionError("AsyncDynavec must not call sync embed_documents().")
async def aembed_documents(
self,
@@ -63,19 +59,14 @@ async def aembed_documents(
) -> list[list[float]]:
self.async_calls.append(texts)
- return [
- [1.0, 2.0, 3.0, 4.0]
- for _ in texts
- ]
+ return [[1.0, 2.0, 3.0, 4.0] for _ in texts]
class FakeVectorStore:
def __init__(self) -> None:
self.entered = False
self.exited = False
- self.put_calls: list[
- tuple[list[tuple[str, list[float], dict[str, Any]]], int]
- ] = []
+ self.put_calls: list[tuple[list[tuple[str, list[float], dict[str, Any]]], int]] = []
self.query_results: list[dict[str, Any]] = []
self.query_calls: list[dict[str, Any]] = []
self.query_page_results: list[list[dict[str, Any]]] = []
@@ -115,14 +106,10 @@ async def __aexit__(
async def put_vectors(
self,
- vectors: list[
- tuple[str, list[float], dict[str, Any]]
- ],
+ vectors: list[tuple[str, list[float], dict[str, Any]]],
max_workers: int = 8,
) -> None:
- self.put_calls.append(
- (vectors, max_workers)
- )
+ self.put_calls.append((vectors, max_workers))
async def query_pages(
self,
@@ -179,11 +166,7 @@ async def get_many(
)
)
- return {
- doc_id: self.documents[doc_id]
- for doc_id in ids
- if doc_id in self.documents
- }
+ return {doc_id: self.documents[doc_id] for doc_id in ids if doc_id in self.documents}
async def __aenter__(
self,
@@ -210,9 +193,7 @@ async def put_many(
]
],
) -> None:
- self.put_calls.append(
- (namespace, items)
- )
+ self.put_calls.append((namespace, items))
def _install_fake_stores(
@@ -299,9 +280,7 @@ async def test_aupsert_requires_open_client() -> None:
async def test_aupsert_uses_async_embedding_and_writes_both_stores() -> None:
embedder = AsyncOnlyEmbedder()
- client, vectors, documents = _client(
- embedder=embedder
- )
+ client, vectors, documents = _client(embedder=embedder)
async with client:
result = await client.aupsert(
@@ -320,9 +299,7 @@ async def test_aupsert_uses_async_embedding_and_writes_both_stores() -> None:
assert result.count == 1
assert result.ids == ["a"]
- assert embedder.async_calls == [
- ["hello"]
- ]
+ assert embedder.async_calls == [["hello"]]
assert len(vectors.put_calls) == 1
assert len(documents.put_calls) == 1
@@ -337,9 +314,7 @@ async def test_aupsert_uses_async_embedding_and_writes_both_stores() -> None:
4.0,
]
- namespace, document_payload = (
- documents.put_calls[0]
- )
+ namespace, document_payload = documents.put_calls[0]
assert namespace == "tenant"
assert document_payload[0][0] == "a"
@@ -422,9 +397,7 @@ async def test_aupsert_runs_s3_and_dynamodb_writes_concurrently() -> None:
s3_started = asyncio.Event()
ddb_started = asyncio.Event()
- class CoordinatedVectors(
- FakeVectorStore
- ):
+ class CoordinatedVectors(FakeVectorStore):
async def put_vectors(
self,
vectors: list[
@@ -443,9 +416,7 @@ async def put_vectors(
timeout=1,
)
- class CoordinatedDocuments(
- FakeDocumentStore
- ):
+ class CoordinatedDocuments(FakeDocumentStore):
async def put_many(
self,
namespace: str,
@@ -503,15 +474,11 @@ async def put_many(
async def test_partial_enter_failure_closes_first_store() -> None:
vectors = FakeVectorStore()
- class FailingDocumentStore(
- FakeDocumentStore
- ):
+ class FailingDocumentStore(FakeDocumentStore):
async def __aenter__(
self,
) -> FailingDocumentStore:
- raise RuntimeError(
- "DynamoDB open failed"
- )
+ raise RuntimeError("DynamoDB open failed")
client = AsyncDynavec(
_config(),
diff --git a/tests/test_async_dynamodb.py b/tests/test_async_dynamodb.py
index 46b5614..3cb2725 100644
--- a/tests/test_async_dynamodb.py
+++ b/tests/test_async_dynamodb.py
@@ -115,9 +115,7 @@ def resource(
**kwargs: Any,
) -> FakeResourceContext:
self.calls.append((service_name, kwargs))
- self.context = FakeResourceContext(
- self.resource_instance
- )
+ self.context = FakeResourceContext(self.resource_instance)
return self.context
@@ -150,18 +148,14 @@ async def test_put_many_builds_and_writes_items():
],
)
- assert table.batch_writer_calls == [
- {"overwrite_by_pkeys": ["pk"]}
- ]
+ assert table.batch_writer_calls == [{"overwrite_by_pkeys": ["pk"]}]
assert len(table.writer.items) == 2
assert table.writer.items[0]["pk"] == "tenant#a"
assert table.writer.items[0]["id"] == "a"
assert table.writer.items[0]["text"] == "First"
- assert table.writer.items[0]["metadata"]["score"] == Decimal(
- "0.5"
- )
+ assert table.writer.items[0]["metadata"]["score"] == Decimal("0.5")
async def test_put_many_writes_custom_ttl_attribute():
@@ -342,12 +336,7 @@ async def test_get_many_batches_at_100_keys():
async with AsyncDynamoDBStore(_config(), session) as store:
await store.get_many("tenant", ids)
- sizes = [
- len(
- call["RequestItems"]["docs"]["Keys"]
- )
- for call in resource.batch_get_calls
- ]
+ sizes = [len(call["RequestItems"]["docs"]["Keys"]) for call in resource.batch_get_calls]
assert sizes == [100, 100, 50]
@@ -355,9 +344,7 @@ async def test_get_many_batches_at_100_keys():
async def test_operations_require_open_store():
store = AsyncDynamoDBStore(
_config(),
- FakeSession(
- FakeDynamoResource(FakeTable())
- ),
+ FakeSession(FakeDynamoResource(FakeTable())),
)
with pytest.raises(RuntimeError, match="not open"):
diff --git a/tests/test_async_s3vectors.py b/tests/test_async_s3vectors.py
index 9a46cba..2316fd2 100644
--- a/tests/test_async_s3vectors.py
+++ b/tests/test_async_s3vectors.py
@@ -112,10 +112,7 @@ async def test_put_vectors_batches_at_service_limit():
client = FakeS3Client()
session = FakeSession(client)
- vectors = [
- (f"key-{i}", [0.1, 0.2, 0.3, 0.4], {"tag": "test"})
- for i in range(1200)
- ]
+ vectors = [(f"key-{i}", [0.1, 0.2, 0.3, 0.4], {"tag": "test"}) for i in range(1200)]
async with AsyncS3VectorsStore(_config(), session) as store:
await store.put_vectors(vectors)
@@ -146,10 +143,7 @@ async def fake_put_batch(payload):
monkeypatch.setattr(store, "_put_batch", fake_put_batch)
- vectors = [
- (f"key-{i}", [0.1, 0.2, 0.3, 0.4], {})
- for i in range(1200)
- ]
+ vectors = [(f"key-{i}", [0.1, 0.2, 0.3, 0.4], {}) for i in range(1200)]
await store.put_vectors(vectors)
@@ -167,35 +161,23 @@ async def fail(payload):
monkeypatch.setattr(store, "_put_batch", fail)
with pytest.raises(RuntimeError, match="S3 API failure"):
- await store.put_vectors(
- [("key", [0.1, 0.2, 0.3, 0.4], {})]
- )
+ await store.put_vectors([("key", [0.1, 0.2, 0.3, 0.4], {})])
async def test_put_vectors_requires_open_store():
store = AsyncS3VectorsStore(_config(), FakeSession(FakeS3Client()))
with pytest.raises(RuntimeError, match="not open"):
- await store.put_vectors(
- [("key", [0.1, 0.2, 0.3, 0.4], {})]
- )
+ await store.put_vectors([("key", [0.1, 0.2, 0.3, 0.4], {})])
async def test_query_returns_paginated_results():
pages = [
{
- "vectors": [
- {"key": f"k{i}", "distance": i * 0.01}
- for i in range(100)
- ],
+ "vectors": [{"key": f"k{i}", "distance": i * 0.01} for i in range(100)],
"NextToken": "token-1",
},
- {
- "vectors": [
- {"key": f"k{i}", "distance": i * 0.01}
- for i in range(100, 150)
- ]
- },
+ {"vectors": [{"key": f"k{i}", "distance": i * 0.01} for i in range(100, 150)]},
]
client = FakeS3Client(pages)
@@ -215,18 +197,10 @@ async def test_query_returns_paginated_results():
async def test_query_truncates_at_top_k():
pages = [
{
- "vectors": [
- {"key": f"k{i}"}
- for i in range(100)
- ],
+ "vectors": [{"key": f"k{i}"} for i in range(100)],
"NextToken": "token-1",
},
- {
- "vectors": [
- {"key": f"k{i}"}
- for i in range(100, 200)
- ]
- },
+ {"vectors": [{"key": f"k{i}"} for i in range(100, 200)]},
]
client = FakeS3Client(pages)
@@ -243,14 +217,7 @@ async def test_query_truncates_at_top_k():
async def test_query_pages_respects_page_size():
- pages = [
- {
- "vectors": [
- {"key": f"k{i}"}
- for i in range(25)
- ]
- }
- ]
+ pages = [{"vectors": [{"key": f"k{i}"} for i in range(25)]}]
client = FakeS3Client(pages)
session = FakeSession(client)
diff --git a/tests/test_bedrock_multimodal.py b/tests/test_bedrock_multimodal.py
index 707e952..7ffdec8 100644
--- a/tests/test_bedrock_multimodal.py
+++ b/tests/test_bedrock_multimodal.py
@@ -237,4 +237,3 @@ def test_empty_string_text_is_sent(mock_boto_session):
payload = json.loads(client.invoke_model.call_args[1]["body"])
assert payload["inputText"] == ""
assert "inputImage" in payload
-
diff --git a/tests/test_bm25_retriever.py b/tests/test_bm25_retriever.py
index 666d16e..8827185 100644
--- a/tests/test_bm25_retriever.py
+++ b/tests/test_bm25_retriever.py
@@ -108,6 +108,7 @@ def db(monkeypatch):
# Tokenizer tests
# ---------------------------------------------------------------------------
+
def test_default_tokenize_basic():
tokens = default_tokenize("The quick brown fox jumps over the lazy dog.")
# Stopwords ("the", "over") filtered out
@@ -150,6 +151,7 @@ def test_default_tokenize_empty_and_special():
# BM25Index tests
# ---------------------------------------------------------------------------
+
def test_bm25_index_validation():
with pytest.raises(ValueError, match="k1 must be non-negative"):
BM25Index(k1=-1.0)
@@ -245,12 +247,15 @@ def test_bm25_index_empty_query():
# BM25Retriever tests
# ---------------------------------------------------------------------------
+
def test_bm25_retriever_basic(db):
retriever = BM25Retriever(db)
- retriever.index_documents([
- Document(id="doc1", text="Dell XPS-13-9310 laptop"),
- Document(id="doc2", text="Lenovo ThinkPad laptop"),
- ])
+ retriever.index_documents(
+ [
+ Document(id="doc1", text="Dell XPS-13-9310 laptop"),
+ Document(id="doc2", text="Lenovo ThinkPad laptop"),
+ ]
+ )
results = retriever.search("XPS-13-9310")
assert len(results) >= 1
@@ -266,10 +271,12 @@ def test_bm25_retriever_basic(db):
@pytest.mark.asyncio
async def test_bm25_retriever_async(db):
retriever = BM25Retriever(db)
- retriever.index_documents([
- Document(id="d1", text="ConnectionResetError encountered"),
- Document(id="d2", text="HTTP 500 internal server error"),
- ])
+ retriever.index_documents(
+ [
+ Document(id="d1", text="ConnectionResetError encountered"),
+ Document(id="d2", text="HTTP 500 internal server error"),
+ ]
+ )
results = await retriever.asearch("ConnectionResetError")
assert len(results) == 1
@@ -290,6 +297,7 @@ def test_bm25_retriever_populate_from_store(db):
# BM25HybridRetriever tests
# ---------------------------------------------------------------------------
+
def test_hybrid_retriever_initialization_and_weights(db):
retriever = BM25HybridRetriever(db, dense_weight=1.2, sparse_weight=0.6)
assert retriever.dense_weight == 1.2
@@ -347,6 +355,7 @@ async def test_hybrid_retriever_asearch(db):
# Client & NamespaceView Ergonomics tests
# ---------------------------------------------------------------------------
+
def test_client_retriever_ergonomics(db):
# as_bm25_retriever
bm25 = db.as_bm25_retriever(populate_from_store=True)
diff --git a/tests/test_cache.py b/tests/test_cache.py
index d44587b..26bb754 100644
--- a/tests/test_cache.py
+++ b/tests/test_cache.py
@@ -44,7 +44,7 @@ def test_dissimilar_miss():
def test_namespace_and_topk_scoping():
c = SemanticCache(threshold=0.5)
c.put("ns1", [1.0, 0.0], 5, None, _res("a"))
- assert c.get("ns2", [1.0, 0.0], 5, None) is None # different namespace
+ assert c.get("ns2", [1.0, 0.0], 5, None) is None # different namespace
assert c.get("ns1", [1.0, 0.0], 10, None) is None # different top_k
@@ -216,9 +216,10 @@ def Table(self, table_name):
ttl_jitter_seconds=30,
)
- with patch("dynavec.cache.time.time", return_value=1_000), patch(
- "dynavec.cache.random.randint", side_effect=[0, 30]
- ) as randint:
+ with (
+ patch("dynavec.cache.time.time", return_value=1_000),
+ patch("dynavec.cache.random.randint", side_effect=[0, 30]) as randint,
+ ):
cache.put("ns", [1.0, 0.0], 5, None, _res("a"))
cache.put("ns", [0.0, 1.0], 5, None, _res("b"))
diff --git a/tests/test_chat_models.py b/tests/test_chat_models.py
index 29545a0..a00d8bc 100644
--- a/tests/test_chat_models.py
+++ b/tests/test_chat_models.py
@@ -89,6 +89,7 @@ def __init__(self) -> None:
async def create(self, **kwargs: Any) -> Any:
self.last_kwargs = kwargs
if kwargs.get("stream"):
+
async def _async_gen() -> Any:
yield SimpleNamespace(
choices=[
@@ -107,6 +108,7 @@ async def _async_gen() -> Any:
)
]
)
+
return _async_gen()
if kwargs.get("tools"):
@@ -198,9 +200,7 @@ def __enter__(self) -> list[Any]:
),
SimpleNamespace(
type="content_block_delta",
- delta=SimpleNamespace(
- type="input_json_delta", partial_json='{"loc":"NY"}'
- ),
+ delta=SimpleNamespace(type="input_json_delta", partial_json='{"loc":"NY"}'),
),
]
@@ -254,6 +254,7 @@ async def _gen() -> Any:
type="input_json_delta", partial_json='{"loc":"Async NY"}'
),
)
+
return _gen()
async def __aexit__(self, exc_type: Any, exc_val: Any, exc_tb: Any) -> None:
diff --git a/tests/test_client_inmemory.py b/tests/test_client_inmemory.py
index 5d3ec0f..75c22b6 100644
--- a/tests/test_client_inmemory.py
+++ b/tests/test_client_inmemory.py
@@ -90,7 +90,11 @@ def query_pages(
yield hits[i : i + chunk_size]
def get_vectors(self, keys, return_metadata=False):
- return {k: {"vector": self._store[k][0], "metadata": self._store[k][1]} for k in keys if k in self._store}
+ return {
+ k: {"vector": self._store[k][0], "metadata": self._store[k][1]}
+ for k in keys
+ if k in self._store
+ }
def delete_vectors(self, keys):
for k in keys:
@@ -128,9 +132,12 @@ def get_versioned(self, namespace, doc_id):
def get_many(self, namespace, ids):
return {
- i: {"text": self._store[(namespace, i)]["text"],
- "metadata": self._store[(namespace, i)]["metadata"]}
- for i in ids if (namespace, i) in self._store
+ i: {
+ "text": self._store[(namespace, i)]["text"],
+ "metadata": self._store[(namespace, i)]["metadata"],
+ }
+ for i in ids
+ if (namespace, i) in self._store
}
def delete_many(self, namespace, ids):
@@ -229,6 +236,7 @@ def db(monkeypatch):
)
return Dynavec(cfg, embedder=HashEmbedder(8))
+
@pytest.fixture
def cross_encoder_db(monkeypatch):
monkeypatch.setattr(client_mod, "S3VectorsStore", FakeS3)
@@ -244,6 +252,7 @@ def cross_encoder_db(monkeypatch):
)
return Dynavec(cfg, embedder=HashEmbedder(8))
+
def test_upsert_and_search_roundtrip(db):
res = db.upsert(
[
@@ -277,6 +286,7 @@ def test_graph_shortest_path_respects_hop_cap(db):
assert db.graph_shortest_path("a", "d", hops=2) == []
+
def test_graph_shortest_path_returns_minimum_hops(db):
db.graph_add_edge("a", "related_to", "c")
db.graph_add_edge("c", "related_to", "e")
@@ -291,6 +301,7 @@ def test_graph_shortest_path_returns_minimum_hops(db):
"d",
]
+
def test_search_explain_handles_empty_results(db):
result = db.search("missing", explain=True)
@@ -405,6 +416,7 @@ def test_dimension_mismatch_raises(db):
with pytest.raises(DimensionMismatchError):
db.upsert([Document(id="x", vector=[0.1, 0.2])]) # wrong dim (2 != 8)
+
class WrongOutputEmbedder(HashEmbedder):
def embed_documents(self, texts):
return [[0.1, 0.2] for _ in texts]
@@ -516,7 +528,7 @@ def test_ns_tag_present_in_s3(db):
db.upsert([Document(id="1", text="hello")], namespace="ns9")
# reach into the fake to confirm the namespace tag was written
store = db._vectors._store
- (_, meta), = (v for k, v in store.items())
+ ((_, meta),) = (v for k, v in store.items())
assert meta[NS_METADATA_KEY] == "ns9"
@@ -526,7 +538,7 @@ def test_update_metadata_merge_preserves_vector(db):
db.update("1", metadata={"rating": 5})
after_meta = db.get(["1"])[0].metadata
assert after_meta["cat"] == "food" # preserved
- assert after_meta["rating"] == 5 # added
+ assert after_meta["rating"] == 5 # added
# vector unchanged because neither text nor vector was updated
assert db._vectors._store["default#1"][0] == before
@@ -582,7 +594,10 @@ def read_then_race(namespace, doc_id):
snapshot = real_read(namespace, doc_id)
# another writer commits after our read but before our write
db._docs.put_versioned(
- namespace, doc_id, snapshot["text"], {**snapshot["metadata"], "views": 2},
+ namespace,
+ doc_id,
+ snapshot["text"],
+ {**snapshot["metadata"], "views": 2},
expected_version=snapshot["version"],
)
return snapshot
@@ -616,9 +631,7 @@ def test_update_upsert_if_missing_starts_at_version_one(db):
def test_search_stream_yields_incrementally(db):
- db.upsert(
- [Document(id=str(i), text=f"apple item {i}") for i in range(5)]
- )
+ db.upsert([Document(id=str(i), text=f"apple item {i}") for i in range(5)])
gen = db.search_stream("apple", top_k=4)
first = next(gen)
assert first.text is not None
@@ -688,7 +701,10 @@ def test_search_many_explain_preserves_order_and_namespace(db, explain):
ns = db.namespace("kb")
ns.upsert([Document(id="1", text="apple"), Document(id="2", text="rocket")])
batches = db.search_many(
- ["rocket", "apple"], namespace="kb", top_k=1, explain=explain,
+ ["rocket", "apple"],
+ namespace="kb",
+ top_k=1,
+ explain=explain,
normalize_scores=True,
)
assert len(batches) == 2
@@ -724,6 +740,7 @@ def test_graph_search_scopes_to_related_docs(db):
hits = db.graph_search("apple", seed_entities=["fruit"], top_k=5)
assert {h.id for h in hits} == {"d1", "d2"} # d3 excluded by the graph
+
def test_hybrid_graph_search_fuses_ann_and_graph_results(db):
db.upsert(
[
@@ -888,11 +905,12 @@ def test_search_telemetry_marks_cache_hit(db):
db._telemetry = rec
db._cache = SemanticCache(threshold=0.99)
db.upsert([Document(id="1", text="apple pie")])
- db.search("apple pie", top_k=3) # miss -> populates cache
- db.search("apple pie", top_k=3) # hit
+ db.search("apple pie", top_k=3) # miss -> populates cache
+ db.search("apple pie", top_k=3) # hit
hits = [e.cache_hit for e in rec.events()]
assert True in hits and False in hits
+
def test_cross_encoder_rerank_on_toy_data(monkeypatch, cross_encoder_db):
class FakeCrossEncoder:
instance = None
@@ -902,10 +920,7 @@ def __init__(self, model_name):
FakeCrossEncoder.instance = self
def predict(self, pairs):
- return [
- 0.95 if "target document" in document else 0.10
- for _, document in pairs
- ]
+ return [0.95 if "target document" in document else 0.10 for _, document in pairs]
monkeypatch.setitem(
sys.modules,
@@ -913,18 +928,20 @@ def predict(self, pairs):
SimpleNamespace(CrossEncoder=FakeCrossEncoder),
)
- cross_encoder_db.upsert([
- Document(
- id="d1",
- text="ordinary document",
- vector=[0.1] * 8,
- ),
- Document(
- id="d2",
- text="target document",
- vector=[0.1] * 8,
- ),
- ])
+ cross_encoder_db.upsert(
+ [
+ Document(
+ id="d1",
+ text="ordinary document",
+ vector=[0.1] * 8,
+ ),
+ Document(
+ id="d2",
+ text="target document",
+ vector=[0.1] * 8,
+ ),
+ ]
+ )
results = cross_encoder_db.search(
"find the target",
@@ -937,18 +954,13 @@ def predict(self, pairs):
assert FakeCrossEncoder.instance.model_name == "toy-cross-encoder"
-def test_search_explain_records_cross_encoder_rerank_stage(
- monkeypatch, cross_encoder_db
-):
+def test_search_explain_records_cross_encoder_rerank_stage(monkeypatch, cross_encoder_db):
class FakeCrossEncoder:
def __init__(self, model_name):
self.model_name = model_name
def predict(self, pairs):
- return [
- 0.95 if "target document" in document else 0.10
- for _, document in pairs
- ]
+ return [0.95 if "target document" in document else 0.10 for _, document in pairs]
monkeypatch.setitem(
sys.modules,
@@ -956,18 +968,20 @@ def predict(self, pairs):
SimpleNamespace(CrossEncoder=FakeCrossEncoder),
)
- cross_encoder_db.upsert([
- Document(
- id="d1",
- text="ordinary document",
- vector=[0.1] * 8,
- ),
- Document(
- id="d2",
- text="target document",
- vector=[0.1] * 8,
- ),
- ])
+ cross_encoder_db.upsert(
+ [
+ Document(
+ id="d1",
+ text="ordinary document",
+ vector=[0.1] * 8,
+ ),
+ Document(
+ id="d2",
+ text="target document",
+ vector=[0.1] * 8,
+ ),
+ ]
+ )
result = cross_encoder_db.search(
"find the target",
@@ -987,13 +1001,15 @@ def predict(self, pairs):
def test_cross_encoder_rerank_requires_text_query(cross_encoder_db):
- cross_encoder_db.upsert([
- Document(
- id="d1",
- text="some document",
- vector=[0.1] * 8,
- ),
- ])
+ cross_encoder_db.upsert(
+ [
+ Document(
+ id="d1",
+ text="some document",
+ vector=[0.1] * 8,
+ ),
+ ]
+ )
with pytest.raises(ConfigurationError, match="requires a text query"):
cross_encoder_db.search(
@@ -1002,6 +1018,7 @@ def test_cross_encoder_rerank_requires_text_query(cross_encoder_db):
rerank="cross-encoder",
)
+
def test_cross_encoder_rerank_requires_document_text(monkeypatch, cross_encoder_db):
class FakeCrossEncoder:
def __init__(self, model_name):
@@ -1013,13 +1030,15 @@ def __init__(self, model_name):
SimpleNamespace(CrossEncoder=FakeCrossEncoder),
)
- cross_encoder_db.upsert([
- Document(
- id="d1",
- text=None,
- vector=[0.1] * 8,
- ),
- ])
+ cross_encoder_db.upsert(
+ [
+ Document(
+ id="d1",
+ text=None,
+ vector=[0.1] * 8,
+ ),
+ ]
+ )
with pytest.raises(ConfigurationError, match="requires document text"):
cross_encoder_db.search(
@@ -1033,15 +1052,15 @@ def test_writes_invalidate_query_cache(db):
db._cache = SemanticCache(threshold=0.99)
db.upsert([Document(id="1", text="apple pie")], namespace="ns")
db.upsert([Document(id="o1", text="apple pie")], namespace="other")
- db.search("apple pie", top_k=3, namespace="ns") # miss -> cached
- db.search("apple pie", top_k=3, namespace="other") # miss -> cached
+ db.search("apple pie", top_k=3, namespace="ns") # miss -> cached
+ db.search("apple pie", top_k=3, namespace="other") # miss -> cached
assert db._cache.misses == 2
# a write to "ns" evicts only that namespace's entries
db.upsert([Document(id="2", text="apple pie tart")], namespace="ns")
- db.search("apple pie", top_k=3, namespace="other") # still cached -> hit
+ db.search("apple pie", top_k=3, namespace="other") # still cached -> hit
assert db._cache.hits == 1
- res = db.search("apple pie", top_k=3, namespace="ns") # evicted -> fresh
+ res = db.search("apple pie", top_k=3, namespace="ns") # evicted -> fresh
assert db._cache.misses == 3
assert "2" in {r.id for r in res}
@@ -1058,14 +1077,17 @@ def test_writes_keep_cache_when_invalidation_disabled(monkeypatch):
monkeypatch.setattr(client_mod, "S3VectorsStore", FakeS3)
monkeypatch.setattr(client_mod, "DynamoDBStore", FakeDDB)
cfg = DynavecConfig(
- vector_bucket="b", index="i", table="t", dimension=8,
+ vector_bucket="b",
+ index="i",
+ table="t",
+ dimension=8,
cache_invalidate_on_write=False,
)
db = Dynavec(cfg, embedder=HashEmbedder(8))
db._cache = SemanticCache(threshold=0.99)
db.upsert([Document(id="1", text="apple pie")], namespace="ns")
- db.search("apple pie", top_k=3, namespace="ns") # cached
+ db.search("apple pie", top_k=3, namespace="ns") # cached
db.upsert([Document(id="2", text="apple pie tart")], namespace="ns")
- db.search("apple pie", top_k=3, namespace="ns") # stale hit
+ db.search("apple pie", top_k=3, namespace="ns") # stale hit
assert db._cache.hits == 1
diff --git a/tests/test_crewai_tool.py b/tests/test_crewai_tool.py
index 852e575..4a9684c 100644
--- a/tests/test_crewai_tool.py
+++ b/tests/test_crewai_tool.py
@@ -80,4 +80,4 @@ def test_as_crewai_tool_missing_dependency_raises():
from dynavec.integrations.tools import as_crewai_tool
with pytest.raises(MissingDependencyError):
- as_crewai_tool(_FakeClient())
\ No newline at end of file
+ as_crewai_tool(_FakeClient())
diff --git a/tests/test_describe.py b/tests/test_describe.py
index 4d2ba4f..1e72411 100644
--- a/tests/test_describe.py
+++ b/tests/test_describe.py
@@ -128,4 +128,4 @@ def test_get_index_request_matches_s3vectors_service_model():
result = store.get_index()
stubber.assert_no_pending_responses()
- assert result["index"]["indexName"] == "test-index"
\ No newline at end of file
+ assert result["index"]["indexName"] == "test-index"
diff --git a/tests/test_dynamodb.py b/tests/test_dynamodb.py
index 917e314..a0ccfc9 100644
--- a/tests/test_dynamodb.py
+++ b/tests/test_dynamodb.py
@@ -138,7 +138,9 @@ def test_put_versioned_conflict_leaves_item_untouched(moto_store):
moto_store.put_versioned("tenant", "a", "loser", {"by": "stale"}, expected_version=1)
assert (info.value.doc_id, info.value.namespace, info.value.expected_version) == (
- "a", "tenant", 1,
+ "a",
+ "tenant",
+ 1,
)
assert moto_store.get_versioned("tenant", "a")["metadata"] == {"by": "second"}
diff --git a/tests/test_embedding_cache.py b/tests/test_embedding_cache.py
index f17d8f3..b673cc7 100644
--- a/tests/test_embedding_cache.py
+++ b/tests/test_embedding_cache.py
@@ -16,13 +16,14 @@
# Fake embedders (same style as test_async_embeddings.py)
# ---------------------------------------------------------------------------
+
class _CountingEmbedder(Embedder):
"""Deterministic embedder that tracks every text it actually embeds."""
dimension: ClassVar[int] = 4
def __init__(self) -> None:
- self.calls: list[list[str]] = [] # one entry per embed_documents call
+ self.calls: list[list[str]] = [] # one entry per embed_documents call
def embed_documents(self, texts: list[str]) -> list[Vector]:
self.calls.append(list(texts))
@@ -59,6 +60,7 @@ async def aembed_documents(self, texts: list[str]) -> list[Vector]:
# Custom cache backend (proves pluggability)
# ---------------------------------------------------------------------------
+
class _MinimalCache(EmbeddingCache):
"""Bare-minimum custom cache to verify the ABC contract works."""
@@ -77,19 +79,23 @@ def set(self, key: str, vector: Vector) -> None:
# 1. _make_key
# ---------------------------------------------------------------------------
+
def test_make_key_same_inputs_same_key():
assert _make_key("hello", "m1") == _make_key("hello", "m1")
+
def test_make_key_different_text_different_key():
assert _make_key("hello", "m1") != _make_key("world", "m1")
+
def test_make_key_different_model_different_key():
assert _make_key("hello", "m1") != _make_key("hello", "m2")
+
def test_make_key_format():
key = _make_key("abc", "my-model")
sha, model = key.split(":")
- assert len(sha) == 64 # sha256 hex is always 64 chars
+ assert len(sha) == 64 # sha256 hex is always 64 chars
assert model == "my-model"
@@ -97,40 +103,47 @@ def test_make_key_format():
# 2. InMemoryCache
# ---------------------------------------------------------------------------
+
def test_inmemory_miss_returns_none():
assert InMemoryCache().get("nonexistent") is None
+
def test_inmemory_set_then_get():
cache = InMemoryCache()
cache.set("k", [1.0, 2.0])
assert cache.get("k") == [1.0, 2.0]
+
def test_inmemory_get_for_set_for():
cache = InMemoryCache()
cache.set_for("hello", "model-a", [0.5, 0.5])
assert cache.get_for("hello", "model-a") == [0.5, 0.5]
- assert cache.get_for("hello", "model-b") is None # different model → miss
+ assert cache.get_for("hello", "model-b") is None # different model → miss
+
def test_inmemory_lru_eviction():
cache = InMemoryCache(max_size=2)
cache.set("a", [1.0])
cache.set("b", [2.0])
- cache.get("a") # touch "a" → now "b" is LRU
- cache.set("c", [3.0]) # should evict "b", not "a"
+ cache.get("a") # touch "a" → now "b" is LRU
+ cache.set("c", [3.0]) # should evict "b", not "a"
assert cache.get("b") is None
assert cache.get("a") == [1.0]
assert cache.get("c") == [3.0]
+
def test_inmemory_max_size_none_is_unlimited():
cache = InMemoryCache(max_size=None)
for i in range(10_000):
cache.set(str(i), [float(i)])
assert len(cache) == 10_000
+
def test_inmemory_negative_max_size_raises():
with pytest.raises(ValueError):
InMemoryCache(max_size=-1)
+
def test_inmemory_len_and_contains():
cache = InMemoryCache()
assert len(cache) == 0
@@ -139,22 +152,25 @@ def test_inmemory_len_and_contains():
assert "x" in cache
assert "y" not in cache
+
def test_inmemory_clear():
cache = InMemoryCache()
cache.set("x", [0.0])
cache.clear()
assert len(cache) == 0
+
def test_inmemory_stats_hit_rate():
cache = InMemoryCache()
cache.set_for("hi", "m", [1.0])
- cache.get_for("hi", "m") # hit
- cache.get_for("bye", "m") # miss
+ cache.get_for("hi", "m") # hit
+ cache.get_for("bye", "m") # miss
s = cache.stats()
assert s["hits"] == 1
assert s["misses"] == 1
assert s["hit_rate"] == 0.5
+
def test_inmemory_reset_stats():
cache = InMemoryCache()
cache.set_for("hi", "m", [1.0])
@@ -167,28 +183,32 @@ def test_inmemory_reset_stats():
# 3. CachedEmbedder — embed_documents
# ---------------------------------------------------------------------------
+
def test_first_call_hits_inner():
inner = _CountingEmbedder()
embedder = CachedEmbedder(inner, cache=InMemoryCache())
embedder.embed_documents(["a", "b"])
assert inner.calls == [["a", "b"]]
+
def test_second_call_is_full_cache_hit():
inner = _CountingEmbedder()
embedder = CachedEmbedder(inner, cache=InMemoryCache())
v1 = embedder.embed_documents(["a", "b"])
v2 = embedder.embed_documents(["a", "b"])
- assert len(inner.calls) == 1 # inner called only once
+ assert len(inner.calls) == 1 # inner called only once
assert v1 == v2
+
def test_partial_hit_calls_inner_only_for_misses():
inner = _CountingEmbedder()
embedder = CachedEmbedder(inner, cache=InMemoryCache())
- embedder.embed_documents(["a"]) # warm "a"
- embedder.embed_documents(["a", "b"]) # "a" hit, "b" miss
+ embedder.embed_documents(["a"]) # warm "a"
+ embedder.embed_documents(["a", "b"]) # "a" hit, "b" miss
# second call should only have sent "b" to inner
assert inner.calls[-1] == ["b"]
+
def test_order_preserved_with_mixed_hits_misses():
inner = _CountingEmbedder()
embedder = CachedEmbedder(inner, cache=InMemoryCache())
@@ -199,12 +219,14 @@ def test_order_preserved_with_mixed_hits_misses():
assert v_zyx[1] == v_xyz[1]
assert v_zyx[2] == v_xyz[0]
+
def test_empty_input_returns_empty():
inner = _CountingEmbedder()
embedder = CachedEmbedder(inner, cache=InMemoryCache())
assert embedder.embed_documents([]) == []
assert inner.calls == []
+
def test_dimension_delegated_to_inner():
inner = _CountingEmbedder()
assert CachedEmbedder(inner).dimension == inner.dimension
@@ -214,19 +236,21 @@ def test_dimension_delegated_to_inner():
# 4. CachedEmbedder — embed_query
# ---------------------------------------------------------------------------
+
def test_embed_query_miss_then_hit():
inner = _CountingEmbedder()
embedder = CachedEmbedder(inner, cache=InMemoryCache())
v1 = embedder.embed_query("hello")
v2 = embedder.embed_query("hello")
assert v1 == v2
- assert inner.total_texts_embedded == 1 # embedded only once
+ assert inner.total_texts_embedded == 1 # embedded only once
# ---------------------------------------------------------------------------
# 5. Async variants
# ---------------------------------------------------------------------------
+
@pytest.mark.asyncio
async def test_aembed_documents_caches():
inner = _CountingEmbedder()
@@ -236,6 +260,7 @@ async def test_aembed_documents_caches():
assert len(inner.calls) == 1
assert v1 == v2
+
@pytest.mark.asyncio
async def test_aembed_documents_partial_hit():
inner = _CountingEmbedder()
@@ -244,6 +269,7 @@ async def test_aembed_documents_partial_hit():
await embedder.aembed_documents(["p", "q"])
assert inner.calls[-1] == ["q"]
+
@pytest.mark.asyncio
async def test_aembed_query_caches():
inner = _CountingEmbedder()
@@ -253,6 +279,7 @@ async def test_aembed_query_caches():
assert v1 == v2
assert inner.total_texts_embedded == 1
+
@pytest.mark.asyncio
async def test_aembed_documents_native_async_inner():
"""Cache should work when inner has a native async path."""
@@ -260,7 +287,7 @@ async def test_aembed_documents_native_async_inner():
embedder = CachedEmbedder(inner, cache=InMemoryCache())
v1 = await embedder.aembed_documents(["foo", "bar"])
v2 = await embedder.aembed_documents(["foo", "bar"])
- assert len(inner.async_calls) == 1 # native async called only once
+ assert len(inner.async_calls) == 1 # native async called only once
assert v1 == v2
@@ -268,6 +295,7 @@ async def test_aembed_documents_native_async_inner():
# 6. model_key isolation
# ---------------------------------------------------------------------------
+
def test_different_model_keys_dont_share_entries():
shared_cache = InMemoryCache()
inner_a = _CountingEmbedder()
@@ -275,15 +303,16 @@ def test_different_model_keys_dont_share_entries():
ea = CachedEmbedder(inner_a, cache=shared_cache, model_key="model-A")
eb = CachedEmbedder(inner_b, cache=shared_cache, model_key="model-B")
ea.embed_documents(["hello"])
- eb.embed_documents(["hello"]) # same text, different key → must be a miss
+ eb.embed_documents(["hello"]) # same text, different key → must be a miss
assert inner_a.total_texts_embedded == 1
- assert inner_b.total_texts_embedded == 1 # inner_b was also called
+ assert inner_b.total_texts_embedded == 1 # inner_b was also called
# ---------------------------------------------------------------------------
# 7. Pluggable custom backend
# ---------------------------------------------------------------------------
+
def test_custom_cache_backend_is_used():
custom = _MinimalCache()
inner = _CountingEmbedder()
@@ -293,6 +322,7 @@ def test_custom_cache_backend_is_used():
assert inner.total_texts_embedded == 1
assert embedder.cache is custom
+
def test_default_cache_is_inmemory():
embedder = CachedEmbedder(_CountingEmbedder())
assert isinstance(embedder.cache, InMemoryCache)
diff --git a/tests/test_eval_trend.py b/tests/test_eval_trend.py
index 1bea2d7..3b031c8 100644
--- a/tests/test_eval_trend.py
+++ b/tests/test_eval_trend.py
@@ -12,6 +12,7 @@
# Helpers
# ---------------------------------------------------------------------------
+
def _retrieval_summary(recall_10: float, ndcg_10: float, mrr: float = 0.8) -> RetrievalEvalSummary:
return RetrievalEvalSummary(
total_queries=10,
@@ -40,6 +41,7 @@ def _rag_summary(faithfulness: float, relevance: float = 0.85) -> EvalSummary:
# 1. record()
# ---------------------------------------------------------------------------
+
def test_record_retrieval_summary_returns_eval_run():
store = EvalRunStore()
summary = _retrieval_summary(0.85, 0.80)
@@ -78,10 +80,11 @@ def test_record_respects_max_runs():
# 2. filter()
# ---------------------------------------------------------------------------
+
def test_filter_by_single_tag():
store = EvalRunStore()
store.record(_retrieval_summary(0.80, 0.75), tags={"dataset": "squad", "model": "ada"})
- store.record(_retrieval_summary(0.70, 0.65), tags={"dataset": "nq", "model": "ada"})
+ store.record(_retrieval_summary(0.70, 0.65), tags={"dataset": "nq", "model": "ada"})
store.record(_retrieval_summary(0.90, 0.85), tags={"dataset": "squad", "model": "v3"})
squad_runs = store.filter(dataset="squad")
@@ -109,6 +112,7 @@ def test_filter_no_match_returns_empty():
# 3. trend()
# ---------------------------------------------------------------------------
+
def test_trend_recall_returns_sorted_time_series():
store = EvalRunStore()
# record three runs at explicit timestamps
@@ -139,7 +143,7 @@ def test_trend_faithfulness_from_rag_summaries():
def test_trend_with_tag_filter():
store = EvalRunStore()
store.record(_retrieval_summary(0.60, 0.55), tags={"model": "ada"}, ts=100.0)
- store.record(_retrieval_summary(0.80, 0.75), tags={"model": "v3"}, ts=200.0)
+ store.record(_retrieval_summary(0.80, 0.75), tags={"model": "v3"}, ts=200.0)
store.record(_retrieval_summary(0.65, 0.60), tags={"model": "ada"}, ts=300.0)
series = store.trend("recall", k=10, model="ada")
@@ -163,6 +167,7 @@ def test_trend_skips_runs_without_metric():
# 4. compare()
# ---------------------------------------------------------------------------
+
def test_compare_two_runs_returns_both():
store = EvalRunStore()
r1 = store.record(_retrieval_summary(0.75, 0.70), tags={"model": "ada"})
@@ -186,8 +191,10 @@ def test_compare_missing_id_raises():
# 5. to_dict round-trip
# ---------------------------------------------------------------------------
+
def test_eval_run_to_dict_is_serialisable():
import json
+
store = EvalRunStore()
run = store.record(_retrieval_summary(0.82, 0.78), tags={"dataset": "squad"})
d = run.to_dict()
diff --git a/tests/test_fusion.py b/tests/test_fusion.py
index c2ab0cb..a072039 100644
--- a/tests/test_fusion.py
+++ b/tests/test_fusion.py
@@ -13,6 +13,7 @@ def _make_result(doc_id: str, score: float) -> SearchResult:
# ── helpers ─────────────────────────────────────────────────────────────────
+
def _two_retriever_fixture():
"""Two queries, two retrievers — dense is better."""
labeled = [
@@ -41,6 +42,7 @@ def _three_retriever_fixture():
# ── score ───────────────────────────────────────────────────────────────────
+
def test_score_returns_float():
labeled, dense, sparse = _two_retriever_fixture()
fitter = RRFWeightFitter(labeled, [dense, sparse])
@@ -50,6 +52,7 @@ def test_score_returns_float():
# ── fit() returns FitResult ─────────────────────────────────────────────────
+
@pytest.mark.parametrize("method", ["grid", "random"])
def test_fit_returns_fit_result(method):
labeled, dense, sparse = _two_retriever_fixture()
@@ -65,6 +68,7 @@ def test_fit_returns_fit_result(method):
# ── grid search ─────────────────────────────────────────────────────────────
+
def test_fit_grid_improves_over_equal_weights():
labeled = [LabeledQuery(query="q1", relevant_ids={"doc_a"})]
dense = [[_make_result("doc_a", 0.9), _make_result("doc_b", 0.1)]]
@@ -91,6 +95,7 @@ def test_fit_grid_three_retrievers():
# ── random search ───────────────────────────────────────────────────────────
+
def test_fit_random_three_retrievers():
labeled, r1, r2, r3 = _three_retriever_fixture()
fitter = RRFWeightFitter(labeled, [r1, r2, r3])
@@ -102,6 +107,7 @@ def test_fit_random_three_retrievers():
# ── bayesian fitting ────────────────────────────────────────────────────────
+
def test_fit_bayesian_two_retrievers():
"""Bayesian fitting should return valid FitResult."""
labeled, dense, sparse = _two_retriever_fixture()
@@ -128,6 +134,7 @@ def test_fit_bayesian_three_retrievers():
# ── serialisation (save / load) ─────────────────────────────────────────────
+
def test_save_load_roundtrip(tmp_path):
"""FitResult should survive a JSON roundtrip."""
original = FitResult(
@@ -166,6 +173,7 @@ def test_to_dict():
# ── end-to-end: fit then save/load ──────────────────────────────────────────
+
def test_fit_and_save_load(tmp_path):
"""Full workflow: fit → save → load → use weights."""
labeled, dense, sparse = _two_retriever_fixture()
@@ -182,6 +190,7 @@ def test_fit_and_save_load(tmp_path):
# ── error handling ──────────────────────────────────────────────────────────
+
def test_empty_labeled_queries_raises():
with pytest.raises(ValueError, match="labeled_queries"):
RRFWeightFitter([], [[]])
diff --git a/tests/test_graph_export.py b/tests/test_graph_export.py
index 93a3c8a..dc04308 100644
--- a/tests/test_graph_export.py
+++ b/tests/test_graph_export.py
@@ -55,9 +55,7 @@ def graph():
def test_mermaid_export_renders_the_namespace_subgraph(graph):
assert graph.graph_export("mermaid", "corp") == (
- "graph LR\n"
- " acme -->|competes_with| globex\n"
- " globex -->|supplies| initech\n"
+ "graph LR\n acme -->|competes_with| globex\n globex -->|supplies| initech\n"
)
@@ -84,10 +82,7 @@ def test_cycle_terminates_and_emits_each_edge_once():
g.add_edge("ns", "a", "next", "b") # duplicate adjacency entry
assert g.graph_export("mermaid", "ns") == (
- "graph LR\n"
- " a -->|next| b\n"
- " b -->|next| c\n"
- " c -->|next| a\n"
+ "graph LR\n a -->|next| b\n b -->|next| c\n c -->|next| a\n"
)
@@ -98,9 +93,7 @@ def test_cycle_terminates_when_walking_from_a_root():
g.add_node("ns", "orphan") # unreachable from "a", so absent
assert g.graph_export("mermaid", "ns", roots=["a"]) == (
- "graph LR\n"
- " a -->|next| b\n"
- " b -->|next| a\n"
+ "graph LR\n a -->|next| b\n b -->|next| a\n"
)
@@ -108,11 +101,7 @@ def test_self_loop_terminates():
g = FakeGraph()
g.add_edge("ns", "a", "cites", "a")
- assert g.graph_export("dot", "ns") == (
- "digraph G {\n"
- ' "a" -> "a" [label="cites"];\n'
- "}\n"
- )
+ assert g.graph_export("dot", "ns") == ('digraph G {\n "a" -> "a" [label="cites"];\n}\n')
# -------------------------------------------------------------------- escaping
@@ -156,11 +145,7 @@ def test_mermaid_alias_never_shadows_a_real_id():
g = FakeGraph()
g.add_edge("ns", "n0", "points_at", "zz top") # "n0" is a legal bare id
- assert g.graph_export("mermaid", "ns") == (
- "graph LR\n"
- ' n1["zz top"]\n'
- " n0 -->|points_at| n1\n"
- )
+ assert g.graph_export("mermaid", "ns") == ('graph LR\n n1["zz top"]\n n0 -->|points_at| n1\n')
def test_dot_escapes_backslashes():
@@ -189,16 +174,9 @@ def test_isolated_nodes_are_declared():
g.add_node("ns", "lonely")
g.add_edge("ns", "a", "next", "b")
- assert g.graph_export("mermaid", "ns") == (
- "graph LR\n"
- " lonely\n"
- " a -->|next| b\n"
- )
+ assert g.graph_export("mermaid", "ns") == ("graph LR\n lonely\n a -->|next| b\n")
assert g.graph_export("dot", "ns") == (
- "digraph G {\n"
- ' "lonely";\n'
- ' "a" -> "b" [label="next"];\n'
- "}\n"
+ 'digraph G {\n "lonely";\n "a" -> "b" [label="next"];\n}\n'
)
@@ -208,8 +186,7 @@ def test_relation_filter_keeps_only_matching_edges():
g.add_edge("ns", "a", "owns", "c")
assert g.graph_export("mermaid", "ns", roots=["a"], relation="next") == (
- "graph LR\n"
- " a -->|next| b\n"
+ "graph LR\n a -->|next| b\n"
)
diff --git a/tests/test_graph_properties.py b/tests/test_graph_properties.py
index 18ab68f..3b404aa 100644
--- a/tests/test_graph_properties.py
+++ b/tests/test_graph_properties.py
@@ -165,4 +165,3 @@ def test_add_node_partial_update_preserves_unspecified_attributes(store):
node_after_ntype = store.get_node("ns", "user")
assert node_after_ntype["ntype"] == "Admin"
assert node_after_ntype["props"] == {"age": Decimal("31"), "city": "NYC"}
-
diff --git a/tests/test_haystack.py b/tests/test_haystack.py
index b92a5d7..35dc5c0 100644
--- a/tests/test_haystack.py
+++ b/tests/test_haystack.py
@@ -1,4 +1,5 @@
"""Tests for the Haystack integration."""
+
# ruff: noqa: E402
import pytest
@@ -85,6 +86,7 @@ def test_write_documents_with_embedding():
assert dynavec_document.metadata == {"category": "account"}
assert dynavec_document.vector == [0.1, 0.2, 0.3]
+
def test_write_documents_overwrite_existing():
client = _FakeClient()
store = DynavecDocumentStore(client, namespace="kb")
@@ -95,9 +97,7 @@ def test_write_documents_overwrite_existing():
meta={"category": "account"},
)
- client.get = lambda ids, **kwargs: [
- type("Result", (), {"id": "doc-1"})()
- ]
+ client.get = lambda ids, **kwargs: [type("Result", (), {"id": "doc-1"})()]
count = store.write_documents(
[document],
@@ -113,42 +113,44 @@ def test_write_documents_overwrite_existing():
assert documents[0].text == "Updated password instructions"
assert kwargs == {"namespace": "kb"}
+
def test_filter_documents():
client = _FakeClient()
store = DynavecDocumentStore(client, namespace="kb")
- client.list_vectors = lambda **kwargs: iter([
- type(
- "Result",
- (),
- {
- "id": "doc-1",
- "text": "Password reset",
- "metadata": {"category": "account"},
- "vector": None,
- },
- )(),
- type(
- "Result",
- (),
- {
- "id": "doc-2",
- "text": "Home loan details",
- "metadata": {"category": "loan"},
- "vector": None,
- },
- )(),
- ])
-
- documents = store.filter_documents(
- filters={"category": "account"}
+ client.list_vectors = lambda **kwargs: iter(
+ [
+ type(
+ "Result",
+ (),
+ {
+ "id": "doc-1",
+ "text": "Password reset",
+ "metadata": {"category": "account"},
+ "vector": None,
+ },
+ )(),
+ type(
+ "Result",
+ (),
+ {
+ "id": "doc-2",
+ "text": "Home loan details",
+ "metadata": {"category": "loan"},
+ "vector": None,
+ },
+ )(),
+ ]
)
+ documents = store.filter_documents(filters={"category": "account"})
+
assert len(documents) == 1
assert documents[0].id == "doc-1"
assert documents[0].content == "Password reset"
assert documents[0].meta == {"category": "account"}
+
def test_retriever():
client = _FakeClient()
@@ -169,6 +171,7 @@ def test_retriever():
assert result["documents"][0].id == "doc-1"
assert result["documents"][0].content == "Password reset instructions"
+
def test_retriever_passes_top_k_and_filters():
client = _FakeClient()
client.search_calls = []
@@ -199,6 +202,7 @@ def search(**kwargs):
assert call["namespace"] == "support"
assert call["filter"] == {"category": "support"}
+
def test_retriever_overrides_default_top_k():
client = _FakeClient()
client.search_calls = []
@@ -218,6 +222,7 @@ def search(**kwargs):
assert client.search_calls[0]["top_k"] == 3
+
def test_retriever_with_filters():
client = _FakeClient()
client.search_calls = []
@@ -270,6 +275,7 @@ def search(**kwargs):
assert client.search_calls[0]["filter"] == {"category": "support"}
+
def test_document_store_serialization():
client = _FakeClient()
store = DynavecDocumentStore(client, namespace="kb")
@@ -280,6 +286,7 @@ def test_document_store_serialization():
assert data["init_parameters"]["namespace"] == "kb"
assert "config" in data["init_parameters"]
+
def test_document_store_from_dict(monkeypatch):
client = _FakeClient()
store = DynavecDocumentStore(client, namespace="kb")
@@ -295,32 +302,35 @@ def test_document_store_from_dict(monkeypatch):
assert restored.namespace == "kb"
+
def test_filter_documents_with_haystack_filter():
client = _FakeClient()
store = DynavecDocumentStore(client, namespace="kb")
- client.list_vectors = lambda **kwargs: iter([
- type(
- "Result",
- (),
- {
- "id": "doc-1",
- "text": "Password reset",
- "metadata": {"category": "account"},
- "vector": None,
- },
- )(),
- type(
- "Result",
- (),
- {
- "id": "doc-2",
- "text": "Home loan details",
- "metadata": {"category": "loan"},
- "vector": None,
- },
- )(),
- ])
+ client.list_vectors = lambda **kwargs: iter(
+ [
+ type(
+ "Result",
+ (),
+ {
+ "id": "doc-1",
+ "text": "Password reset",
+ "metadata": {"category": "account"},
+ "vector": None,
+ },
+ )(),
+ type(
+ "Result",
+ (),
+ {
+ "id": "doc-2",
+ "text": "Home loan details",
+ "metadata": {"category": "loan"},
+ "vector": None,
+ },
+ )(),
+ ]
+ )
documents = store.filter_documents(
filters={
diff --git a/tests/test_hot_tier.py b/tests/test_hot_tier.py
index 73019b0..27163bc 100644
--- a/tests/test_hot_tier.py
+++ b/tests/test_hot_tier.py
@@ -69,7 +69,8 @@ def query(self, query_vector, top_k, filter=None, return_metadata=True, return_d
def get_vectors(self, keys, return_metadata=False):
return {
k: {"vector": self._store[k][0], "metadata": self._store[k][1]}
- for k in keys if k in self._store
+ for k in keys
+ if k in self._store
}
def list_pages(self, return_data=False, return_metadata=False, page_size=None):
@@ -117,6 +118,7 @@ def _make(monkeypatch, **cfg_kw):
# --------------------------------------------------------------------- matcher
+
def test_matches_supported_operators():
m = {"cat": "food", "year": 2026, "score": 0.4}
assert matches(m, {"cat": "food"})
@@ -135,6 +137,7 @@ def test_matches_rejects_unsupported_operator():
# ---------------------------------------------------------------- integration
+
def test_disabled_by_default_uses_s3(monkeypatch):
db = _make(monkeypatch)
assert db._hot is None
@@ -161,10 +164,10 @@ def test_warm_serves_from_ram_without_touching_s3_or_ddb(monkeypatch):
hits = db.search("apple", top_k=2)
assert len(hits) == 2
- assert hits[0].text is not None # text served from RAM
+ assert hits[0].text is not None # text served from RAM
assert hits[0].score >= hits[1].score
- assert db._vectors.query_calls == s3_before # no S3 Vectors query
- assert db._docs.get_calls == ddb_before # no DynamoDB hydration
+ assert db._vectors.query_calls == s3_before # no S3 Vectors query
+ assert db._docs.get_calls == ddb_before # no DynamoDB hydration
def test_write_through_keeps_warmed_namespace_current(monkeypatch):
@@ -176,7 +179,7 @@ def test_write_through_keeps_warmed_namespace_current(monkeypatch):
db.upsert([Document(id="2", text="apple tart")])
hits = db.search("apple tart", top_k=2)
assert {h.id for h in hits} == {"1", "2"}
- assert db._vectors.query_calls == s3_before # still served from RAM
+ assert db._vectors.query_calls == s3_before # still served from RAM
def test_filter_on_hot_path(monkeypatch):
@@ -191,7 +194,7 @@ def test_filter_on_hot_path(monkeypatch):
s3_before = db._vectors.query_calls
hits = db.search("apple", top_k=5, filter={"cat": "space"})
assert {h.id for h in hits} == {"2"}
- assert db._vectors.query_calls == s3_before # filtered in RAM
+ assert db._vectors.query_calls == s3_before # filtered in RAM
def test_unsupported_filter_falls_back_to_s3(monkeypatch):
@@ -204,7 +207,7 @@ def test_unsupported_filter_falls_back_to_s3(monkeypatch):
assert db._hot.search("default", [0.0] * 8, 5, {"n": {"$regex": "3"}}) is None
s3_before = db._vectors.query_calls
db.search("apple", top_k=5, filter={"n": {"$regex": "3"}})
- assert db._vectors.query_calls == s3_before + 1 # fell back to S3
+ assert db._vectors.query_calls == s3_before + 1 # fell back to S3
def test_delete_removes_from_hot_tier(monkeypatch):
@@ -215,7 +218,7 @@ def test_delete_removes_from_hot_tier(monkeypatch):
s3_before = db._vectors.query_calls
hits = db.search("apple", top_k=5)
assert {h.id for h in hits} == {"2"}
- assert db._vectors.query_calls == s3_before # still hot, id 1 gone
+ assert db._vectors.query_calls == s3_before # still hot, id 1 gone
def test_capacity_cap_falls_back_to_s3(monkeypatch):
@@ -225,7 +228,7 @@ def test_capacity_cap_falls_back_to_s3(monkeypatch):
assert loaded == 0
assert not db._hot.is_authoritative("default")
hits = db.search("doc", top_k=3)
- assert db._vectors.query_calls >= 1 # fell back to S3
+ assert db._vectors.query_calls >= 1 # fell back to S3
assert hits
@@ -266,7 +269,9 @@ def test_hot_stats(monkeypatch):
def test_hot_tier_lru_eviction(monkeypatch):
db = _make(monkeypatch, hot_tier=True, hot_tier_max_vectors=3, hot_tier_eviction="lru")
- db.upsert([Document(id="a1", text="apple 1"), Document(id="a2", text="apple 2")], namespace="ns_a")
+ db.upsert(
+ [Document(id="a1", text="apple 1"), Document(id="a2", text="apple 2")], namespace="ns_a"
+ )
db.upsert([Document(id="b1", text="banana 1")], namespace="ns_b")
db.upsert([Document(id="c1", text="cherry 1")], namespace="ns_c")
@@ -292,7 +297,9 @@ def test_hot_tier_lru_eviction(monkeypatch):
def test_hot_tier_fifo_eviction(monkeypatch):
db = _make(monkeypatch, hot_tier=True, hot_tier_max_vectors=3, hot_tier_eviction="fifo")
- db.upsert([Document(id="a1", text="apple 1"), Document(id="a2", text="apple 2")], namespace="ns_a")
+ db.upsert(
+ [Document(id="a1", text="apple 1"), Document(id="a2", text="apple 2")], namespace="ns_a"
+ )
db.upsert([Document(id="b1", text="banana 1")], namespace="ns_b")
db.upsert([Document(id="c1", text="cherry 1")], namespace="ns_c")
@@ -315,7 +322,9 @@ def test_hot_tier_fifo_eviction(monkeypatch):
def test_hot_tier_none_eviction(monkeypatch):
db = _make(monkeypatch, hot_tier=True, hot_tier_max_vectors=3, hot_tier_eviction="none")
- db.upsert([Document(id="a1", text="apple 1"), Document(id="a2", text="apple 2")], namespace="ns_a")
+ db.upsert(
+ [Document(id="a1", text="apple 1"), Document(id="a2", text="apple 2")], namespace="ns_a"
+ )
db.upsert([Document(id="b1", text="banana 1")], namespace="ns_b")
db.upsert([Document(id="c1", text="cherry 1")], namespace="ns_c")
@@ -356,7 +365,9 @@ def test_hot_tier_insert_many_evicts_cold_namespace(monkeypatch):
# Now upsert 2 new docs into ns_b. Total vectors for ns_b will be 3.
# ns_a (1 vector) + ns_b (3 vectors) = 4 > 3.
# ns_a should be evicted, and ns_b should remain authoritative with 3 resident vectors.
- db.upsert([Document(id="b2", text="banana 2"), Document(id="b3", text="banana 3")], namespace="ns_b")
+ db.upsert(
+ [Document(id="b2", text="banana 2"), Document(id="b3", text="banana 3")], namespace="ns_b"
+ )
assert not db._hot.is_authoritative("ns_a")
assert db._hot.is_authoritative("ns_b")
assert db.hot_stats()["resident_vectors"] == 3
diff --git a/tests/test_huggingface_embedder.py b/tests/test_huggingface_embedder.py
index ac2f35d..49f68d6 100644
--- a/tests/test_huggingface_embedder.py
+++ b/tests/test_huggingface_embedder.py
@@ -1,6 +1,7 @@
"""Unit tests for HFInferenceEmbedder."""
from unittest.mock import MagicMock, patch
+
import pytest
from dynavec.embeddings import HFInferenceEmbedder
@@ -44,4 +45,4 @@ def test_embed_documents_batching(mock_post):
def test_empty_input():
emb = HFInferenceEmbedder(api_key="fake_token")
- assert emb.embed_documents([]) == []
\ No newline at end of file
+ assert emb.embed_documents([]) == []
diff --git a/tests/test_list_vectors.py b/tests/test_list_vectors.py
index 8ffdea4..9b2d7e2 100644
--- a/tests/test_list_vectors.py
+++ b/tests/test_list_vectors.py
@@ -258,9 +258,7 @@ def test_list_vectors_hydrates_text_and_metadata():
assert result.distance is None
assert result.vector is None
# hydrating means we do not pay for metadata on the S3 Vectors side
- assert db._vectors.calls == [
- dict(return_data=False, return_metadata=False, page_size=None)
- ]
+ assert db._vectors.calls == [dict(return_data=False, return_metadata=False, page_size=None)]
def test_list_vectors_without_hydration_uses_s3_metadata():
@@ -278,9 +276,7 @@ def test_list_vectors_without_hydration_uses_s3_metadata():
assert docs.calls == [] # DynamoDB is never touched
assert result.text == "mirrored"
assert result.metadata == {"cat": "food"} # internal tags stripped
- assert db._vectors.calls == [
- dict(return_data=False, return_metadata=True, page_size=None)
- ]
+ assert db._vectors.calls == [dict(return_data=False, return_metadata=True, page_size=None)]
def test_list_vectors_without_hydration_tolerates_missing_metadata():
diff --git a/tests/test_markdown_source.py b/tests/test_markdown_source.py
index 304febf..7c1c77c 100644
--- a/tests/test_markdown_source.py
+++ b/tests/test_markdown_source.py
@@ -115,6 +115,7 @@ def test_root_must_be_an_existing_directory(tmp_path):
def test_empty_directory_yields_no_records(tmp_path):
assert list(MarkdownSource(tmp_path)) == []
+
def test_front_matter_dates_normalize_to_iso_strings(tmp_path):
(tmp_path / "notes.md").write_text(
"---\ntitle: Research Notes\ndate: 2026-09-24\n---\nBody\n",
@@ -188,7 +189,6 @@ def test_front_matter_dates_survive_dynamodb_serialization(tmp_path):
assert serialized["M"]["date"] == {"S": "2026-09-24"}
-
def test_markdown_source_flows_through_ingest(tmp_path):
(tmp_path / "guide.md").write_text("---\ntopic: aws\n---\nabcdefghij", encoding="utf-8")
db = Mock()
diff --git a/tests/test_mcp_server.py b/tests/test_mcp_server.py
index 564f0b4..8957a2d 100644
--- a/tests/test_mcp_server.py
+++ b/tests/test_mcp_server.py
@@ -111,7 +111,9 @@ def test_client_from_env_embedder_resolution(monkeypatch):
monkeypatch.setattr(gemini_mod, "GeminiEmbedder", lambda **kw: MagicMock(dimension=768))
monkeypatch.setattr(voyage_mod, "VoyageEmbedder", lambda **kw: MagicMock(dimension=1024))
monkeypatch.setattr(mistral_mod, "MistralEmbedder", lambda **kw: MagicMock(dimension=1024))
- monkeypatch.setattr(st_mod, "SentenceTransformerEmbedder", lambda **kw: MagicMock(dimension=384))
+ monkeypatch.setattr(
+ st_mod, "SentenceTransformerEmbedder", lambda **kw: MagicMock(dimension=384)
+ )
base_env = {
"DYNAVEC_BUCKET": "b",
@@ -175,7 +177,7 @@ def test_mcp_server_search_tool(fake_mcp):
rescore="dot",
rerank="mmr",
)
- assert "[1] id: doc-1 (score: 0.9500 | metadata: {\"topic\": \"greeting\"})" in result_text
+ assert '[1] id: doc-1 (score: 0.9500 | metadata: {"topic": "greeting"})' in result_text
assert "Hello world" in result_text
assert "[2] id: doc-2 (score: 0.8200)" in result_text
@@ -197,7 +199,9 @@ def test_mcp_server_search_tool_empty_and_error(fake_mcp):
def test_mcp_server_graph_search_tool(fake_mcp):
mock_db = MagicMock()
mock_db.graph_search.return_value = [
- SearchResult(id="doc-graph", score=0.91, text="Graph entity content", metadata={"entity": "acme"}),
+ SearchResult(
+ id="doc-graph", score=0.91, text="Graph entity content", metadata={"entity": "acme"}
+ ),
]
mcp = create_mcp_server(mock_db)
@@ -225,7 +229,163 @@ def test_mcp_server_graph_search_tool(fake_mcp):
def test_cli_mcp_subcommand_parser():
parser = _parser()
- args = parser.parse_args(["mcp", "--transport", "sse", "--port", "9000"])
+
+ args = parser.parse_args(
+ [
+ "mcp",
+ "--transport",
+ "sse",
+ "--port",
+ "9000",
+ "--enable-write",
+ ]
+ )
+
assert args.command == "mcp"
assert args.transport == "sse"
assert args.port == 9000
+ assert args.enable_write is True
+
+ # Verify write access is disabled by default.
+ default_args = parser.parse_args(["mcp"])
+
+ assert default_args.enable_write is False
+
+
+def test_write_tools_hidden_by_default(fake_mcp):
+ mock_db = MagicMock()
+
+ mcp = create_mcp_server(db=mock_db)
+
+ assert "dynavec_search" in mcp.tools
+ assert "dynavec_graph_search" in mcp.tools
+
+ assert "dynavec_remember" not in mcp.tools
+ assert "dynavec_get" not in mcp.tools
+ assert "dynavec_forget" not in mcp.tools
+
+
+def test_write_tools_registered_with_enable_write(fake_mcp):
+ mock_db = MagicMock()
+
+ mcp = create_mcp_server(
+ db=mock_db,
+ enable_write=True,
+ )
+
+ assert "dynavec_search" in mcp.tools
+ assert "dynavec_graph_search" in mcp.tools
+
+ assert "dynavec_remember" in mcp.tools
+ assert "dynavec_get" in mcp.tools
+ assert "dynavec_forget" in mcp.tools
+
+
+def test_remember_calls_upsert_with_metadata_and_ttl(fake_mcp):
+ mock_db = MagicMock()
+
+ mcp = create_mcp_server(
+ db=mock_db,
+ enable_write=True,
+ )
+
+ remember_fn = mcp.tools["dynavec_remember"].fn
+
+ result = remember_fn(
+ text="Remember this important information",
+ doc_id="memory-001",
+ namespace="test-namespace",
+ metadata_json='{"category": "notes", "source": "test"}',
+ ttl_seconds=3600,
+ )
+
+ mock_db.upsert.assert_called_once()
+
+ args, kwargs = mock_db.upsert.call_args
+ documents = args[0]
+
+ assert len(documents) == 1
+
+ document = documents[0]
+ assert document.id == "memory-001"
+ assert document.text == "Remember this important information"
+ assert document.metadata == {
+ "category": "notes",
+ "source": "test",
+ }
+ assert document.ttl_seconds == 3600
+
+ assert kwargs["namespace"] == "test-namespace"
+ assert kwargs["ttl_seconds"] == 3600
+
+ assert "Successfully remembered" in result
+
+
+def test_remember_rejects_bad_metadata_json(fake_mcp):
+ mock_db = MagicMock()
+
+ mcp = create_mcp_server(
+ db=mock_db,
+ enable_write=True,
+ )
+
+ remember_fn = mcp.tools["dynavec_remember"].fn
+
+ result = remember_fn(
+ text="Test memory",
+ metadata_json='{"category":',
+ )
+
+ assert "Error parsing metadata_json" in result
+ mock_db.upsert.assert_not_called()
+
+
+def test_get_and_forget_forward_ids_and_namespace(fake_mcp):
+ mock_db = MagicMock()
+
+ mock_db.get.return_value = [
+ SearchResult(
+ id="doc-1",
+ score=1.0,
+ text="First document",
+ metadata={"type": "test"},
+ ),
+ SearchResult(
+ id="doc-2",
+ score=0.9,
+ text="Second document",
+ metadata={"type": "test"},
+ ),
+ ]
+
+ mcp = create_mcp_server(
+ db=mock_db,
+ enable_write=True,
+ )
+
+ get_fn = mcp.tools["dynavec_get"].fn
+ forget_fn = mcp.tools["dynavec_forget"].fn
+
+ ids = ["doc-1", "doc-2"]
+ namespace = "test-namespace"
+
+ get_result = get_fn(
+ ids=ids,
+ namespace=namespace,
+ )
+
+ mock_db.get.assert_called_once_with(ids, namespace)
+
+ assert "doc-1" in get_result
+ assert "First document" in get_result
+ assert "doc-2" in get_result
+ assert "Second document" in get_result
+
+ forget_result = forget_fn(
+ ids=ids,
+ namespace=namespace,
+ )
+
+ mock_db.delete.assert_called_once_with(ids, namespace)
+
+ assert "Successfully deleted 2 document(s)" in forget_result
diff --git a/tests/test_metadata.py b/tests/test_metadata.py
index 82b46ca..79db0b0 100644
--- a/tests/test_metadata.py
+++ b/tests/test_metadata.py
@@ -166,14 +166,12 @@ def test_split_text_mirror_optional():
# None and empty filter
(None, "default", {NS_METADATA_KEY: "default"}),
({}, "production", {NS_METADATA_KEY: "production"}),
-
# Bare equality
(
{"genre": "scifi"},
"ns1",
{"$and": [{"genre": "scifi"}, {NS_METADATA_KEY: "ns1"}]},
),
-
# $eq operator
(
{"status": {"$eq": "active"}},
@@ -185,7 +183,6 @@ def test_split_text_mirror_optional():
]
},
),
-
# $ne operator
(
{"archived": {"$ne": True}},
@@ -197,7 +194,6 @@ def test_split_text_mirror_optional():
]
},
),
-
# Numeric comparison operators ($gte, $gt, $lte, $lt)
(
{"rating": {"$gte": 4.5}},
@@ -229,7 +225,6 @@ def test_split_text_mirror_optional():
]
},
),
-
# $in and $nin operators
(
{"tag": {"$in": ["python", "aws", "vector"]}},
@@ -251,7 +246,6 @@ def test_split_text_mirror_optional():
]
},
),
-
# $or operator combinations
(
{"$or": [{"category": "news"}, {"category": "tech"}]},
@@ -295,11 +289,7 @@ def test_split_text_mirror_optional():
"$and": [
{
"$or": [
- {
- "category": {
- "$in": ["electronics", "computers"]
- }
- },
+ {"category": {"$in": ["electronics", "computers"]}},
{"discount": {"$gte": 0.2}},
]
},
@@ -307,7 +297,6 @@ def test_split_text_mirror_optional():
]
},
),
-
# Top-level $and list extension (should not double wrap)
(
{"$and": [{"a": 1}]},
@@ -330,7 +319,6 @@ def test_split_text_mirror_optional():
]
},
),
-
# Complex nested $and + $or + $in + $gte combinations
(
{
diff --git a/tests/test_metric_properties.py b/tests/test_metric_properties.py
index a5c26dc..9257573 100644
--- a/tests/test_metric_properties.py
+++ b/tests/test_metric_properties.py
@@ -197,7 +197,9 @@ def test_euclidean_and_manhattan_distance_monotonicity(vec_pair, scale_a, delta)
for metric in ("euclidean", "manhattan"):
scores = score(q, mat, metric)
# Closer candidate (near) must have strictly higher similarity score than farther candidate
- assert scores[0] > scores[1], f"Metric {metric} failed monotonicity: {scores[0]} <= {scores[1]}"
+ assert scores[0] > scores[1], (
+ f"Metric {metric} failed monotonicity: {scores[0]} <= {scores[1]}"
+ )
@given(
@@ -297,7 +299,9 @@ def test_normalize_scores_bounds_and_order_preservation(scores):
scores=arrays(
dtype=np.float32,
shape=st.integers(min_value=2, max_value=20),
- elements=st.floats(min_value=-100.0, max_value=100.0, allow_nan=False, allow_infinity=False),
+ elements=st.floats(
+ min_value=-100.0, max_value=100.0, allow_nan=False, allow_infinity=False
+ ),
),
scale=st.floats(min_value=0.1, max_value=50.0, allow_nan=False, allow_infinity=False),
shift=st.floats(min_value=-50.0, max_value=50.0, allow_nan=False, allow_infinity=False),
diff --git a/tests/test_namespace.py b/tests/test_namespace.py
index 12cfece..e3a1434 100644
--- a/tests/test_namespace.py
+++ b/tests/test_namespace.py
@@ -21,11 +21,15 @@ def embed_documents(self, texts):
v[i % self.dimension] += (ord(ch) % 17) / 17.0
out.append(v)
return out
+
+
def _cosine_distance(a, b):
dot = sum(x * y for x, y in zip(a, b))
na = math.sqrt(sum(x * x for x in a)) or 1e-12
nb = math.sqrt(sum(y * y for y in b)) or 1e-12
return 1.0 - dot / (na * nb)
+
+
class FakeS3(client_mod.S3VectorsStore):
def __init__(self, config, boto_session=None):
self.config = config
@@ -70,12 +74,17 @@ def query_pages(
yield hits[i : i + chunk_size]
def get_vectors(self, keys, return_metadata=False):
- return {k: {"vector": self._store[k][0], "metadata": self._store[k][1]} for k in keys if k in self._store}
+ return {
+ k: {"vector": self._store[k][0], "metadata": self._store[k][1]}
+ for k in keys
+ if k in self._store
+ }
def delete_vectors(self, keys):
for k in keys:
self._store.pop(k, None)
+
class FakeDDB(client_mod.DynamoDBStore):
def __init__(self, config, boto_session=None):
self.config = config
@@ -91,6 +100,8 @@ def get_many(self, namespace, ids):
def delete_many(self, namespace, ids):
for i in ids:
self._store.pop((namespace, i), None)
+
+
class FakeGraph(client_mod.GraphStore):
def __init__(self, config, boto_session=None):
self.config = config
@@ -166,6 +177,8 @@ def get_docs(self, ns, entity_ids):
seen.add(d)
out.append(d)
return out
+
+
@pytest.fixture
def db(monkeypatch):
monkeypatch.setattr(client_mod, "S3VectorsStore", FakeS3)
@@ -174,11 +187,15 @@ def db(monkeypatch):
cfg = DynavecConfig(vector_bucket="b", index="i", table="t", dimension=8)
return Dynavec(cfg, embedder=HashEmbedder(8))
+
+
def test_search_many_forwards_multiple_queries_with_namespace_isolation(db):
kb = db.namespace("kb")
other = db.namespace("other")
kb.upsert([Document(id="1", text="apple"), Document(id="2", text="rocket")])
- other.upsert([Document(id="other-apple", text="apple"), Document(id="other-rocket", text="rocket")])
+ other.upsert(
+ [Document(id="other-apple", text="apple"), Document(id="other-rocket", text="rocket")]
+ )
results = kb.search_many(["apple", "rocket"], top_k=1)
@@ -207,6 +224,7 @@ def test_search_many_empty_batch(db):
assert kb.search_many([]) == []
+
@pytest.mark.parametrize("explain", [False, True])
def test_search_many_dynamic_explain_preserves_namespace_and_order(db, explain):
kb = db.namespace("kb")
diff --git a/tests/test_nodes.py b/tests/test_nodes.py
index f33aa3a..d9b2dde 100644
--- a/tests/test_nodes.py
+++ b/tests/test_nodes.py
@@ -397,9 +397,7 @@ def flaky_fn(inputs: dict[str, Any]) -> dict[str, Any]:
return {"result": inputs["x"] * 10}
policy = RetryPolicy(max_attempts=4, base_delay=0.001, max_delay=0.01)
- flaky_node = CodeNode(
- code_fn=flaky_fn, node_id="flaky_node", retry_policy=policy
- )
+ flaky_node = CodeNode(code_fn=flaky_fn, node_id="flaky_node", retry_policy=policy)
graph = SimpleGraph()
graph.add_node(flaky_node)
@@ -420,9 +418,7 @@ def always_failing_fn(inputs: dict[str, Any]) -> dict[str, Any]:
raise RuntimeError("Hard database failure")
policy = RetryPolicy(max_attempts=3, base_delay=0.001, max_delay=0.01)
- failing_node = CodeNode(
- code_fn=always_failing_fn, node_id="fail_node", retry_policy=policy
- )
+ failing_node = CodeNode(code_fn=always_failing_fn, node_id="fail_node", retry_policy=policy)
graph = SimpleGraph()
graph.add_node(failing_node)
diff --git a/tests/test_openai_embeddings.py b/tests/test_openai_embeddings.py
index a3fc8dd..ea5ee0f 100644
--- a/tests/test_openai_embeddings.py
+++ b/tests/test_openai_embeddings.py
@@ -1,4 +1,5 @@
"""Tests for the OpenAI embedder retry behavior."""
+
from types import SimpleNamespace
import pytest
@@ -32,9 +33,7 @@ def __init__(self, error: Exception):
@pytest.mark.parametrize("dimensions", [None, 2])
-def test_openai_embedder_retries_rate_limit_and_respects_retry_after(
- monkeypatch, dimensions
-):
+def test_openai_embedder_retries_rate_limit_and_respects_retry_after(monkeypatch, dimensions):
class RateLimitError(Exception):
status_code = 429
@@ -64,6 +63,7 @@ def __init__(self):
expected_request["dimensions"] = dimensions
assert fake_client.embeddings.requests == [expected_request, expected_request]
+
def test_openai_embedder_retries_server_error(monkeypatch):
class ServerError(Exception):
status_code = 500
@@ -81,6 +81,7 @@ class ServerError(Exception):
assert fake_client.embeddings.calls == 2
assert len(delays) == 1
+
def test_openai_embedder_does_not_retry_client_error(monkeypatch):
class ClientError(Exception):
status_code = 400
@@ -99,6 +100,7 @@ class ClientError(Exception):
assert fake_client.embeddings.calls == 1
assert delays == []
+
def _make_embedder(error):
fake_client = _FakeClient(error)
diff --git a/tests/test_provisioning.py b/tests/test_provisioning.py
index f5c908a..397cc7f 100644
--- a/tests/test_provisioning.py
+++ b/tests/test_provisioning.py
@@ -25,16 +25,10 @@ def test_ensure_table_creates_expected_key_schema():
ensure_table(config, session)
- table = session.client("dynamodb").describe_table(
- TableName="test-table"
- )["Table"]
+ table = session.client("dynamodb").describe_table(TableName="test-table")["Table"]
- assert table["KeySchema"] == [
- {"AttributeName": "pk", "KeyType": "HASH"}
- ]
- assert table["AttributeDefinitions"] == [
- {"AttributeName": "pk", "AttributeType": "S"}
- ]
+ assert table["KeySchema"] == [{"AttributeName": "pk", "KeyType": "HASH"}]
+ assert table["AttributeDefinitions"] == [{"AttributeName": "pk", "AttributeType": "S"}]
def test_ensure_index_marks_text_mirror_non_filterable():
@@ -60,9 +54,7 @@ def test_ensure_index_marks_text_mirror_non_filterable():
dataType="float32",
dimension=4,
distanceMetric="cosine",
- metadataConfiguration={
- "nonFilterableMetadataKeys": [TEXT_METADATA_KEY]
- },
+ metadataConfiguration={"nonFilterableMetadataKeys": [TEXT_METADATA_KEY]},
)
diff --git a/tests/test_quantization.py b/tests/test_quantization.py
index a7946a1..e460cc4 100644
--- a/tests/test_quantization.py
+++ b/tests/test_quantization.py
@@ -196,6 +196,7 @@ def test_load_corrupted_file_raises(tmp_path):
with pytest.raises(ValueError):
ProductQuantizer.load(corrupt)
+
def test_opq_rotation_fit():
rng = np.random.default_rng(42)
diff --git a/tests/test_retrievers.py b/tests/test_retrievers.py
index 8c30af3..553206e 100644
--- a/tests/test_retrievers.py
+++ b/tests/test_retrievers.py
@@ -365,7 +365,9 @@ def test_hyde_requires_embedder(monkeypatch):
monkeypatch.setattr(client_mod, "S3VectorsStore", FakeS3)
monkeypatch.setattr(client_mod, "DynamoDBStore", FakeDDB)
monkeypatch.setattr(client_mod, "GraphStore", FakeGraph)
- bare = Dynavec(DynavecConfig(vector_bucket="b", index="i", table="t", dimension=4, region="us-east-1"))
+ bare = Dynavec(
+ DynavecConfig(vector_bucket="b", index="i", table="t", dimension=4, region="us-east-1")
+ )
with pytest.raises(ConfigurationError):
HyDERetriever(bare, lambda q: "x")
diff --git a/tests/test_s3vectors.py b/tests/test_s3vectors.py
index 32e1797..a320e1a 100644
--- a/tests/test_s3vectors.py
+++ b/tests/test_s3vectors.py
@@ -8,38 +8,37 @@
class FakeS3VectorsClient:
- def __init__(self):
- self.calls = []
+ def __init__(self):
+ self.calls = []
- def get_vectors(self, **kwargs):
- self.calls.append(kwargs)
- return {
- "vectors": [
- {"key": key, "data": {"float32": [1.0, 2.0]}}
- for key in kwargs["keys"]
- ]
- }
+ def get_vectors(self, **kwargs):
+ self.calls.append(kwargs)
+ return {
+ "vectors": [{"key": key, "data": {"float32": [1.0, 2.0]}} for key in kwargs["keys"]]
+ }
def test_get_vectors_batches_keys_and_merges_results():
- fake = FakeS3VectorsClient()
- store = S3VectorsStore.__new__(S3VectorsStore)
- store._config = DynavecConfig(vector_bucket="bucket", index="index", table="table", dimension=2)
- store._client = fake
+ fake = FakeS3VectorsClient()
+ store = S3VectorsStore.__new__(S3VectorsStore)
+ store._config = DynavecConfig(vector_bucket="bucket", index="index", table="table", dimension=2)
+ store._client = fake
- keys = [f"key-{i}" for i in range(250)]
- result = store.get_vectors(keys)
+ keys = [f"key-{i}" for i in range(250)]
+ result = store.get_vectors(keys)
- assert [len(call["keys"]) for call in fake.calls] == [100, 100, 50]
- assert all(call["returnData"] is True for call in fake.calls)
- assert len(result) == 250
- assert set(result) == set(keys)
+ assert [len(call["keys"]) for call in fake.calls] == [100, 100, 50]
+ assert all(call["returnData"] is True for call in fake.calls)
+ assert len(result) == 250
+ assert set(result) == set(keys)
def _config(**kwargs):
- defaults = dict(vector_bucket="test-bucket", index="test-index", table="test-table", dimension=4)
- defaults.update(kwargs)
- return DynavecConfig(**defaults)
+ defaults = dict(
+ vector_bucket="test-bucket", index="test-index", table="test-table", dimension=4
+ )
+ defaults.update(kwargs)
+ return DynavecConfig(**defaults)
def _store_with_pages(pages, config=None):
@@ -56,17 +55,18 @@ def _store_with_pages(pages, config=None):
def test_query_single_page():
- page = [{"key": f"k{i}", "distance": 0.01 * i} for i in range(50)]
- store, paginator = _store_with_pages([{"vectors": page}])
+ page = [{"key": f"k{i}", "distance": 0.01 * i} for i in range(50)]
+ store, paginator = _store_with_pages([{"vectors": page}])
- results = store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=50)
+ results = store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=50)
+
+ assert len(results) == 50
+ assert results[0]["key"] == "k0"
+ assert results[-1]["key"] == "k49"
+ store._client.get_paginator.assert_called_once_with("query_vectors")
+ assert paginator.paginate.call_args.kwargs["PaginationConfig"] == {"MaxItems": 50}
+ assert paginator.paginate.call_args.kwargs["topK"] == 50
- assert len(results) == 50
- assert results[0]["key"] == "k0"
- assert results[-1]["key"] == "k49"
- store._client.get_paginator.assert_called_once_with("query_vectors")
- assert paginator.paginate.call_args.kwargs["PaginationConfig"] == {"MaxItems": 50}
- assert paginator.paginate.call_args.kwargs["topK"] == 50
def test_query_multi_page_pagination():
pages = [
@@ -98,47 +98,46 @@ def test_query_multi_page_pagination():
"k249",
]
+
def test_query_fewer_results_than_top_k():
- store, _ = _store_with_pages([{"vectors": [{"key": "k0"}, {"key": "k1"}]}])
+ store, _ = _store_with_pages([{"vectors": [{"key": "k0"}, {"key": "k1"}]}])
- results = store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=50)
+ results = store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=50)
- assert len(results) == 2
+ assert len(results) == 2
def test_query_zero_or_negative_top_k():
- store, _ = _store_with_pages([{"vectors": [{"key": "k0"}]}])
+ store, _ = _store_with_pages([{"vectors": [{"key": "k0"}]}])
- assert store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=0) == []
- assert store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=-5) == []
- store._client.get_paginator.assert_not_called()
+ assert store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=0) == []
+ assert store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=-5) == []
+ store._client.get_paginator.assert_not_called()
def test_query_exceeding_service_limit():
- store, _ = _store_with_pages([])
+ store, _ = _store_with_pages([])
- with pytest.raises(ValueError, match="exceeds Amazon S3 Vectors maximum limit"):
- store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=_MAX_TOP_K + 1)
+ with pytest.raises(ValueError, match="exceeds Amazon S3 Vectors maximum limit"):
+ store.query(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=_MAX_TOP_K + 1)
def test_query_pages_invalid_page_size():
- store, _ = _store_with_pages([])
+ store, _ = _store_with_pages([])
- with pytest.raises(ValueError, match="page_size must be a positive integer"):
- list(store.query_pages(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=10, page_size=0))
+ with pytest.raises(ValueError, match="page_size must be a positive integer"):
+ list(store.query_pages(query_vector=[0.1, 0.2, 0.3, 0.4], top_k=10, page_size=0))
def test_config_rejects_non_positive_top_k_page_size():
- with pytest.raises(ValueError, match="top_k_page_size must be a positive integer"):
- _config(top_k_page_size=0)
+ with pytest.raises(ValueError, match="top_k_page_size must be a positive integer"):
+ _config(top_k_page_size=0)
+
def test_put_vectors_parallelization():
store, _ = _store_with_pages([])
- vectors = [
- (f"key_{i}", [0.1] * 128, {"tag": "test"})
- for i in range(1500)
- ]
+ vectors = [(f"key_{i}", [0.1] * 128, {"tag": "test"}) for i in range(1500)]
def mock_put_batch(payload):
time.sleep(0.1)
@@ -156,10 +155,7 @@ def mock_put_batch(payload):
def test_put_vectors_error_propagation():
store, _ = _store_with_pages([])
- vectors = [
- (f"key_{i}", [0.1] * 128, {"tag": "test"})
- for i in range(1000)
- ]
+ vectors = [(f"key_{i}", [0.1] * 128, {"tag": "test"}) for i in range(1000)]
def mock_put_batch_with_error(payload):
if payload[0]["key"] == "key_0":
@@ -242,9 +238,7 @@ def test_query_pages_raw_chunks():
def test_query_pages_configurable_page_size():
- store, _ = _store_with_pages(
- [{"vectors": [{"key": f"k{i}"} for i in range(25)]}]
- )
+ store, _ = _store_with_pages([{"vectors": [{"key": f"k{i}"} for i in range(25)]}])
result_pages = list(
store.query_pages(
@@ -324,4 +318,4 @@ def test_query_pages_does_not_rate_limit_after_paginator_exhaustion():
)
assert [len(page) for page in result_pages] == [1]
- assert limiter.acquire.call_count == 1
\ No newline at end of file
+ assert limiter.acquire.call_count == 1
diff --git a/tests/test_telemetry.py b/tests/test_telemetry.py
index 8d52c9a..8880a8e 100644
--- a/tests/test_telemetry.py
+++ b/tests/test_telemetry.py
@@ -78,7 +78,7 @@ def test_aggregate_cache_hit_rate_and_errors():
for e in evs:
e.ts = now - 1
agg = aggregate(evs, window_seconds=3600, now=now)
- assert agg["cache_total"] == 3 # None excluded
+ assert agg["cache_total"] == 3 # None excluded
assert agg["cache_hits"] == 2
assert agg["cache_hit_rate"] == round(100 * 2 / 3, 1)
assert agg["error_rate"] == round(100 * 1 / 5, 2)
diff --git a/tests/test_tool_registry.py b/tests/test_tool_registry.py
index bfac1ce..739924d 100644
--- a/tests/test_tool_registry.py
+++ b/tests/test_tool_registry.py
@@ -120,22 +120,22 @@ def test_python_code_tool() -> None:
def test_mcp_adapter() -> None:
"""Test adapting an MCP session to dynaflow tools."""
mock_session = MagicMock()
-
+
# Mock list_tools
class MockTool:
name = "mcp_math"
description = "MCP math"
inputSchema = {"type": "object", "properties": {"a": {"type": "integer"}}}
-
+
mock_listing = MagicMock()
mock_listing.tools = [MockTool()]
mock_session.list_tools.return_value = mock_listing
-
+
# Mock call_tool
class MockResult:
content = [{"text": "success: 42"}]
isError = False
-
+
mock_session.call_tool.return_value = MockResult()
tools = mcp_tools_from_session(mock_session, tags=["mcp"])
@@ -143,7 +143,7 @@ class MockResult:
assert tools[0].name == "mcp_math"
assert tools[0].description == "MCP math"
assert "mcp" in tools[0].tags
-
+
# Execute
res = tools[0].execute({"a": 42})
assert res == "success: 42"
diff --git a/tests/test_utils_transforms.py b/tests/test_utils_transforms.py
index b6931a1..567e664 100644
--- a/tests/test_utils_transforms.py
+++ b/tests/test_utils_transforms.py
@@ -76,6 +76,7 @@ def test_as_pipeline_coercions():
multi = as_pipeline([lambda c: c, lambda c: c])
assert len(multi) == 2
+
def test_retry_uses_retry_delay(monkeypatch):
calls = {"n": 0}
delays = []