
One forward pass. Typed answers. Calibrated probabilities. Zero tokens generated.


中文文档 · How it works · Data format · Benchmarks · Contributing
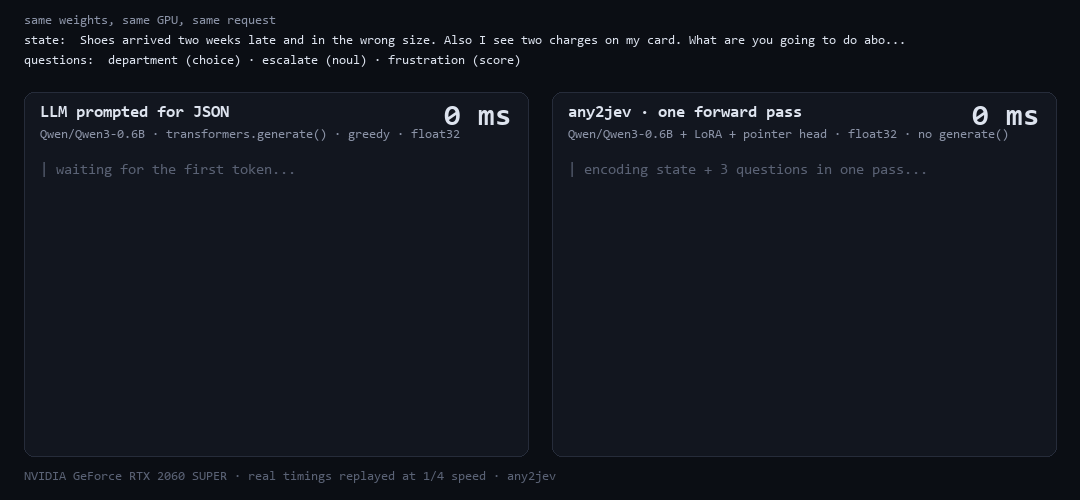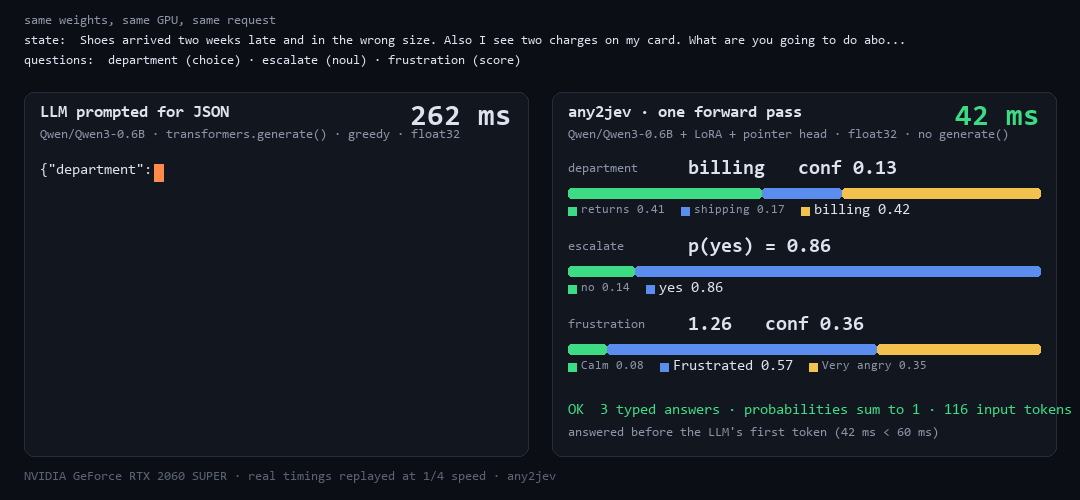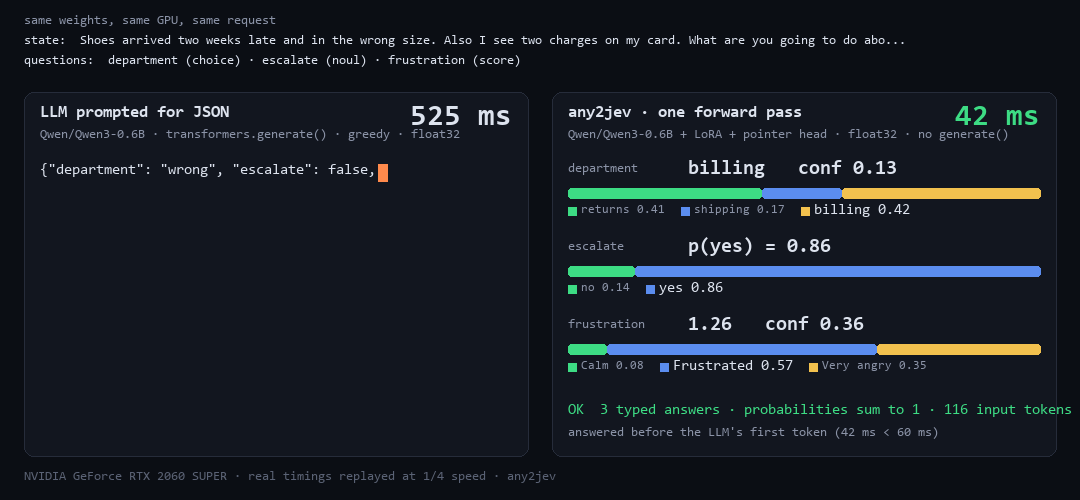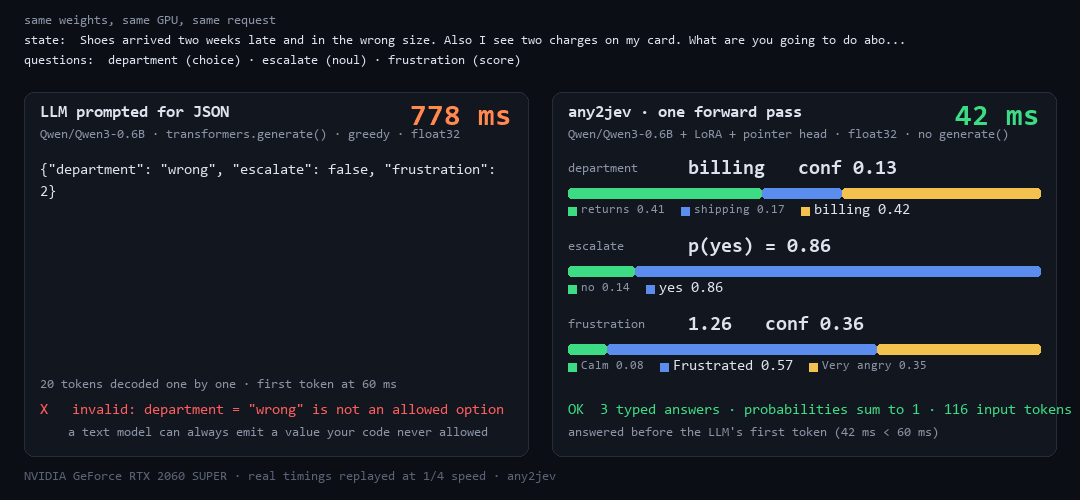
Same Qwen3-0.6B weights · same RTX 2060 SUPER · same request. Left: prompted for JSON, decoded token by token.
Right: after any2jev train. Real timings, replayed at ¼ speed (examples/record_vs.py).
pip install "any2jev[serve]"
any2jev train --base Qwen/Qwen3-0.6B --data train.jsonl --val val.jsonl --out runs/my-jev   # ~1 GPU-hour
any2jev serve runs/my-jev # POST /v1/systemone · the official TypeSafe SDK connects with one base_url changeTypeSafe's Jev made the case: for routing, triage, moderation, ranking, guardrails and game agents you do not need a model that writes, you need one that decides, in milliseconds, with probabilities your code can threshold. Jev's weights are closed. any2jev is the converter: any Hugging Face causal LM plus a few thousand labelled decisions becomes a model that answers Choice / Score / Noul questions in one pass.
| approach | how it answers | latency¹ | format failures² | accuracy² | ECE² | peak VRAM | GPU-hours / 1M requests |
|---|---|---|---|---|---|---|---|
| GPT-4o-class API, JSON mode | cloud round trip, token by token | seconds³ | valid JSON, values unchecked | — | — | cloud | per-token billing |
| Qwen/Qwen3-0.6B, prompted for JSON | generate(), token by token |
778 ms | 0.1% | 0.621 | none (no probabilities) | 2.3 GB | ~216 h |
| Qwen/Qwen3-0.6B, label-logit reading | one prefill per question, no training | 137 ms | 0% | 0.531 | 0.111 | 2.3 GB | ~38 h |
| any2jev on Qwen/Qwen3-0.6B | one forward pass, all questions at once | 42 ms | 0% by construction | 0.796 | 0.027 | 2.8 GB | ~12 h |
¹ The same 3-question support ticket on one NVIDIA GeForce RTX 2060 SUPER, fp32, median of repeated runs (examples/record_vs.py).
² 1,000 held-out questions (boolq, ag_news, banking77, sst5); any2jev eval and examples/baseline_*.py read the same file.
³ Not measured here. TypeSafe's launch post reports 3 to 329 s end to end for frontier models; run examples/bench_cloud.py with your own key to fill this row with a real number.
Every number above comes from a script in this repository. No cloud model was measured here, so the first row carries no numbers; the script to fill it is included.
                 ┌─────────────────────── one forward pass ───────────────────────┐
  state ────────►│ <state> …  │ <q> which team? <opt>billing</opt><opt>shipping</opt> <decide> │──► {billing: 0.91, shipping: 0.09}, confidence 0.82
                 │            │ <q> urgent?     <opt>no</opt><opt>yes</opt>          <decide> │──► noul 0.97
                 │            │ <q> how angry?  <opt>calm</opt> … <opt>furious</opt> <decide> │──► score 1.4, {0: .05, 1: .5, 2: .45}
                 └─────────────── questions see the state, never each other ─────────────────┘
| 🔪 Model surgery | The vocabulary head is dropped; a pointer head scores each option's hidden state against a decision token. Works on any AutoModelForCausalLM; hybrid backbones (Qwen3.5, linear attention) fall back to one causal row per question. |
| 🧱 Block-causal packing | The state is encoded once; every question attends to it and to itself only, so answers never depend on sibling questions. Verified by a test, not a promise. |
| 🎯 Training that targets calibration | LoRA + head + delimiter embeddings; cross-entropy plus optional Brier / ordinal terms; option shuffling for order robustness; then temperature scaling on held-out data. |
| 📏 Evaluation that matches the claims | Accuracy, NLL, Brier, ECE, AURC and coverage-at-risk per question type, an option-order sensitivity test and a packed-vs-separate isolation check. |
| 🔌 Jev-compatible server | POST /v1/systemone and GET /v1/models with TypeSafe's exact wire format. typesafe-sdk runs against it unchanged. |
examples/snake.py generates labelled moves from a BFS teacher, any2jev train turns Qwen3-0.6B into the policy,
and the game loop asks one Choice question per tick over the legal moves. No text is generated.
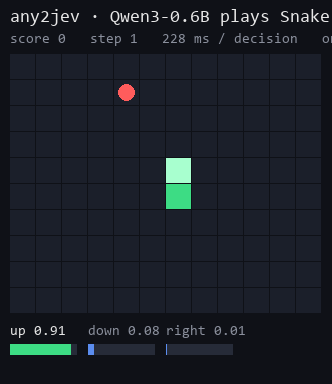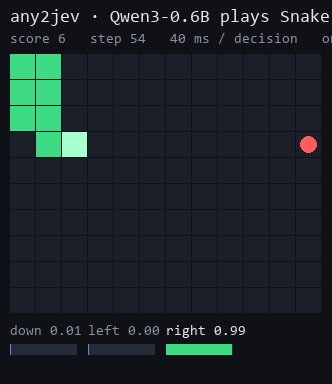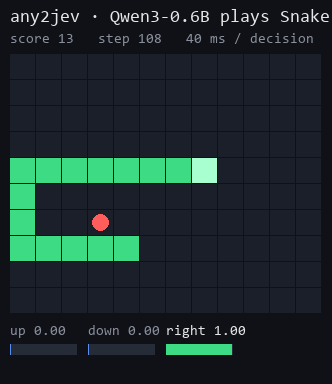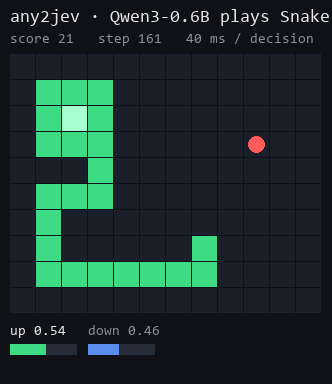
Held-out teacher moves: accuracy 0.953, ECE 0.034, 400 decisions. Recorded game: final score 21 in 161 steps | median latency 41 ms
Pretrained adapters are on the Hugging Face Hub. hf:// works anywhere a checkpoint path does:
pip install "any2jev[serve]"
any2jev ask hf://huaweifeng/any2jev-qwen3-0.6b \
    --state "My payouts have failed 3 days in a row, the bank says everything is fine. Fix this ASAP." \
    --choice "Which team should handle this? | billing, technical, sales" \
    --noul "Does this need urgent human attention?" \
    --score "How frustrated is the customer? | calm, frustrated, furious"
any2jev serve hf://huaweifeng/any2jev-qwen3-0.6b --port 8009| checkpoint | base | trained on | held-out | notes |
|---|---|---|---|---|
huaweifeng/any2jev-qwen3-0.6b |
Qwen3-0.6B | boolq, ag_news, banking77, sst5 (5.4k records) | acc 0.796 · ECE 0.027 | the model behind every number on this page |
huaweifeng/any2jev-qwen3-0.6b-snake |
Qwen3-0.6B | 4k BFS-teacher Snake moves | acc 0.953 | drives examples/snake.py |
huaweifeng/any2jev-qwen3.5-0.8b-synthetic |
Qwen3.5-0.8B (hybrid) | 1.6k synthetic tickets | acc 0.997 | proves the rows-mode recipe on a linear-attention backbone; not a general model |
hf://user/repo@revision also works with train --base, eval and Python's DecisionModel.load().
calibrate edits a local checkpoint in place; copy a Hub checkpoint locally before using it.
Each repo is ~40 MB (LoRA adapter + pointer head + tokenizer + config); the base weights download from their own Hub repo on first use.
For faster inference, add --merge to ask or serve. On the measured 116-token request,
merging reduced median latency from 40.4 to 31.3 ms; see measurement details.
pip install "any2jev[serve]"            # + [data] for public datasets, [compat] for the TypeSafe SDK
# or straight from GitHub:  pip install "any2jev[serve] @ git+https://github.com/hwfengcs/any2jev"

# 1. data: 2,000 synthetic support tickets (no download), or convert public datasets
any2jev data synthetic --out data/synthetic --n 2000
any2jev data build --sources boolq,ag_news,banking77,sst5 --out data/public --n-per-source 1500

# 2. train: surgery + LoRA + head + temperature scaling in one command
#    (Qwen3-0.6B on one 8 GB GPU: 7 min for 2k short tickets, ~1 h for 5.4k public records)
any2jev train --base Qwen/Qwen3-0.6B --data data/public/train.jsonl --val data/public/val.jsonl --out runs/qwen3-0.6b

# 3. evaluate: calibration, order sensitivity, isolation
any2jev eval runs/qwen3-0.6b --data data/public/test.jsonl

# 4. ask, or serve
any2jev ask runs/qwen3-0.6b --state "My payouts have failed 3 days in a row, fix this ASAP" \
    --choice "Which team? | billing, technical, sales" --noul "Is this urgent?" \
    --score "How frustrated? | calm, frustrated, furious"
any2jev serve runs/qwen3-0.6b --port 8009
With the official SDK, only base_url changes:
from typesafe_sdk import Choice, Noul, Score, TypeSafeClient

client = TypeSafeClient(api_key="local", base_url="http://127.0.0.1:8009", model="any2jev-latest")
r = client.system_one(
    state="Shoes arrived two weeks late and in the wrong size. Also I see two charges on my card.",
    questions={
        "department": Choice(instructions="Which team should handle this?",
                             criteria={"returns": "Exchanges, refunds, wrong or damaged items",
                                       "shipping": "Delivery status, delays, lost packages",
                                       "billing": "Charges, invoices, payment problems"}),
        "escalate": Noul(instructions="Does this need urgent human attention?"),
        "frustration": Score(instructions="How frustrated is the customer?", criteria=["Calm", "Frustrated", "Very angry"]),
    })
r.choices["department"].probabilities   # {'returns': 0.41, 'shipping': 0.17, 'billing': 0.42}
r.nouls["escalate"].noul                # 0.86
r.scores["frustration"].score           # 1.26
Or raw HTTP, identical to Jev's contract:
curl -s localhost:8009/v1/systemone -H 'content-type: application/json' -d @examples/request.jsonYour own data is one JSON object per line, exactly a /v1/systemone request plus a label per question
(format). What the model trains on is byte-identical to what the server feeds it.
Qwen3-0.6B, LoRA r=16, one epoch, one RTX 2060 SUPER (8 GB). Held-out test splits, temperature fitted on
validation. any2jev eval prints these tables; the JSON reports live in runs/ and scripts/fill_readme.py
writes them here. docs/benchmarks.md lists which script produced each number.
| question type | n | system | acc | NLL | Brier | ECE | AURC | cov@5% |
|---|---|---|---|---|---|---|---|---|
| overall | 1000 | prompted for JSON (generate) | 0.621 (0.1% format failures) | — | — | — | — | — |
| overall | 1000 | zero-shot logits (base) | 0.531 | 1.180 | 0.595 | 0.111 | 0.276 | 0.05 |
| overall | 1000 | zero-shot + temperature | 0.531 | 1.125 | 0.579 | 0.058 | 0.279 | 0.05 |
| overall | 1000 | any2jev | 0.796 | 0.506 | 0.284 | 0.027 | 0.062 | 0.57 |
| noul | 250 | prompted for JSON (generate) | 0.624 (0.0% format failures) | — | — | — | — | — |
| noul | 250 | zero-shot logits (base) | 0.644 | 0.693 | 0.479 | 0.166 | 0.216 | 0.12 |
| noul | 250 | zero-shot + temperature | 0.644 | 0.631 | 0.443 | 0.119 | 0.216 | 0.12 |
| noul | 250 | any2jev | 0.844 | 0.386 | 0.242 | 0.090 | 0.058 | 0.58 |
| choice | 500 | prompted for JSON (generate) | 0.764 (0.2% format failures) | — | — | — | — | — |
| choice | 500 | zero-shot logits (base) | 0.622 | 1.163 | 0.534 | 0.082 | 0.222 | 0.09 |
| choice | 500 | zero-shot + temperature | 0.622 | 1.118 | 0.532 | 0.087 | 0.226 | 0.09 |
| choice | 500 | any2jev | 0.906 | 0.272 | 0.142 | 0.020 | 0.018 | 0.88 |
| score | 250 | prompted for JSON (generate) | 0.332 (0.0% format failures) | — | — | — | — | — |
| score | 250 | zero-shot logits (base) | 0.236 | 1.700 | 0.835 | 0.145 | 0.710 | 0.00 |
| score | 250 | zero-shot + temperature | 0.236 | 1.634 | 0.811 | 0.092 | 0.705 | 0.00 |
| score | 250 | any2jev | 0.528 | 1.093 | 0.611 | 0.056 | 0.424 | 0.01 |
Option-order test on 23 Choice questions: argmax stable in 96% of them, mean max probability spread 0.088. Isolation check: skipped (no multi-question records in the checked subset). Temperature fitted on validation: T = 1.61. Test set: 1000 records, 1000 questions.
Synthetic support tickets (2,000 records, 4 question types, rule-based labels) are solved to accuracy 1.000 / ECE 0.001 in 7 minutes; that run is the smoke test, not the benchmark.
Steady state, single request, examples/bench_latency.py:
| base | dtype | device | input tokens | questions | p50 ms | p95 ms |
|---|---|---|---|---|---|---|
| Qwen/Qwen3-0.6B | float32 | cuda:0 | 116 | 3 | 41.8 | 53.2 |
| Qwen/Qwen3-0.6B | bfloat16 | cuda:0 | 116 | 3 | 61.6 | 64.2 |
| Qwen/Qwen3-0.6B | bfloat16 | cuda:0 | 353 | 12 | 133.4 | 136.8 |
| Qwen/Qwen3-0.6B | bfloat16 | cuda:0 | 361 | 3 | 132.8 | 133.7 |
The RTX 2060 SUPER (Turing) has no native bf16, so fp32 is the faster dtype there; on Ampere or newer bf16 wins. Latency grows with input tokens, not with the number of questions: 12 questions cost the same as 3 once the sequence length matches.
| base | architecture | mode | trained on | acc | ECE | train time | trainable params |
|---|---|---|---|---|---|---|---|
| Qwen/Qwen3-0.6B | attention-only | packed | public (1000 q) | 0.796 | 0.027 | 61 min | 10.6 M |
| Qwen/Qwen3.5-0.8B | hybrid (linear attention + attention) | rows | synthetic (594 q) | 0.997 | 0.003 | 26 min | 5.9 M |
The Qwen3.5 row is the synthetic smoke test, not a benchmark: it shows the hybrid (Gated DeltaNet) backbone goes
through the same surgery, training and serving path, with every question run as its own causal row because
linear-attention layers cannot take the block-causal mask. Rows mode costs about 6x the packed latency on this
GPU (259 ms for the 3-question example, without the fused kernels from flash-linear-attention).
Anything AutoModelForCausalLM loads should work. Delimiter reuse is built in for Qwen, Llama 3 and Gemma
tokenizers; other tokenizers get five new tokens. Rough VRAM for fp32 LoRA training with 384-token states:
0.6B → 8 GB, 1.7B → 16 GB (--dtype bf16 halves it). Verified a new base? Open a PR with its eval.json.
See docs/architecture.md. In short:
extract_backbone()keeps the decoder stack of a*ForCausalLMand discardslm_head.- Five delimiter tokens (
<state> <q> <opt> </opt> <decide>) are reused from the tokenizer's spare specials or added. User text is sanitised so it can never forge one. - State + questions are packed into one sequence under a block-causal mask; branch positions restart after the state. Hybrid (linear-attention) backbones fall back to one causal row per question.
- A pointer head scores
h(</opt>_k) · h(<decide>); softmax with a fitted temperature. - Noul, Choice and Score are the same primitive with different option lists. Choice
confidencefollows TypeSafe's public demo; Score confidence is an approximation (details).
- RLCR-style RL stage (
correct − (confidence − correct)²reward) on top of the supervised recipe - State-prefix KV cache in the server (exact, thanks to the block-causal mask)
- vLLM / SGLang backend for large bases; ONNX export for the small ones
- Encoder backbones (ModernBERT) through the same interface
- Pretrained adapters on the Hub for Qwen3 0.6B (public data, Snake)
- Adapters for Qwen3 1.7B / 4B and a Llama / Gemma base
Jev is TypeSafe AI's model; this project is independent and not affiliated. The packed-question architecture follows Archer Hume's Jev's Architecture Unmasked and the kev reproduction (Apache-2.0), which trains a fixed Qwen family; any2jev generalises the recipe into a converter for arbitrary bases with an evaluation and calibration toolkit. rlcd-lite informed the calibration objective. awesome-jev lists the wider ecosystem.
Apache-2.0.