Repository navigation
Conversation


 github-actions
Bot
added
enhancement

5ac87ab to
4972bde
Compare
4972bde to
2eafd11
Compare
github-actions
Bot
added
enhancement
2eafd11 to
270ea5c
Compare
github-actions
Bot
added
enhancement

This comment has been minimized.
This comment has been minimized.
github-actions
Bot
added
enhancement

| FROM session_record i | ||
| WHERE ($1::text = '' OR i.id > $1::uuid) | ||
| AND i.state = 'RUNTIME_STATE_FAILED' AND i.operation = 'RUNTIME_OPERATION_RESUME' | ||
| AND (($3 AND i.state = 'RUNTIME_STATE_READY' AND i.operation = 'RUNTIME_OPERATION_NONE') |
There was a problem hiding this comment.
Agreed. The scan needed one interval per 100 READY Sessions and spent one GetActor on each healthy runtime. As of 94026a0, each interval lists the Actors in the atespaces that hold a READY Session, in pages of 1,000, and reads only the CRASHED ones individually. Revert re-observes the Actor before it admits anything, and PostgreSQL paging now covers admitted recoveries only. On a dev fleet with about 505 READY Sessions and a 15s interval, a worker loss took 69–73s to recover before and 0.4–11s after. An idle controller went from 507 GetActor calls a minute to 6 ListActors calls (crash-detection.txt, substrate-rpcs-idle.txt):
before  READY=506  recovered 1m13.1s after the worker deletion (4.9 intervals)
after   READY=507  recovered 11s after the worker deletion (0.7 intervals)
idle 60s, interval 10s, READY=507:  before 507 GetActor   after 6 ListActors

|
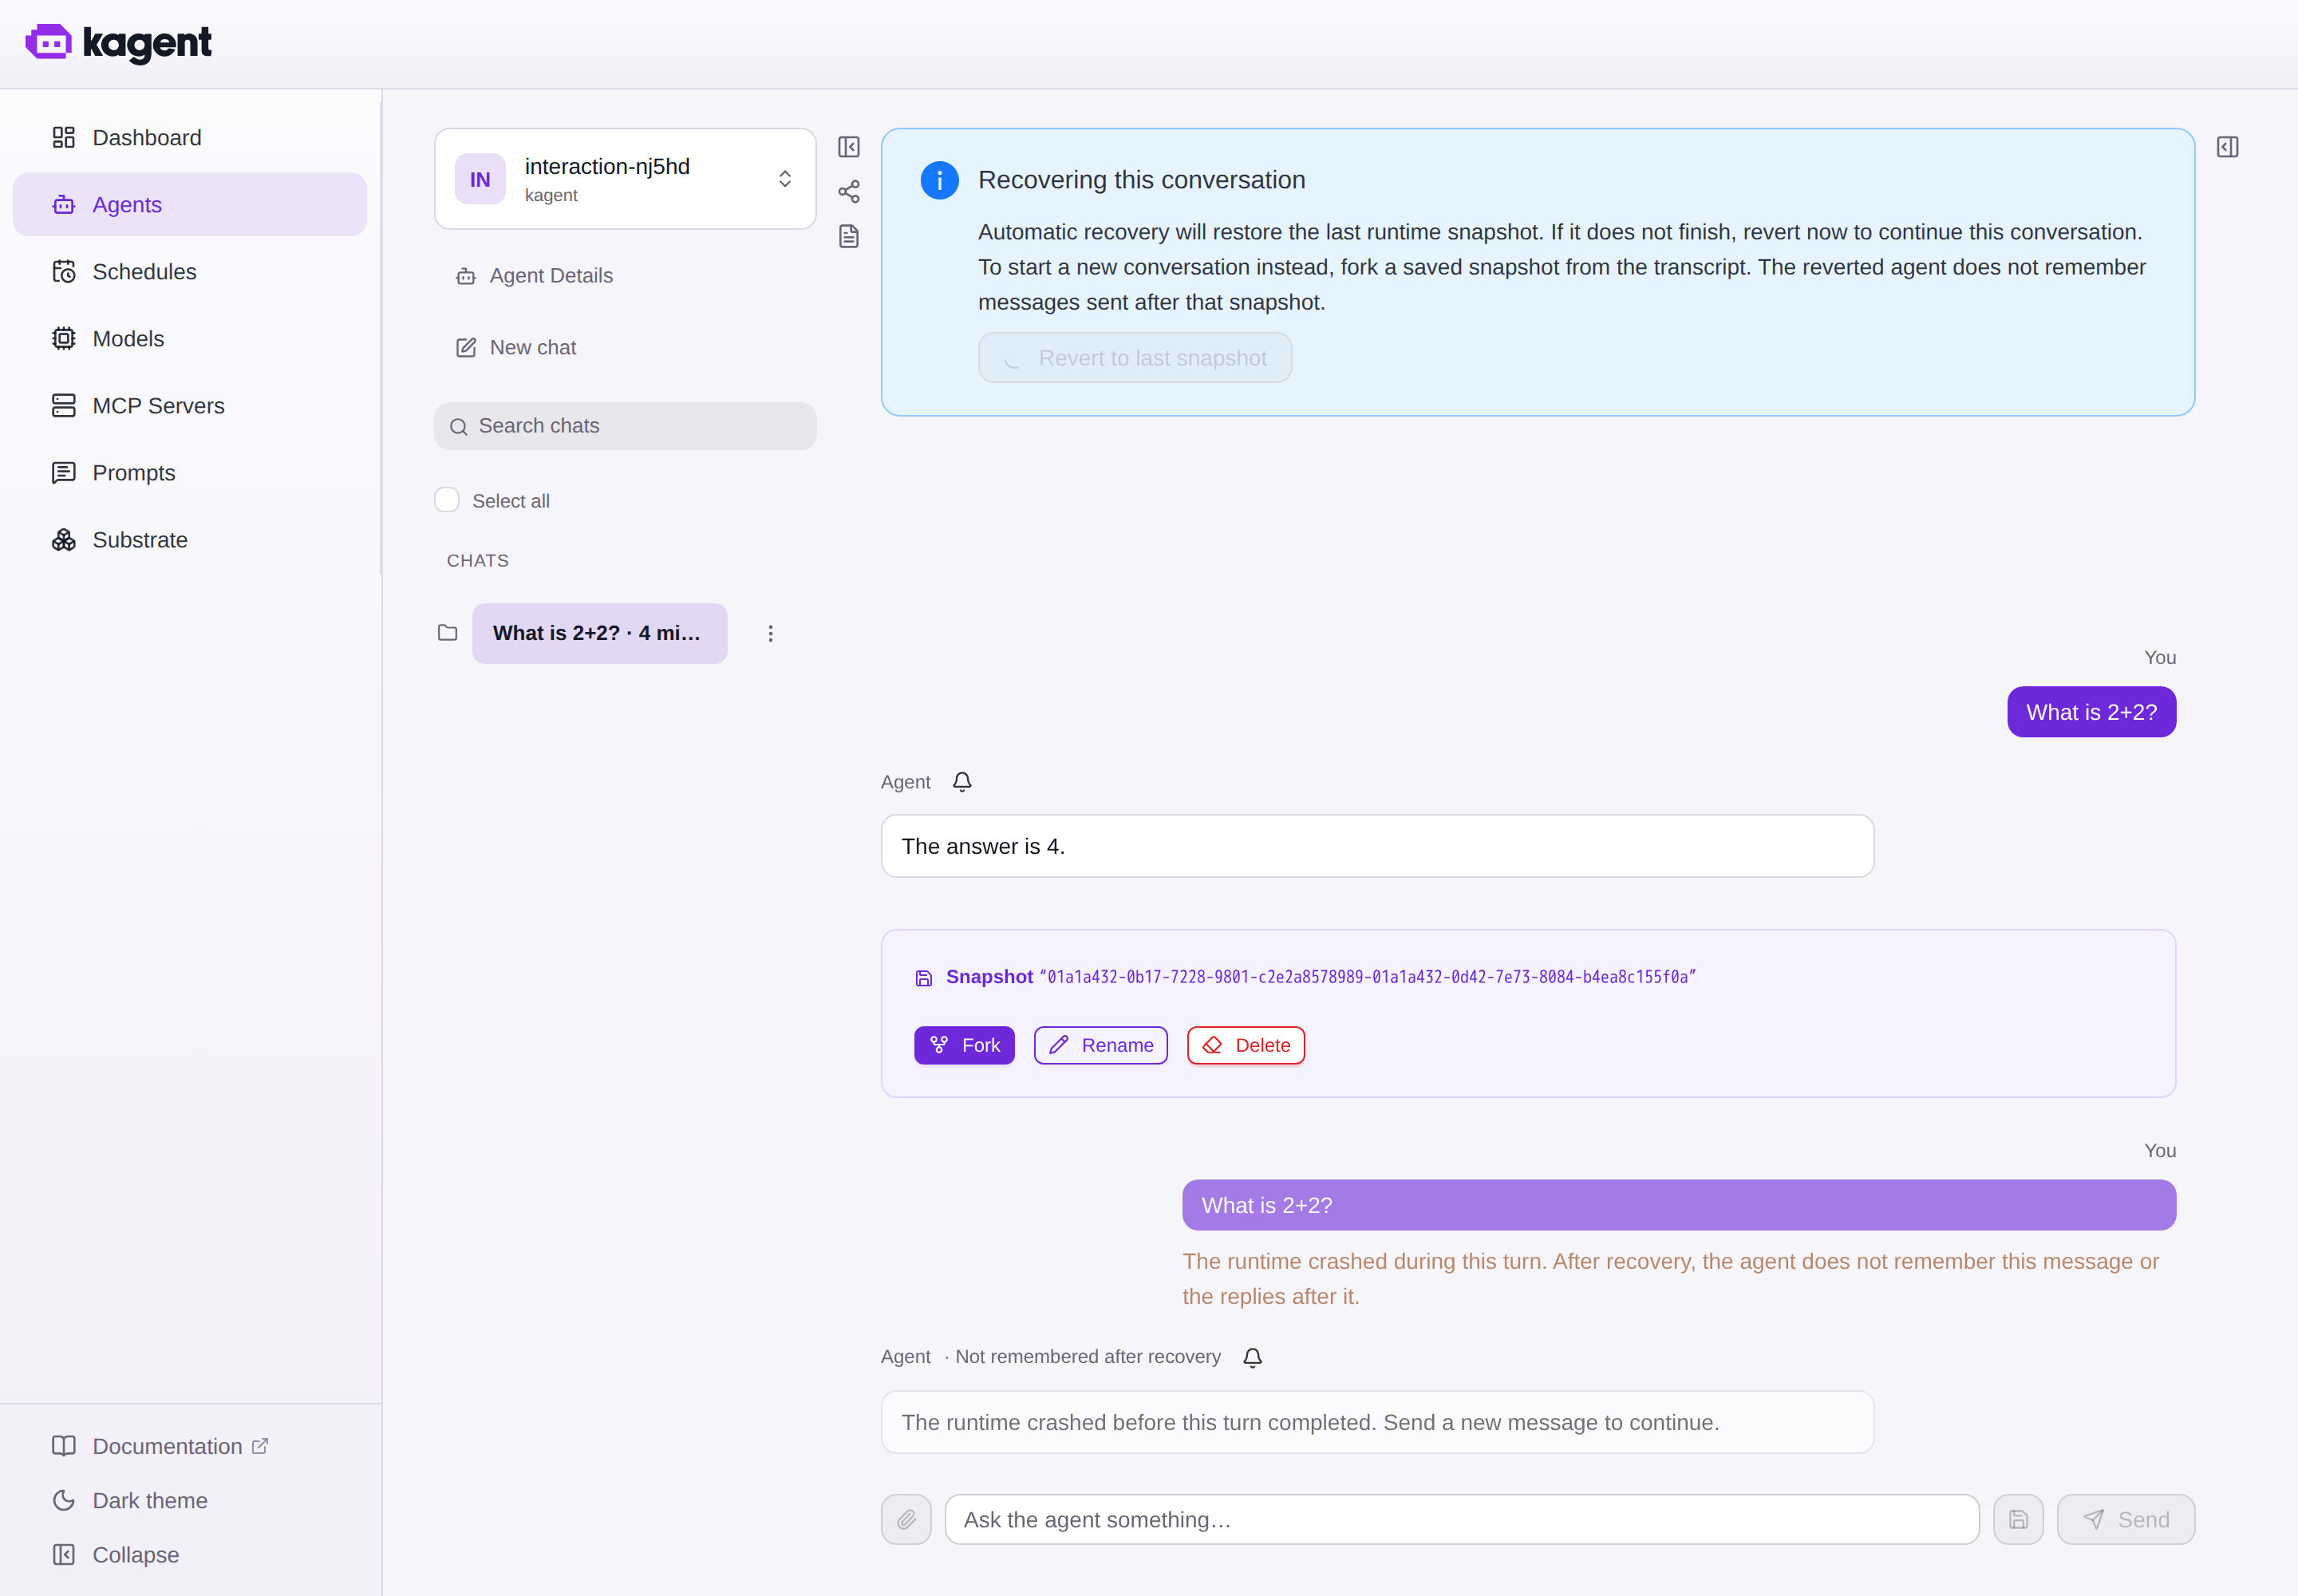
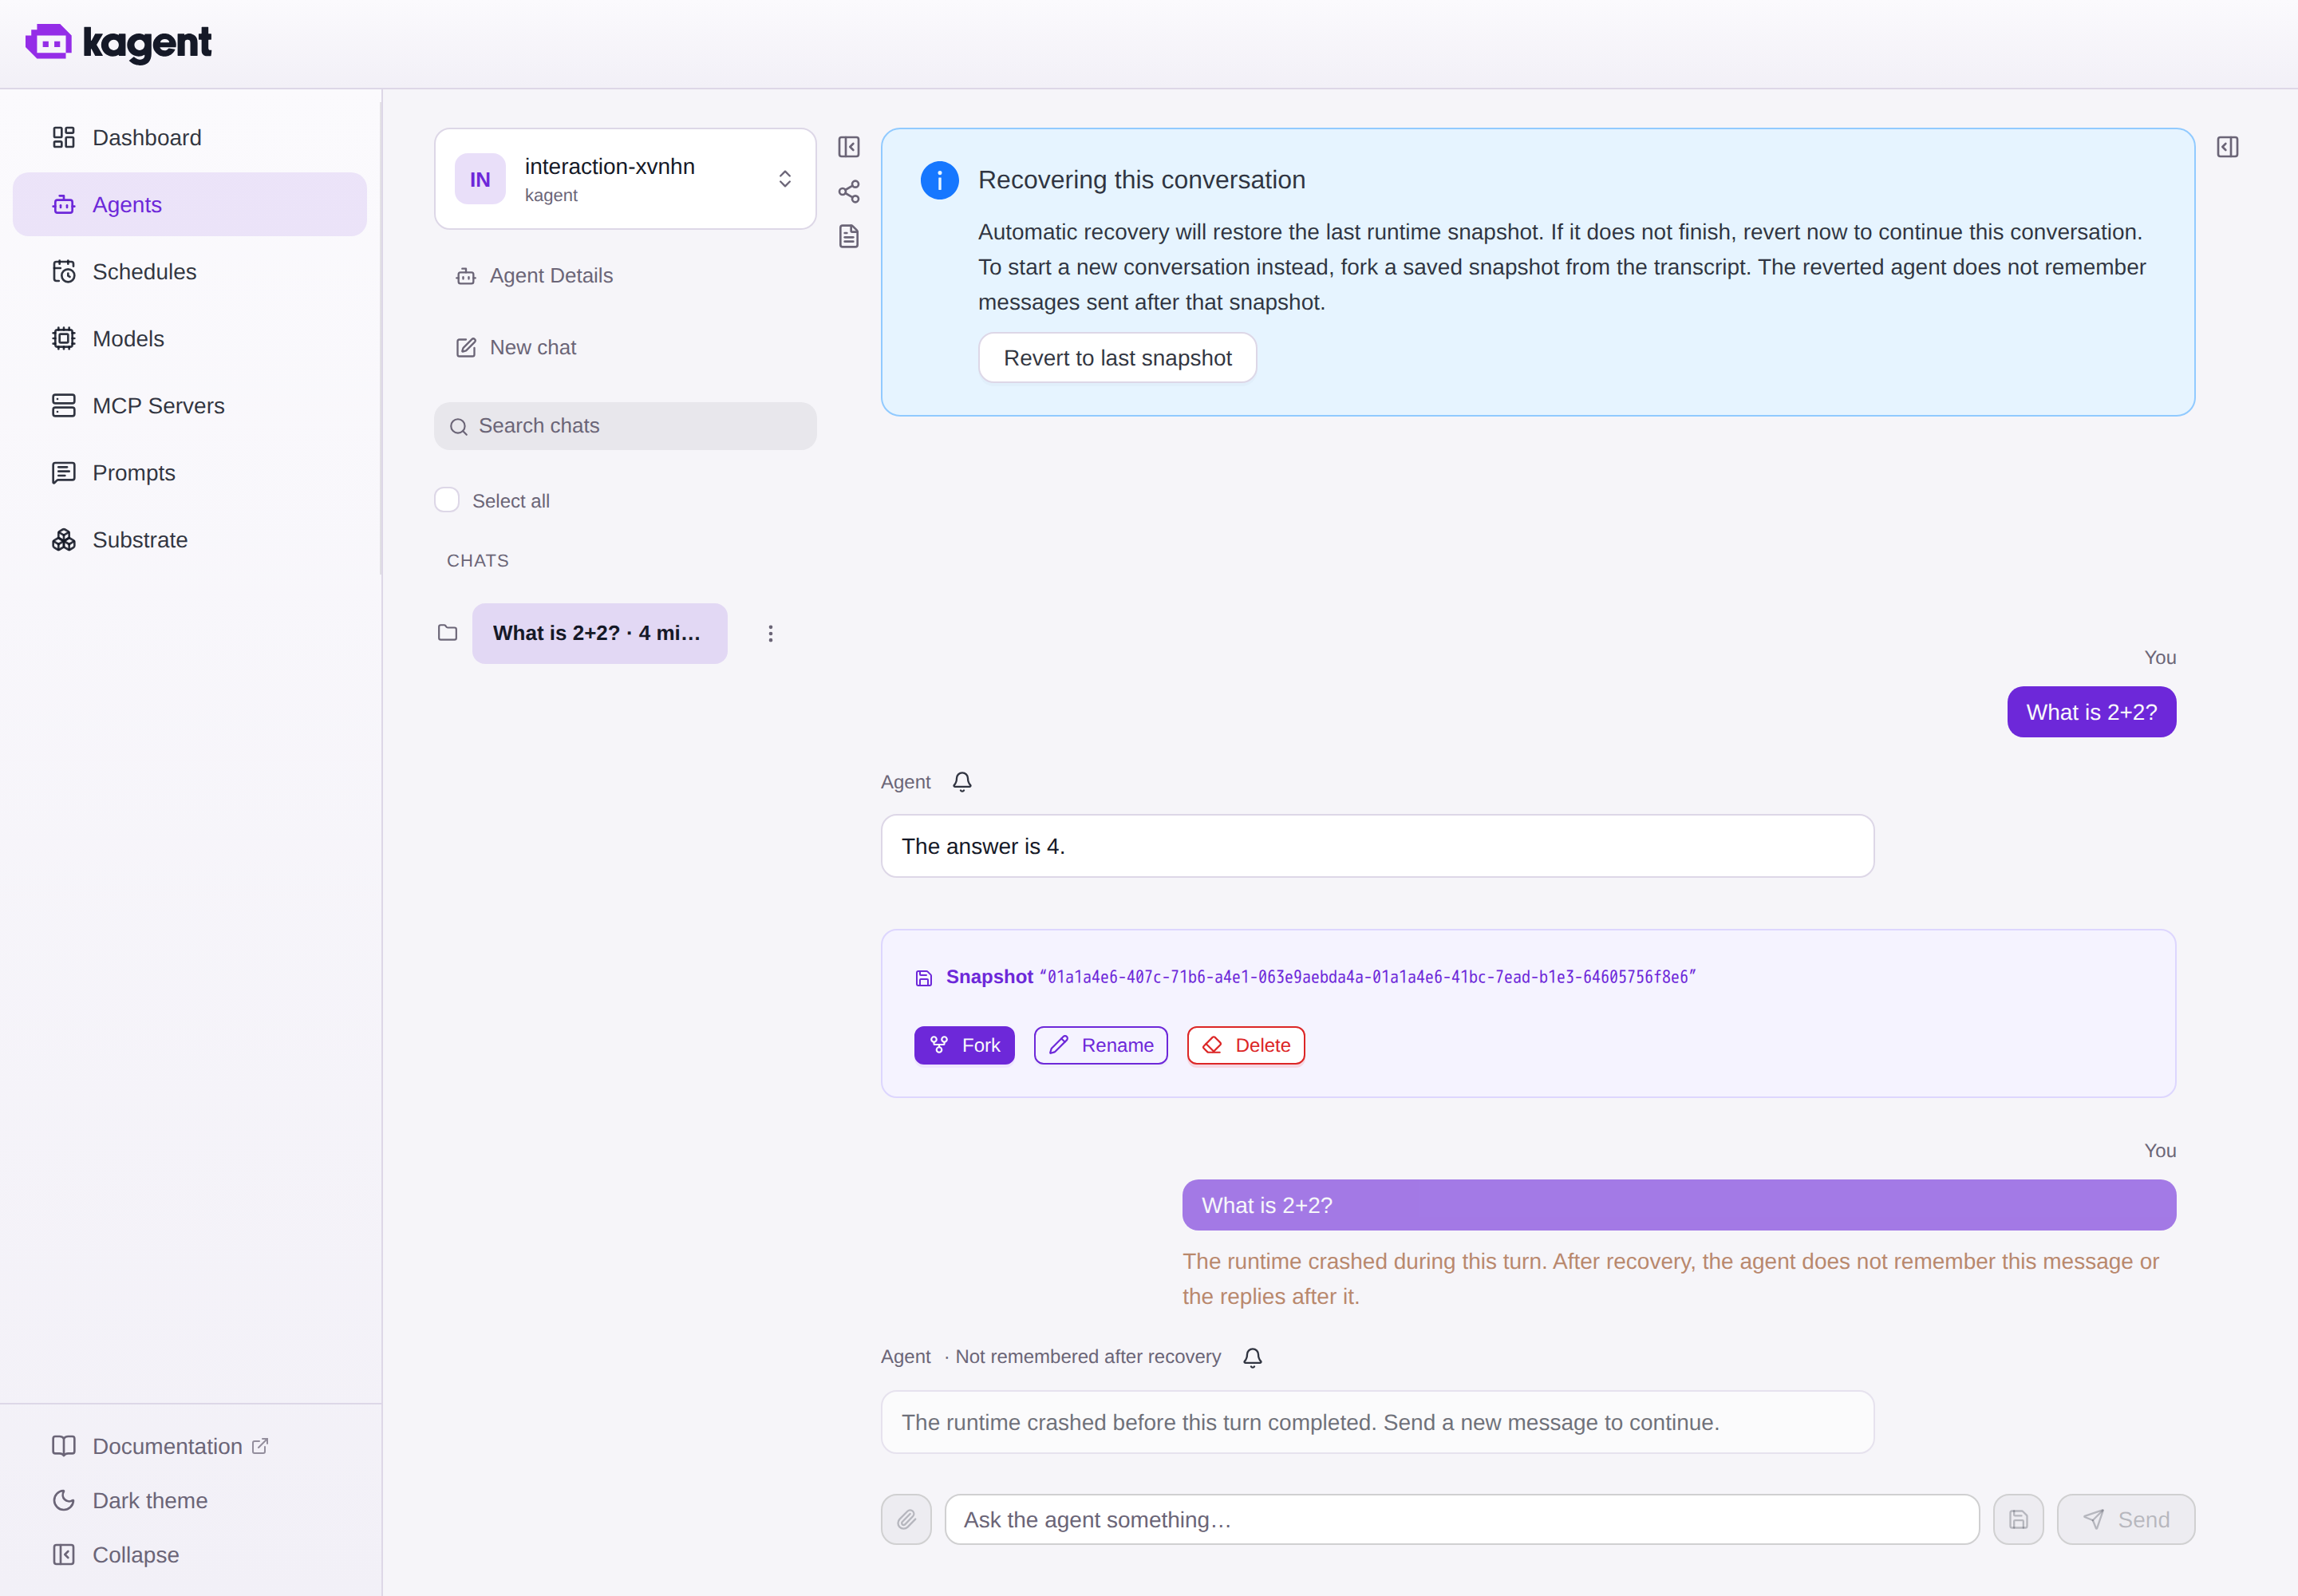
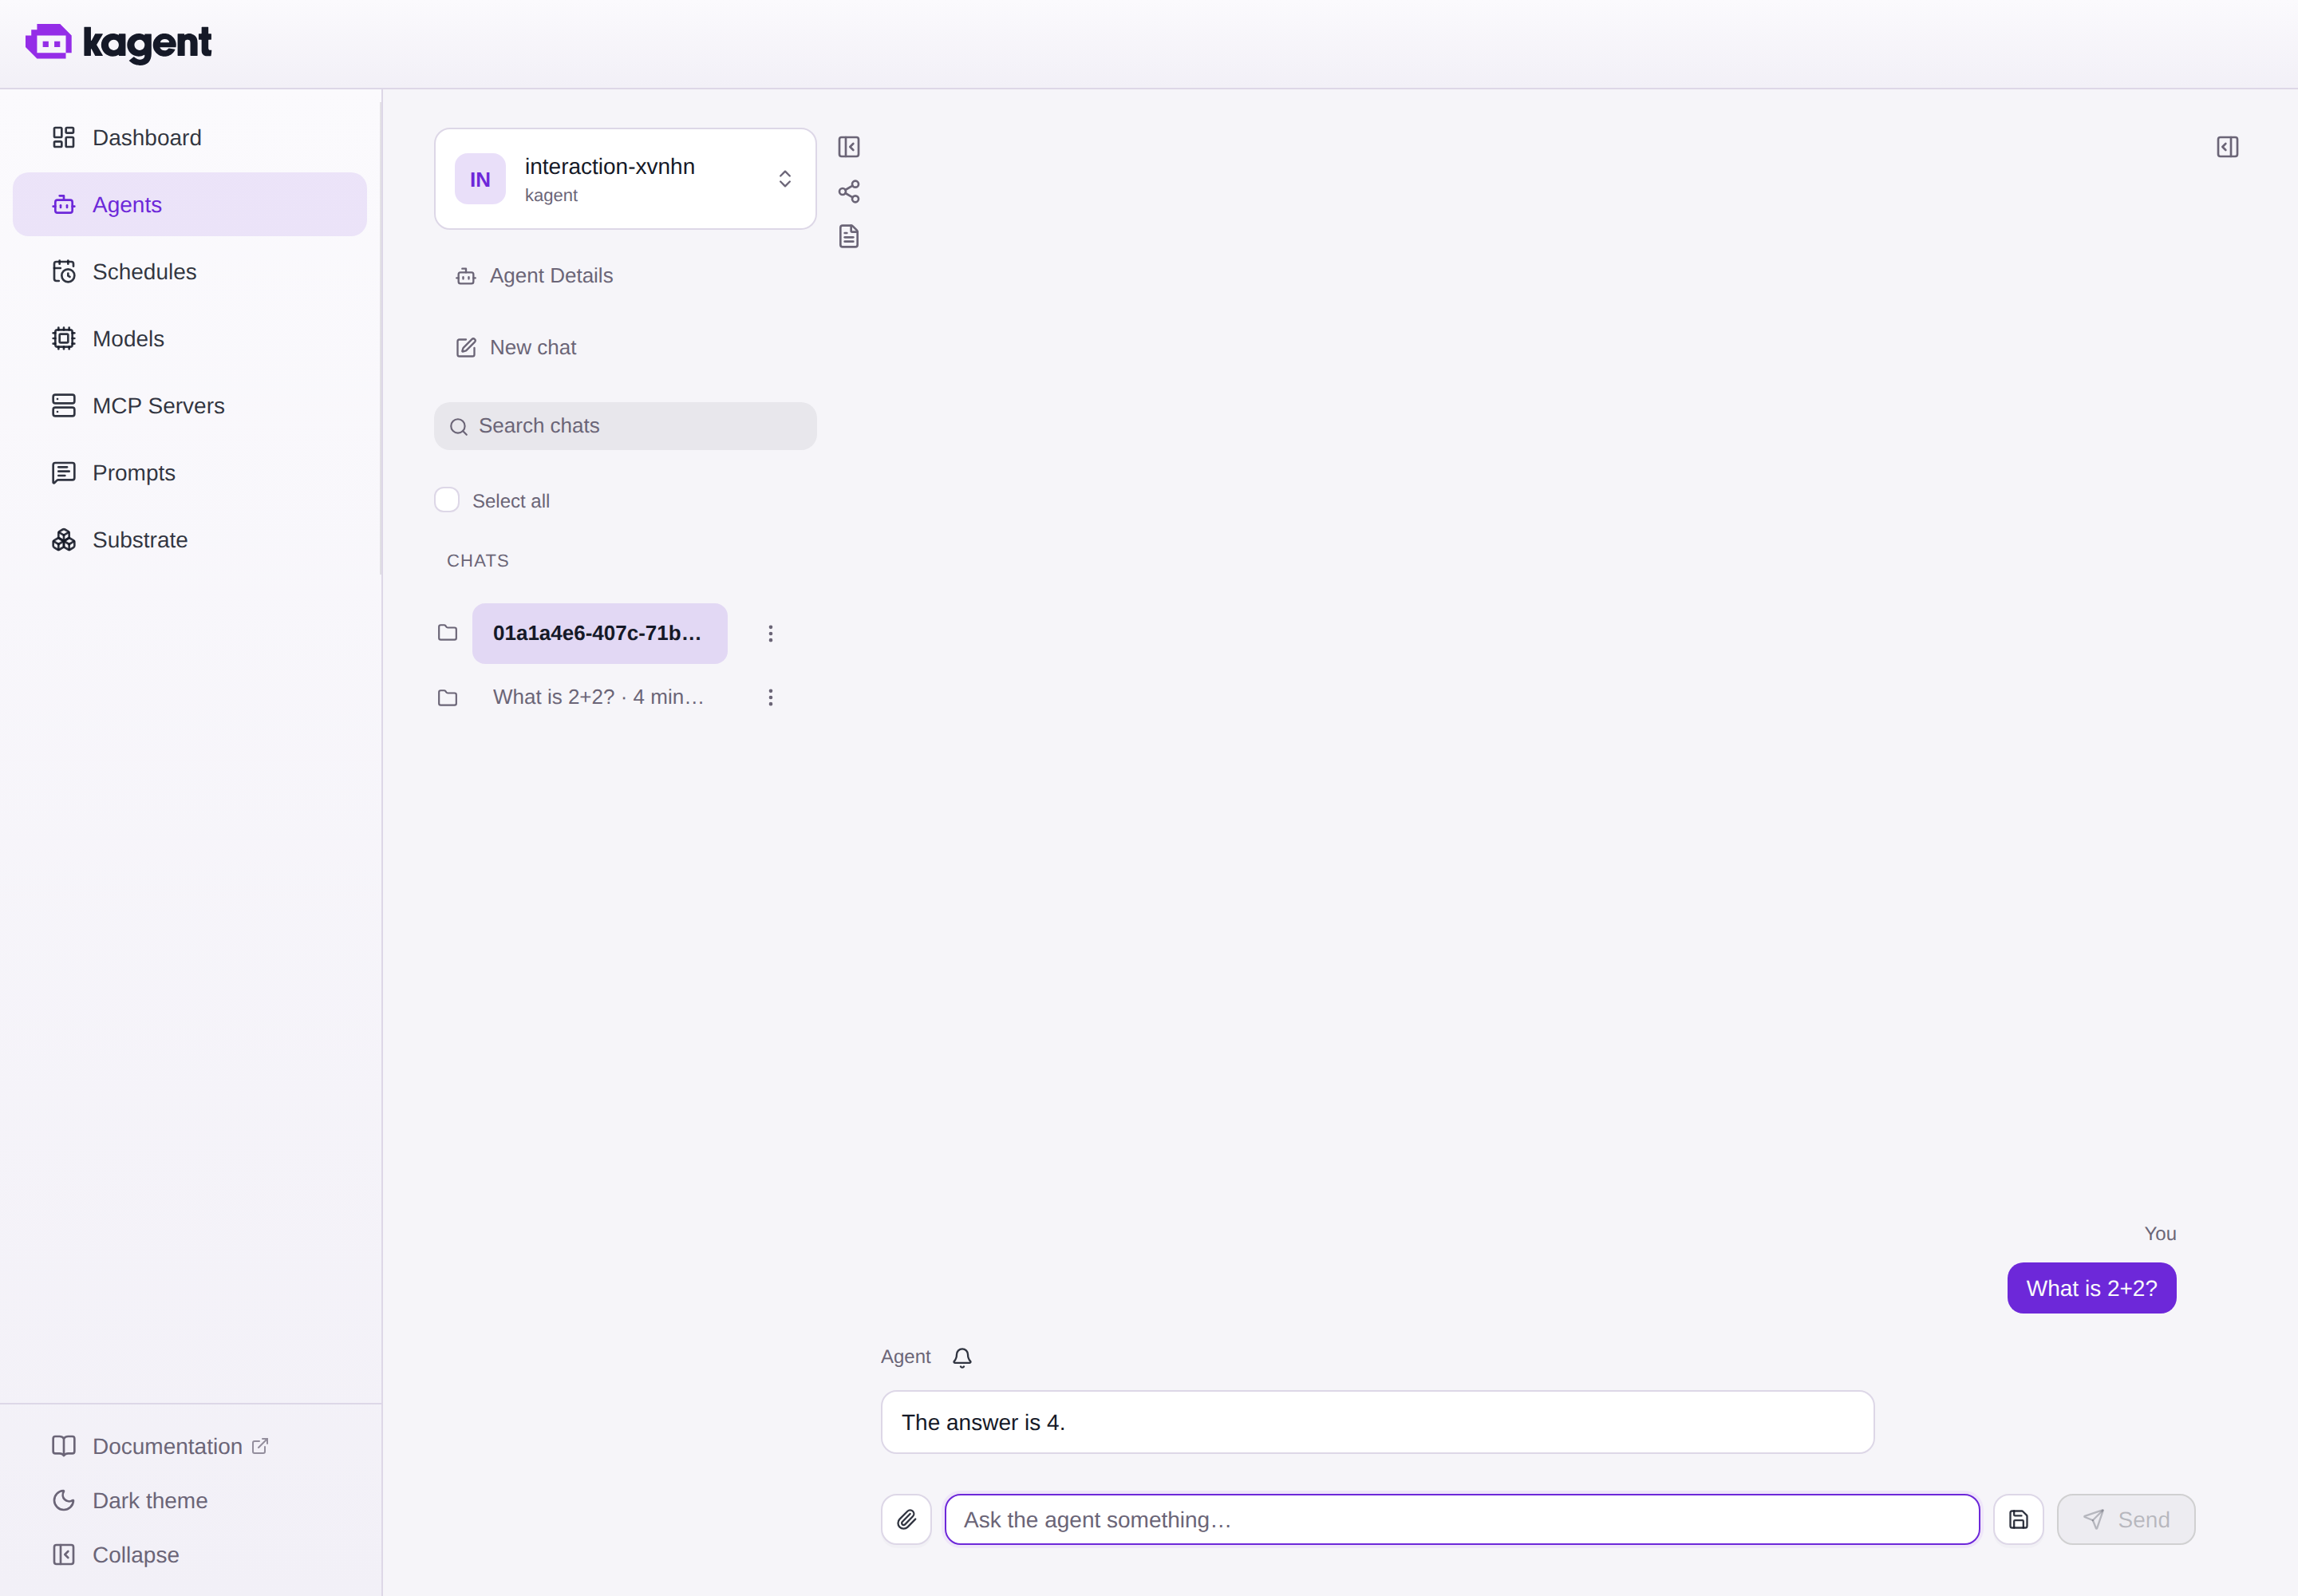
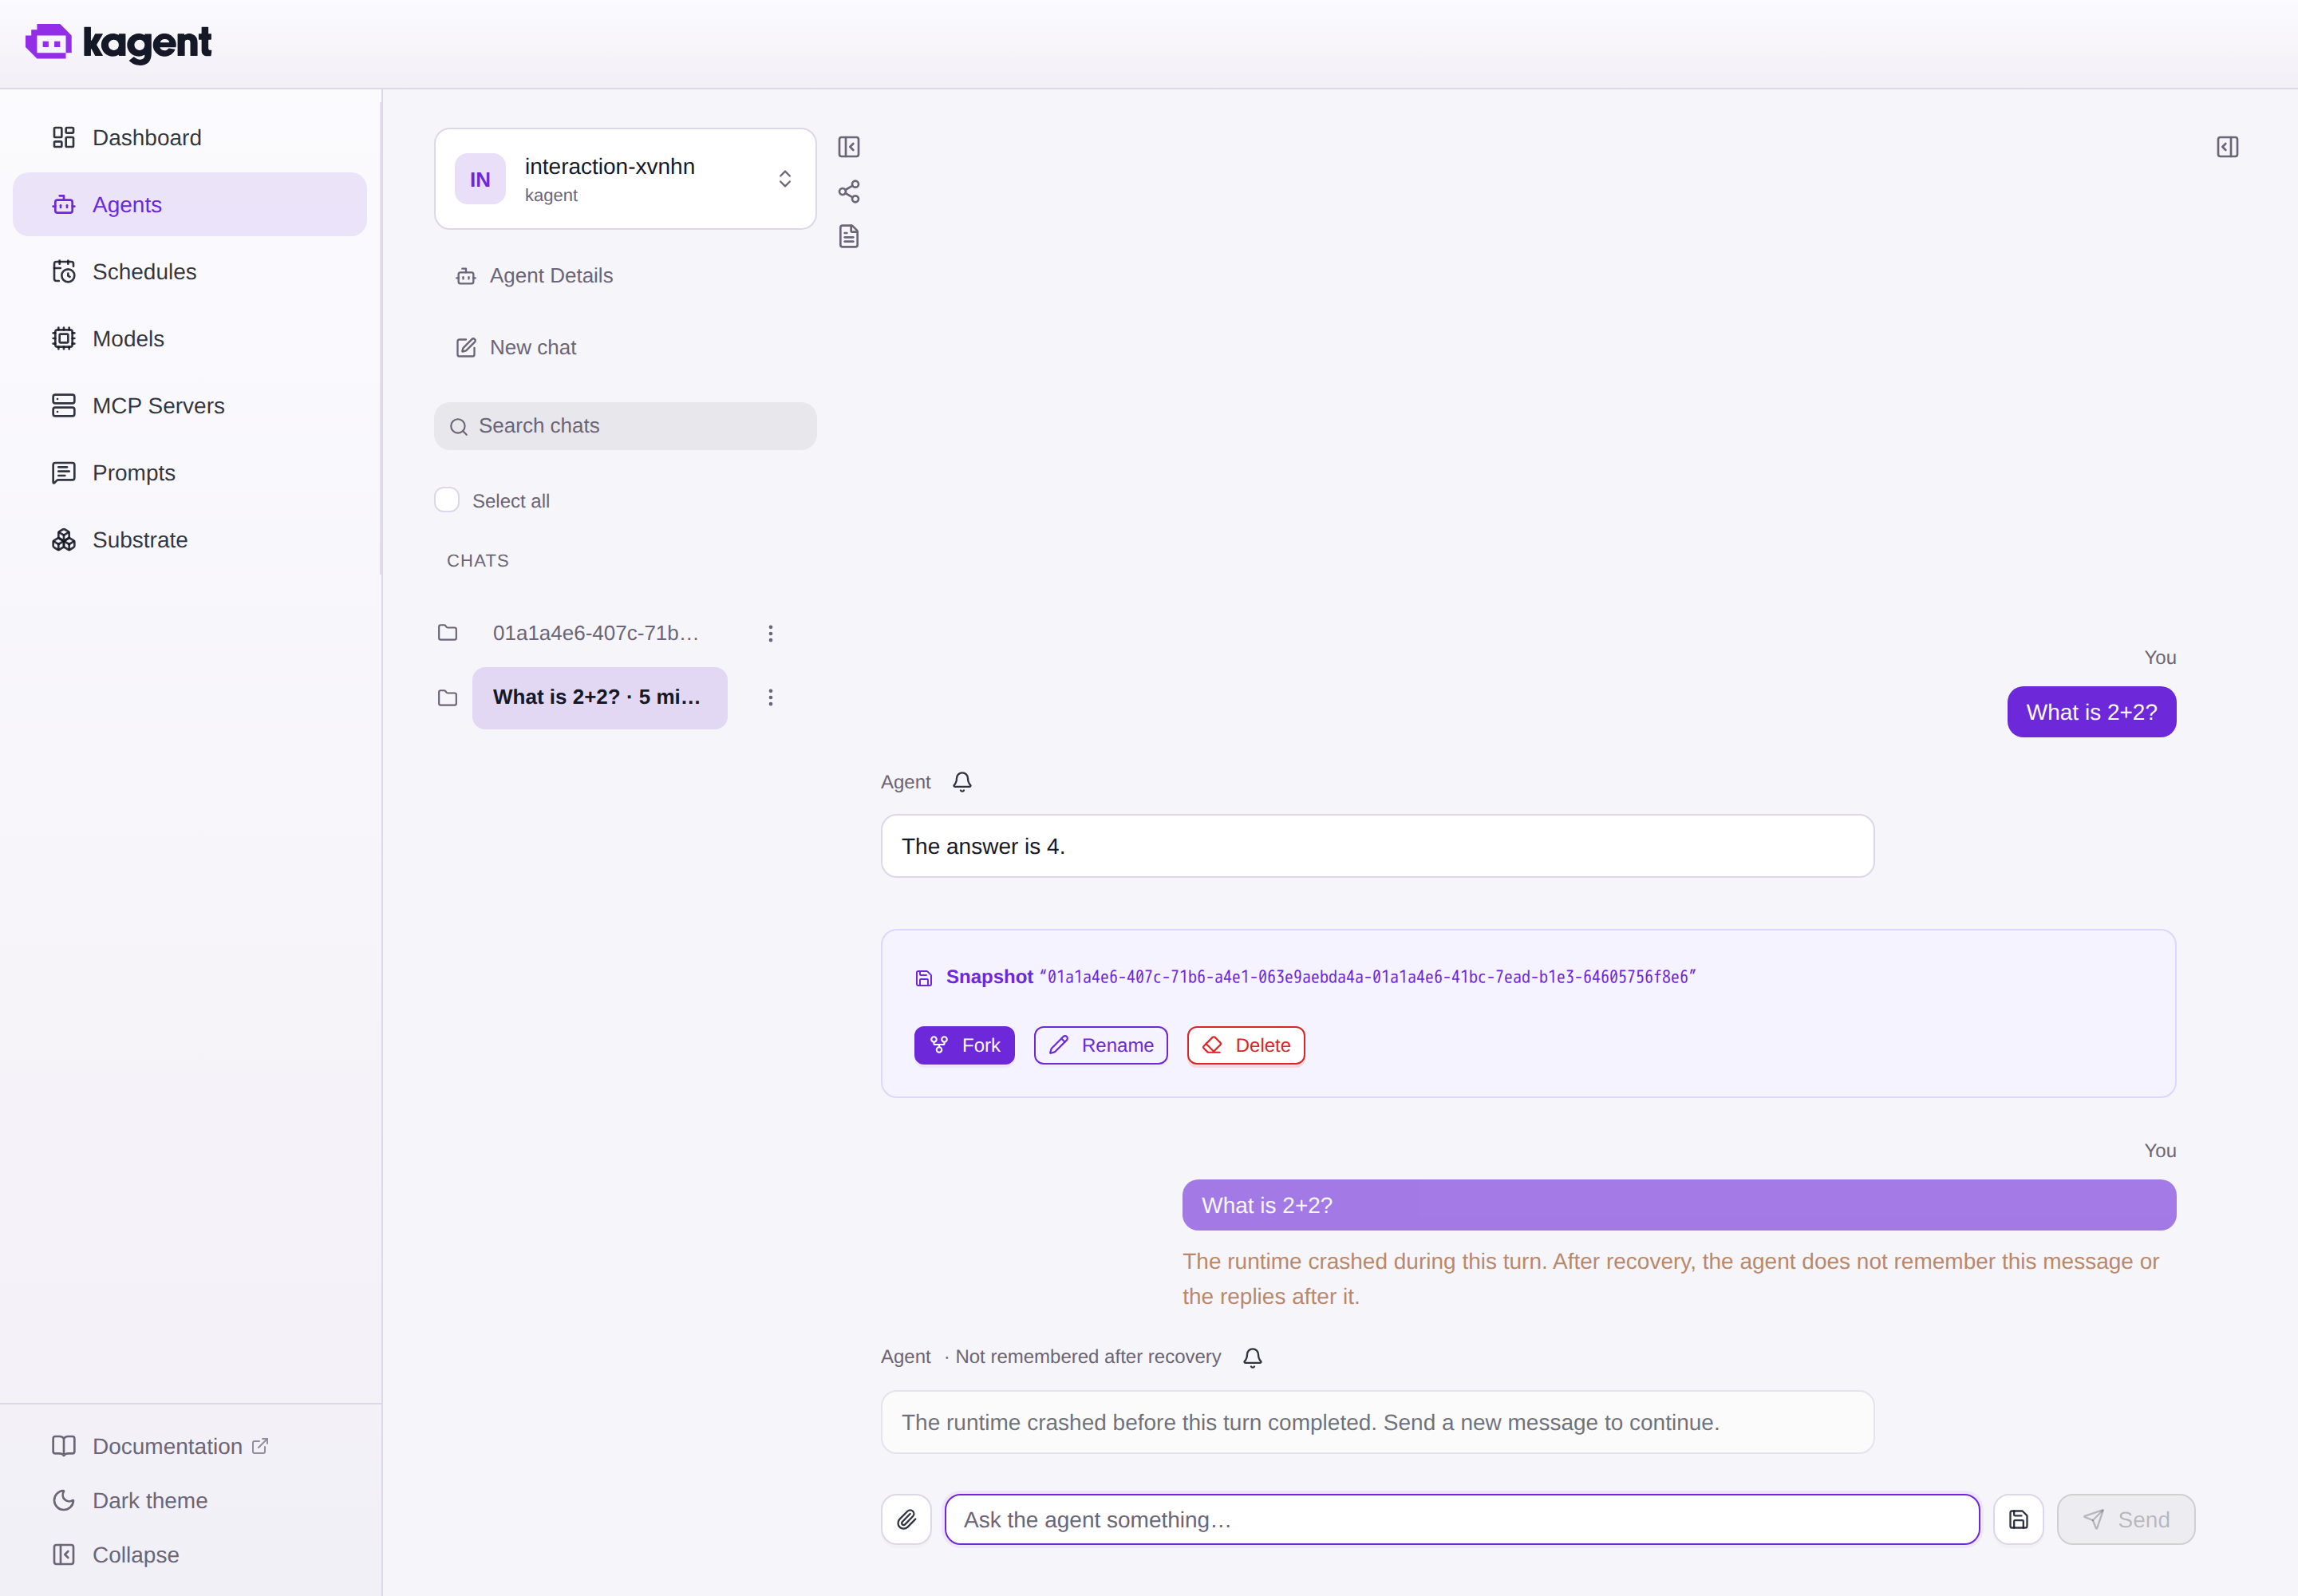
Review follow-up: a failed automatic recovery must still leave the user a way to revert or fork. The review thread that raised this is gone, so I'm answering here. Agreed, and my first fix (02bd7b6) only half closed this. It added Revert to the alert in automatic mode, but disabled the button while the Session's operation was RESUME. An admitted recovery keeps RESUME through every failed attempt, so after the first automatic attempt failed, Revert spun until a later attempt succeeded. 5ae5c00 disables it only while the page's own request is in flight. A click joins the admitted recovery. After merging #3398 (11f9abb, 40e3702), Fork lives on each saved snapshot's line in the transcript, which renders in automatic mode too, so there is one place to fork. On a dev fleet I held the automatic revert failing. Before, at 3fc96de: After, pending, forked, and reverted: |
749d4b4 to
8d4cff0
Compare
github-actions
Bot
added
enhancement

 codyhartsook
left a comment
codyhartsook
left a comment
There was a problem hiding this comment.
🤖 AI-assisted review.
A failed recovery can leave chat stuck with the flag on
On kind, I took atelet down while chat's send ran the recovery, and the Session stayed FAILED/REVERT. It was still stuck three minutes after atelet came back. After a reload, chat says the runtime "is being restored", but the composer is disabled. Unless I missed a path, the user has no way to recover from chat.
Today canSend (AgentChatPage.tsx:345) is state === "ready", so a recovering Session gets a disabled composer. I'd recommend also allowing a pending recovery, with alert copy that says to send a message:
const canSend = state === "ready" || instance.data?.operation === "revert";A running revert and a failed one look the same in the stored Session (FAILED/REVERT), and a send handles both. It rejoins a failed recovery (interactions.go:500), and while a revert runs it's refused as not accepted, so chat's existing resend lands once it finishes. I tried this on kind, and the next message restored the runtime and was answered.
What I checked
- Kind cluster at
9e26908withautomaticRecovery: true, chat driven in a browser. - Worker pod deleted mid-turn, then a send from chat with atelet down.
- The same run with a local patch that enables the composer during
revert.

 EItanya
left a comment
EItanya
left a comment
There was a problem hiding this comment.
🤖 AI-generated review. Comment left by Claude on behalf of @EItanya.
Thanks for working through all of these, the stored RuntimeLost state and dropping the Substrate read from GetSession make this a lot simpler. A few things now that recovery on send is behind automaticRecovery, inline.
| * Read from the stored Session alone. A pending crash recovery and a runtime that is | ||
| * gone are both FAILED, and only the operation and failure reason tell them apart. | ||
| */ | ||
| function notReadyCopy( |
There was a problem hiding this comment.
With the flag off, chat has no way to recover a crashed conversation
The Revert alert is gone, and send only recovers when automaticRecovery is on, which is off by default. So in a default install, a crashed conversation looks READY in chat, every send comes back KAGENT_SEND_NOT_ACCEPTED, the new retry loop runs for 30s, and then the user gets an error with no hint that the runtime crashed or what to do. That's the same place we were before this PR, plus 30s of retries.
Can we keep an explicit Revert in the UI for this case? E.g. when the 30s window runs out on KAGENT_SEND_NOT_ACCEPTED, show "the runtime may have crashed" with a Revert button that calls RevertSession. Revert returns a healthy Session unchanged, so it's safe to offer on a guess, and it's an explicit user action, so it fits the flag being off. With the flag on, the user wouldn't see it unless recovery itself keeps failing.
There was a problem hiding this comment.
Done. When the retry window runs out on KAGENT_SEND_NOT_ACCEPTED, the turn error now says the runtime may have crashed and offers Recover (calls RevertSession) next to Retry. A refusal that arrives after the first frame is not tagged, because that message was accepted. Recover also records RuntimeLost, and the page then shows the lost-runtime alert. (ed0fa109)
This missed the mid-turn crash case; see my correction below.
There was a problem hiding this comment.
Correction to my reply above: it didn't cover the #394 case. I reproduced it on kind with the flag off. After a worker is deleted mid-turn, the next send isn't KAGENT_SEND_NOT_ACCEPTED. It's an outright FailedPrecondition: resource conflict, because the crashed turn stays open, and the Session still reads READY. Chat showed only Retry, which can't succeed.
456201b6 also offers Recover for A2A refusals that arrive before the first frame. On the same cluster, the refused send now offers Recover. Recover restored the runtime, and the next message was answered. Recover during a healthy running turn left it running, and the turn completed. The branch is also rebased onto main.
Screenshots and logs are in this gist: section 1 is before the fix, section 3 is after it, and section 4 is the healthy running turn.
| // crashed Actor cannot be resumed, so the refusal would repeat on every retry; | ||
| // reverting it first lets the caller's retry reach the restored runtime. | ||
| func (s *InteractionService) RecoverRejectedSend(ctx context.Context, agent types.NamespacedName, message *a2atype.Message) error { | ||
| if !s.automaticRecovery { |
There was a problem hiding this comment.
With the flag off, a lost runtime is never recorded from a send
This returns ErrSendNotAccepted before looking at anything when the flag is off, so a send to a missing or replaced Actor stays retryable forever and the Session stays READY/NONE. Only an explicit RevertSession records RuntimeLost. Recording the loss doesn't revert or discard anything, so I'm not sure it needs to be behind the flag. @iplay88keys, would you be ok with the rejected-send path recording RuntimeLost regardless of the flag, and only the revert being gated?

There was a problem hiding this comment.
For #3395, we had discussed that rollback wouldn't be possible if RevertSession RPC had been called, since the prior version doesn't know the REVERT operation. Keeping automatic recovery generally behind a flag keeps that true. So we have two options that still are rollback safe:
- Keep it behind the flag. With the flag off, sends behave as they did before this PR. A Revert action in chat then records
RuntimeLostwhen sends keep failing. - Record
RuntimeLostregardless of the flag. A send to a lost runtime then fails fast with a clear error. This stays rollback safe becauseFAILEDandNOINEalready exist in every 1.0 release candidate. However, it must only record the loss and never admit a recovery. This also needs the same update access asRevertSession. Otherwise a caller who can only send could end a Session.
There was a problem hiding this comment.
I went with option 1. Sends keep their pre-PR behaviour with the flag off. Chat's Recover action calls RevertSession, which records RuntimeLost through the existing update-access check, so the send path never records a loss or admits a recovery. (ed0fa109)
| * How long a send keeps re-sending a message the gateway proved it did not accept. | ||
| * The window bounds the retries, not how long an accepted turn may run. | ||
| */ | ||
| const UNACCEPTED_SEND_WINDOW_MS = 30_000; |
There was a problem hiding this comment.
With the gateway's retryAfterMs: 100, this window is up to ~300 sends per message, and each one goes through dispatch to the runtime (and with the flag on, a GetActor). That's fine for the busy-dispatch case that clears quickly, but for a crashed runtime with the flag off it's the whole window. Can we back off between retries, e.g. double from retryAfterMs up to a few seconds?
There was a problem hiding this comment.
Done. Waits now start at retryAfterMs and double up to 2s. A runtime that stays down costs 19 sends per 30s window, down from about 300. A larger retryAfterMs from the server still wins. (ed0fa109)
| generation *database.SessionGeneration | ||
| actor *ateapipb.Actor | ||
| // lost replaces actor with why the recorded Actor cannot be recovered. | ||
| lost string |
There was a problem hiding this comment.
lost sits next to actor with a comment saying one replaces the other, so a caller can build an observation with both, or with neither. Could observeCrash return the loss separately, e.g. a typed actorLostError{reason} that Revert checks with errors.As, so the observation only ever carries an Actor?
Small related one: lifecycleIdle is now defined in both database and service/session with the same body; can the session package use the database one?
There was a problem hiding this comment.
Done. observeCrash now returns *actorLostError{operationID, reason}, and Revert checks it with errors.AsType, so a crashObservation always carries an Actor. lifecycleIdle is now database.LifecycleIdle, and the session package uses it. (ed0fa109)

| recoveryInterval: 60s | ||
| sessions: | ||
| # Recover crashed runtimes when a client sends another message. | ||
| automaticRecovery: false |
There was a problem hiding this comment.
🤖 Written with AI, raised by me.
@EItanya, this raises a question about feature flags as config keys in general.
The chart copies config into controller.yaml, so every key in values.yaml renders for every install. v1.0.0 rejects unknown config fields. So kubectl rollout undo or an image-only rollback to v1.0.0 would crash-loop here, even if the flag was never enabled. Each new flag with a default in values.yaml repeats this.
Two options:
- Keep default-off flags out of
values.yaml, or add them only as a comment. The proto default keeps them off, and a default install renders the same config as before. - Let the config decoder accept unknown fields and log them. This only helps rollbacks to releases that include the change. It also stops the decoder from catching typos.
What do you think?
There was a problem hiding this comment.
For this PR I took option 1. automaticRecovery is only a comment in values.yaml, so a default install renders the same controller.yaml as before. A helm-unittest asserts the default render omits the key, and a second test asserts it renders when set. The CI fleet still enables it explicitly. The general decoder question is still open for you two. (ed0fa109)
On a fresh install from this branch, the rendered controller.yaml has no automaticRecovery key (gist, Setup).
|
@codyhartsook Thanks for reproducing it. I added a Recover button to the recovering alert in place of enabling the composer. Recover calls Evidence from kind with the flag off is in this gist, section 2. With your one-line change applied temporarily, the send to the FAILED/REVERT Session was refused with |
github-actions
Bot
added
enhancement
This comment has been minimized.
This comment has been minimized.
f46cff7 to
b979f85
Compare


Add `Session.recovery` with `SessionRecovery.failed_messages`, a list of
`SessionMessageReference` task and message identities. When admission
reverts a crashed runtime, it records each user input after the
retained snapshot boundary, including accepted inputs not yet
published, in the same transaction that fails the interrupted turn.

The boundary is the newest history event tagged with the snapshot the
Actor reverts to. Without a snapshot every input is discarded. If no
event records the snapshot, the boundary is unknown and no new
annotations are added. One CTE resolves the boundary and reads the
discarded messages. Each message's identity is still validated in Go,
and a malformed event rejects the admission.

Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
`GetSession` now reports `recovery.needed`. It is true for an admitted
recovery, false for a Session with a lifecycle operation in flight,
and, for an idle Session, the result of the same `observeCrash` check
`RevertSession` admits by. Chat can therefore never offer a revert the
API would refuse. An observation costs one fence read and one Substrate
call. If the observation fails, needed is left unset rather than
failing the read, so an outage cannot hide history.

`GetSession` is the only read that observes Substrate. `Get`, which MCP
calls before every invoke, serves the stored record without observing.
`ListSessions`, rename, revert, and delete omit `recovery`, so a list
does not carry every conversation's annotations.

`Service.Observe` always has a workflow; transport tests use a stand-in
that reports stored annotations instead of a nil workflow.

Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
The API client now maps `GetSession`'s `recovery` (needed and the
discarded message references) into the conversation domain type, and
adds a `revert` operation that calls `RevertSession`. The mock
transport passes recovery through. It refuses a revert with
FAILED_PRECONDITION, because fixtures have no crashed runtime that
could authorize one.

Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
When `GetSession` reports that a conversation's runtime needs recovery,
chat shows an alert offering to revert it to its last snapshot. The
existing fork action stays available for a saved checkpoint. An idle
conversation re-reads the Session on the existing four-second live
refresh while the tab is visible, so a crash after a turn settles is
found without keeping the one-second lifecycle poll running. The shared
page does the same.

Inputs that the restored runtime does not remember are marked "Not
remembered after recovery" across their whole turn, and the public
transcript is kept. Forking a crashed conversation is left to the
checkpoint lines.

Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
TestMCPToolApproval and TestSessionAskUserSurvivesSuspension wait for the
Actor to suspend, then send the reply once. Waking the Actor can fail before
the runtime accepts the reply. In a gVisor run, the restored runtime's
TaskStore dial to the controller timed out, so the gateway revoked the dispatch
and answered KAGENT_SEND_NOT_ACCEPTED. The test treated that retryable answer
as a failure.

Both resumes now go through sendMessageWithRetry, which every other send in
the suite already uses. The server returns this error only after proving the
input was not persisted, and a repeated message ID returns the accepted task,
so the retry cannot duplicate the reply.

Verified with go vet on the e2e package; the suite runs in CI.

Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
The base branch now returns the Session from RevertSession when it is
READY and its recorded Actor is SUSPENDED, so a retry after a lost
revert response succeeds. TestSessionRecoveryObservation still expected
KAGENT_SESSION_RUNTIME_NOT_CRASHED for its healthy case, whose Actor is
suspended.

The healthy case now expects the unchanged Session, and a running case
keeps the NOT_CRASHED refusal covered. Every case asserts that only a
confirmed crash reaches RevertActor.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
RevertSession now returns the Session for a runtime that is not
crashed, so chat no longer needs the NOT_CRASHED re-read.

GetSession reports recovery as `optional bool recovery_needed` instead
of a SessionRecovery message. The discarded-message annotations
(failed_messages) are removed: the admission CTE that recorded them,
the transcript marking, the shared page's Session refresh, and
withoutRecovery, which existed only because the annotations were stored
and grew with each revert. Showing users what a revert lost is a
separate follow-up.

Revert also stays usable while an earlier attempt's recovery is still
admitted. The alert disables the button only while this page's own
request is in flight (isReverting), which is separate from isRecovering.
This came in with the automatic-recovery commit, which is no longer in
this history.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Remove comments added for recovery observation and the chat Revert flow
that narrate the code, restate names, repeat assertions, or describe
earlier behavior. Keep the ordering, polling, and retry rationale,
shortened.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
… guard

- The CheckpointDivider fork check fixes forking from non-READY
  checkpoints, which predates crash recovery, so it is not part of this
  PR.
- The revert double-click ref is unnecessary: a second RevertSession
  joins the same REVERT or returns the Session.
- refreshConversation had one caller, so the live refresh inlines
  Promise.allSettled.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Substrate cannot resume a crashed Actor, so an A2A send to one fails
before the runtime accepts it. The gateway revokes the dispatch and
answers KAGENT_SEND_NOT_ACCEPTED, and every retry failed the same way.

When the gateway proves a failed send was not accepted, it now runs the
Session's Revert before answering. A healthy runtime returns at once. A
crashed one is reverted in place, so the client's ordinary retry
reaches the restored runtime. A send to a Session with recovery already
admitted joins that recovery instead of being refused. The revert uses
the authorization the send already checked and continues if the caller
disconnects. A missing or replaced Actor answers the send with a
non-retryable error rather than the retry signal.

No background work runs: recovery starts only from a client request.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Address review feedback on crash recovery:

- Drop Session.recovery_needed, Service.Observe, and
  ActorWorkflow.RecoveryNeeded. No Session read calls Substrate. Chat
  sends normally and retries KAGENT_SEND_NOT_ACCEPTED with the same
  message ID; it shows a pending recovery and a lost runtime from the
  stored Session state.
- Record a missing, replaced, or retemplated Actor as FAILED/NONE with
  failure reason RuntimeLost, in one transaction guarded by the observed
  operation ID. Open tasks fail and a pending dispatch is cleared. Later
  sends and reverts fail from PostgreSQL without asking Substrate.
- Recover through Service.Revert so a send needs update access to
  revert, as RevertSession does.
- Return Session errors from RecoverRejectedSend instead of mapping them
  to KAGENT_SEND_NOT_ACCEPTED.
- A crash during a turn leaves the turn active, which refuses every
  send. A send refused for active work now runs Revert once and retries
  its reservation, so a crashed runtime is restored and a busy healthy
  one refuses the send as before.
- The crash e2e recovers through a send instead of RevertSession.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Add sessions.automaticRecovery, disabled by default. Gate all three send recovery paths while keeping explicit revert, migrations, and persistence unconditional. Enable recovery in the CI fleet and cover disabled refusals and config rendering. Gateway, config, PostgreSQL Session, gRPC, scheduled-run, protobuf, and lint checks pass.

Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
…dered

Chat offers Recover, which calls RevertSession, when a recovery is pending and
when sends stay refused as not accepted after the retry window. It works with
automatic recovery off, retries a failed recovery, and records a lost runtime.
Re-sends now back off from retryAfterMs to two seconds. Only refusals before
the first frame are tagged as not accepted.

Keep sessions.automaticRecovery out of the rendered chart values, so a default
install stays readable by releases that predate it; helm-unittest guards that.

Report a lost Actor as a typed actorLostError instead of a crashObservation
field, and share database.LifecycleIdle.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
Vitest's default of one worker per core less one oversubscribed an 18-core
machine: each worker rendering a page keeps about 1.5 cores busy, so heavy
page tests stretched from about one second to 5-9 s and hit the 5 s timeout
or the 1 s findBy, a different few each run. Cap workers at eight, and one
less than the cores below that, so 4-vCPU CI runners keep their three.
Three consecutive full runs pass, 846/846, at load 11-13.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
With automatic recovery off, a runtime that crashes mid-turn leaves that turn
open. The next send is refused outright as a conflict while the Session still
reads READY, so chat showed only Retry, which cannot succeed. Tag A2A refusals
that arrive before the first frame and offer Recover for them, as for sends
refused as not accepted. RevertSession leaves a busy, healthy runtime alone.
The transcript offers Recover only for a ready conversation; one that is not
ready has its own alert.

Verified on kind with the flag off: worker deleted mid-turn, the refused send
offers Recover, Recover restores the runtime, and the next message is
answered. Recover during a healthy running turn leaves it running.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
There was a problem hiding this comment.
🤖 AI-generated review
The values.yaml change and the helm-unittest guard look good. A default install no longer renders the key, so a rollback can still read the config. With the flag off, sends keep their old refusals, and TestSendRecoveryDisabled covers all three send paths. The comments below are small.
| source = client.sendStreamingMessage(request, options); | ||
| continue; | ||
| } | ||
| if (!received && !signal?.aborted && a2aRefusal(error)) throw refusedSendError(error, SEND_REFUSED); |
There was a problem hiding this comment.
Optional: this tags every A2A refusal that arrives before the first frame, so chat says the runtime may have crashed for any of them. The reason: "SOMETHING_ELSE" test case expects SEND_REFUSED too.
The case this targets is the open-turn conflict from interactionStoreError. Could the gateway name that refusal in ErrorInfo metadata, as it does for KAGENT_SEND_NOT_ACCEPTED? Then chat could tag only that reason, and other refusals would keep the plain error with Retry. Recover is harmless either way, so this only affects what the user reads.
There was a problem hiding this comment.
Done in 208343c2, and narrowed to open turns in 9d9f5f98. The gateway now names the open-turn refusal KAGENT_TURN_ACTIVE in its ErrorInfo metadata; the code and message are the same as before. Chat offers Recover only for that reason and KAGENT_SEND_NOT_ACCEPTED. Other refusals keep the plain error with Retry.
| // The mock chat client has no A2A push store; hide the control rather | ||
| // than showing a backend error over an otherwise scripted transcript. | ||
| // A conversation that is not ready has its own alert with Recover. | ||
| onRecover={canSend ? () => void recover() : undefined} |
There was a problem hiding this comment.
Small one: the two new props sit between onManageTaskPush and its comment about the mock push store. That comment now reads as if it describes onRecover. Could the new props move above it?
Related: the onRecover doc in ChatTranscript.tsx says Recover is offered when sends are refused as not accepted. It is now offered for outright refusals too.
There was a problem hiding this comment.
Fixed in 208343c2. The new props now sit above that comment, and the onRecover doc lists both refusals that offer Recover.
| import { CheckpointDivider } from "./CheckpointDivider"; | ||
| import { groupByCheckpoint } from "./messageCheckpoints"; | ||
| import { scrollbarStyles } from "@/components/agent/controlStyles"; | ||
| import { isSendNotAccepted, mayNeedRecovery } from "@/api/chat/a2aGrpcChatClient"; |
There was a problem hiding this comment.
Optional: this is the only component that imports from the gRPC chat client. isNotFound and the other error predicates live in ApiError.ts. Could SEND_NOT_ACCEPTED, SEND_REFUSED, isSendNotAccepted, and mayNeedRecovery move there? Then the transcript depends only on ApiError.
There was a problem hiding this comment.
Moved in 208343c2. The reasons and predicates live in ApiError.ts and are exported from @/api, so the transcript no longer imports the chat client.
The gateway now sends reason KAGENT_SESSION_BUSY in the ErrorInfo metadata
when an open turn or a checkpoint holds the Session. The refusal keeps its
code and message. Chat offers Recover for that reason only, so other A2A
refusals keep the plain error with Retry.

Move the send-refusal reasons and predicates to ApiError, beside isNotFound,
so the transcript depends only on @/api. Keep the push-store comment beside
the prop it describes, and document every refusal that offers Recover.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>
| req.Config = &config | ||
| } | ||
| id, err := s.reserveDispatch(ctx, session.Id, initialID) | ||
| if s.automaticRecovery && errors.Is(err, database.ErrConflict) { |
There was a problem hiding this comment.
ErrConflict here also covers a checkpoint in CREATING and a Session that isn't READY, so healthy Sessions call Revert (and GetActor) too. And if that Revert fails with Unavailable or Aborted, the caller gets ErrSendNotAccepted in place of the busy refusal, so a Substrate outage turns a definitive "busy" into a retry loop.
Can we fall back to the original refusal when recovery isn't available, like the unauthorized case already does?
There was a problem hiding this comment.
Fixed in 9d9f5f98. Only an open turn starts recovery now. The store reports it as ErrActiveTurn, which is still an ErrConflict, so a checkpoint in progress or a Session that isn't READY keeps its refusal without a revert. If the revert can't run (outage, contention, or no update access), the send gets the same busy refusal as before, not ErrSendNotAccepted. A gateway test covers the outage case.
| if err != nil { | ||
| return err | ||
| } | ||
| if err := s.recoverRuntime(ctx, session.Id); err != nil { |
There was a problem hiding this comment.
Small one: PrepareSend falls back to the original refusal on ErrUnauthorized, but this path and the admitted path in resolveSend return permission denied, even for a transient not-accepted send on a healthy runtime, because Service.Revert authorizes before it checks health. The built-in authorizer grants create and update together, so it needs a custom authorizer to show up, but can the three be consistent?
There was a problem hiding this comment.
Done in 9d9f5f98. All three paths now share one helper and handle a failed revert the same way. If no recovery is admitted, the send gets the answer it would give without recovery. If one is admitted, it gets the new recovering answer. Missing update access is one of those cases, so none of the paths returns permission denied for it any more.
| // outages answer ErrSendNotAccepted, so the caller retries. The revert outlives a | ||
| // caller that disconnects, so a retry finds it finished. | ||
| func (s *InteractionService) recoverRuntime(ctx context.Context, sessionID string) error { | ||
| _, err := s.sessions.Revert(context.WithoutCancel(ctx), sessionID) |
There was a problem hiding this comment.
finishSend bounds its context to 5s, but WithoutCancel drops that deadline, and workflow.Revert then runs under the 2 minute RuntimeOperationTimeout. So a send can wait ~2 minutes before it answers, on all three paths. Is that intended?
I think the send should either answer "retry" once recovery is admitted and let the revert finish on its own, or have an explicit bound.
There was a problem hiding this comment.
Not intended. Fixed in 9d9f5f98: a send now waits at most 10 seconds for the recovery it starts. If the revert isn't done by then, the attempt releases its claim and the send answers that the runtime is recovering. The client's next retry continues the admitted recovery, so nothing keeps running after the request ends.
| if err := s.recoverRuntime(ctx, session.Id); err != nil { | ||
| return nil, err | ||
| } | ||
| return nil, ErrSendNotAccepted |
There was a problem hiding this comment.
During recovery the client gets KAGENT_SEND_NOT_ACCEPTED with retryAfterMs: 100, the same as an ordinary busy dispatch, so it can't tell "we're reverting, come back shortly" from "busy".
Can we return a separate reason for it, e.g. KAGENT_RUNTIME_RECOVERING, with a retryAfterMs in seconds? The UI could show "recovering" from that directly, and A2A clients get the signal without calling GetSession.
There was a problem hiding this comment.
Added in 9d9f5f98, but as metadata rather than a new reason. reason stays KAGENT_SEND_NOT_ACCEPTED, and the error adds state: RECOVERING and retryAfterMs: 1000. The CLI, the e2e helpers and enterprise's SendMessageWithRetry only retry on that exact reason, so a new reason would make recovery a hard failure for clients that are already released. Chat already shows "recovering" from the Session while it retries, and now also says so if its retry window runs out.
| @@ -50,39 +57,63 @@ func (w *ActorWorkflow) observeCrash(ctx context.Context, session *apiv1.Session | |||
| TemplateAtespace: generation.TemplateAtespace, TemplateName: generation.TemplateName} | |||
| actor, err := w.actors.GetActor(ctx, binding.Atespace, binding.Name) | |||
| if status.Code(err) == codes.NotFound { | |||
There was a problem hiding this comment.
Question: one GetActor NotFound marks the Session FAILED for good and fails every open task, including ones waiting on input. Can Substrate ever return NotFound for an Actor that still exists, e.g. while it's restarting? I didn't find a case, but since there's no way back from RuntimeLost I want to make sure a single observation is enough.
There was a problem hiding this comment.
One observation is enough. In Substrate v1.0.0, GetActor is a primary-key read of ate-api's own PostgreSQL actors table (cmd/ateapi/internal/store/atepg/actor.go), with no cache in between. Crashes, restarts, suspends and reverts all update that row. Only DeleteActor removes it, and it refuses while a worker still holds the Actor. The atespace foreign key is ON DELETE RESTRICT, so no cascade removes it either. A database error comes back as Internal, not NotFound.
| reverted, err := fixture.sessions.RevertSession(fixture.ctx, request) | ||
| _, next := newMessageRequest(t, "What is 2+2?") | ||
| next.Tenant, next.Message.ContextId = fixture.tenant, fixture.sessionID | ||
| answered, err := sendMessageWithRetry(fixture.ctx, fixture.client, next) |
There was a problem hiding this comment.
This crashes mid-turn and sends, so it only exercises the conflict path in PrepareSend. RecoverRejectedSend through finishSend has no e2e.
The rename also dropped the e2e for an explicit RevertSession on a crashed runtime, which is what the new Recover button calls; it's now only called on a healthy runtime. Can we keep that case as its own test?
There was a problem hiding this comment.
Restored in 9d9f5f98. TestSessionRevertCrashedRuntime is back as its own test. It calls RevertSession on the crashed runtime, including a retry after a lost response, and sits beside the send-recovery test; they share a crash helper. Both kagent subtests pass on kind with the flag on.
I couldn't add a reliable e2e for RecoverRejectedSend. It needs a crash after the dispatch is reserved but before the runtime saves the input, and a test can't time that. Gateway unit tests cover it.
Recover on send only for an open turn. ReserveSessionDispatch now reports one
as ErrActiveTurn, which still matches ErrConflict, so a checkpoint in progress
no longer triggers a revert. The open-turn refusal's reason is renamed from
KAGENT_SESSION_BUSY to KAGENT_TURN_ACTIVE; its code and message are unchanged.

All three send paths share one helper. It waits at most 10 seconds for the
revert; a cancelled attempt releases its claim, so the client's retry continues
the admitted recovery. If the revert cannot run, whether for missing update
access, contention, or an outage, the send keeps the answer it gives without
recovery. If a recovery is admitted, the send answers ErrRuntimeRecovering.
That error keeps the KAGENT_SEND_NOT_ACCEPTED reason, so existing clients still
retry, and adds state RECOVERING and a one-second retryAfterMs. Chat reports
it when its retry window runs out.

Restore the e2e test for an explicit RevertSession on a crashed runtime, beside
the send-recovery test, using a shared crash helper. Both kagent subtests pass
on kind with automatic recovery on.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: Ada Lundhe <adalundhe@lundhe.audio>


Builds on #3395, now merged; rebased onto main.
Recover crashed runtimes during A2A sends when
config.sessions.automaticRecovery: true. The setting defaults tofalse. The chart only mentions it in a comment, so a default install renders the samecontroller.yamlas before and a rollback to v1.0.0 can still read it.The flag controls joining an admitted recovery, recovering a send refused for an open turn, and reverting after a proven unaccepted send. A send waits at most 10 seconds for recovery; a recovery still running is answered
KAGENT_SEND_NOT_ACCEPTEDwithstate: RECOVERING, and the client's retry continues it. If recovery can't run, the send keeps the answer it gives without recovery. With the flag off, sends keep their existing refusals. ExplicitRevertSessioncalls remain available.Missing or replaced runtimes are recorded as FAILED/NONE with reason
RuntimeLost. These persistence changes apply with either flag value. The flag does not control migrations, schema, or stored data.Chat reads recovery status from stored Session state. It retries
KAGENT_SEND_NOT_ACCEPTEDbefore the first stream frame, with the same message ID. The wait doubles fromretryAfterMsup to 2 seconds, within a 30-second window. Chat offers Recover, which callsRevertSession, in three cases: when the window runs out; when a send is refused for an open turn (KAGENT_TURN_ACTIVE), which is what a mid-turn crash produces with the flag off while the Session still reads READY; and while a recovery is pending. A recovery whose attempt failed stays FAILED/REVERT until a client retries it. Recover returns a healthy runtime unchanged and records a lost one. Session reads do not query Substrate.Validation:
min(cores - 1, 8)); the default oversubscribed large machines and made heavy page tests time out. Three consecutive full runs pass, 846/846.🤖 Generated with Claude Code